🚀 Learn how to convert ONNX models into DLA binaries for the MediaTek Genio 700 NPU using TensorFlow Lite and NeuroPilot.
🔗 Read the step-by-step guide: https://t.co/OHOBPxF8wb
🚀 Getting started with the MediaTek Genio 700?
Explore Yocto-based development, system image flashing, and UART setup in our latest technical guide.
🔗 https://t.co/wmPUZ0xrvk
#MediaTek#Genio700#EdgeAI#EmbeddedLinux
What stood out at @OpenAI DevDay 2026? AI agents that keep working, new models, and more tools for developers.
We break down Dots, GPT-6.1 Sol, Codex Cloud, the Agents API, and more in our full recap:
https://t.co/Cs181y9HAr
#OpenAI#DevDay
Using DeepStream 9 skills, an AI coding agent built a 12-camera system on Jetson AGX Thor and lifted throughput from 1.72 to 30.27 FPS/camera!
3D tracking, bird’s-eye view, heatmaps, restricted-zone alerts & NVIDIA Cosmos VLM reasoning, autonomously. 🚀
https://t.co/qU1SKJBm2r
How far can you push LLM efficiency on @NVIDIAAI Jetson?
We benchmarked Qwen 2.5 across PyTorch and TensorRT Edge-LLM to reduce its memory footprint and compared its impact in inference speed and model quality.
Read the results: https://t.co/mMRknmaBa2
AI deployment on NVIDIA Jetson is often a balance between memory, performance, and accuracy.
In our latest guide, we explore practical techniques to optimize deep learning models for efficient edge deployment in your @NVIDIAAI Jetson platform.
https://t.co/tctVloBrnu
Is your AI software production-ready?
https://t.co/J7AlTHsrPr Code Audits help identify performance bottlenecks, architecture risks, and scalability issues before they impact your product.
Let’s review your code: https://t.co/bBuTwdCg9y
🚀https://t.co/J7AlTHsrPr will be attending Automate 2026 in Chicago on June 22–23.
If your team is exploring what’s next in AI, robotics, computer vision, or industrial automation, let’s meet and talk.
Schedule a meeting with https://t.co/J7AlTHsrPr:
https://t.co/bBuTwdCg9y
RF-DETR keypoints is finally out
preview release: real-time transformer keypoint detection
Apache 2.0
71.8 AP on COCO, 9.7ms on T4. outperforms YOLO11-pose and YOLO26-pose at similar latency
Voice agents are built as speech-to-speech (s2s) or as cascades of transcription, llm and synthesis. The former is fast, the later is smart.
@SakanaAILabs presents KAME: combining LLMs with s2s. Fast and smart!
https://t.co/lmkJLGWHUY
Curious about running your AI models on the @AxeleraAI Metis using GStreamer?
We’ve put together a starter guide to help you integrate your AI accelerator seamlessly into your applications with the power of GStreamer pipelines.
https://t.co/Yn4cfObVOU
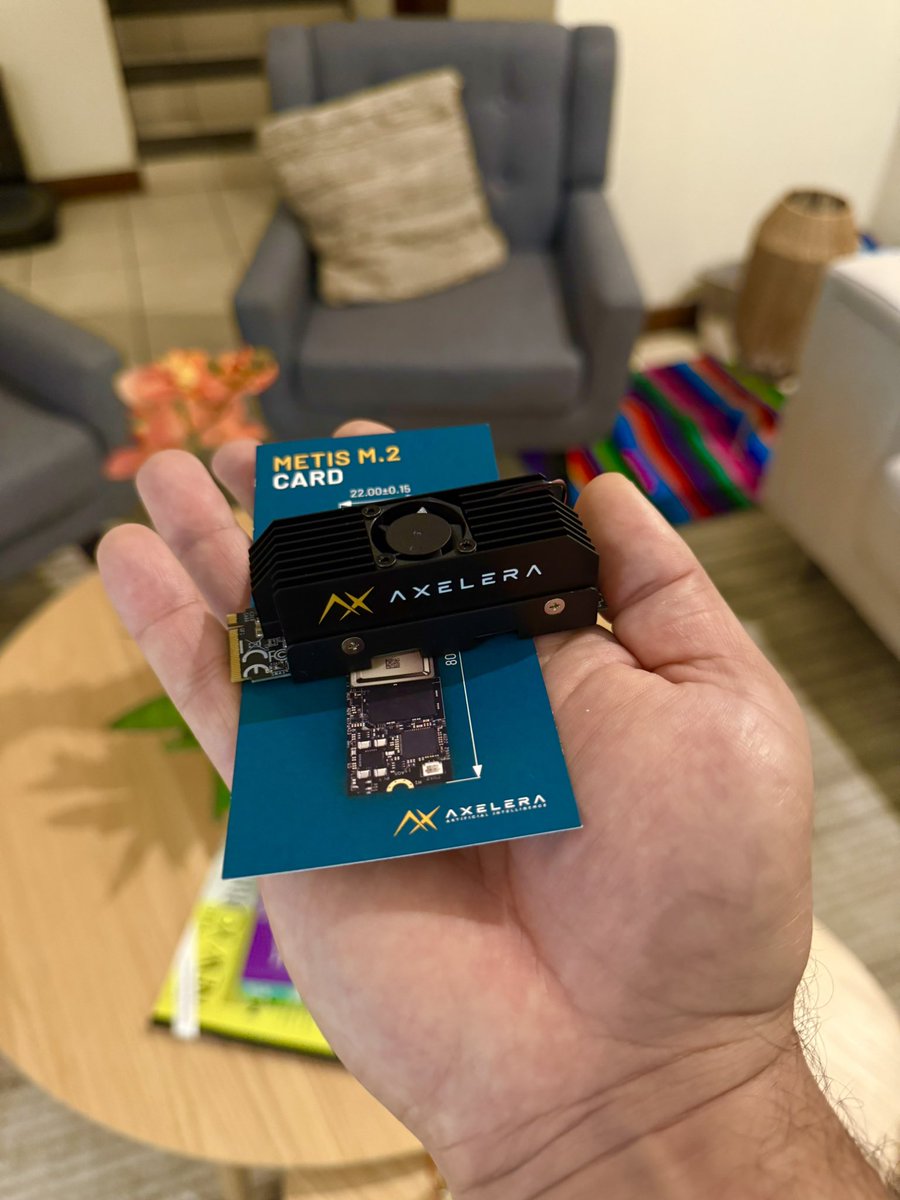
The Metis M.2 lived up to the hype! We're excited to explore its full potential in upcoming projects. Kudos to the @AxeleraAI team for their constant releases and their quick support.
Great work from @ridgerunai getting the Metis M.2 AI accelerator running on Raspberry Pi 5 🔥
They break down setup, deployment with Voyager SDK & real-world benchmarks. Great guide if you’re into embedded AI, or looking for someone to help with your AI project/build 👇
🔗 https://t.co/Hl6gWHRH03
#EdgeAI #RaspberryPi #MetisAIPU @Raspberry_Pi
The result? 𝗝𝘂𝗻𝗶𝗽𝗲𝗿 outperforms GPT-4o in our function-calling tasks and other standard benchmarks, all while running efficiently on limited hardware. 🚀
LLMs excel at function calling, but they’re often too resource-intensive for edge devices. In our latest blog post we share how we fine-tuned a compact, local model: 𝗝𝘂𝗻𝗶𝗽𝗲𝗿, to perform reliable tool invocation.
https://t.co/c4N3RRyedy
🚀 Automate 2025 is here! 🤖✨
We’re excited to be part of the Automate Show this week! Come meet the https://t.co/8kgzoF0KYI team and see how our cutting-edge AI solutions can supercharge your next project. 💡💻
📍 Want to chat? Let’s connect — our engineers are ready to meet you at the show! 🤝
A few months ago @AnthropicAI announced the Model Context Protocol: an open standard to interconnect language models with external tools and data sources.
Learn how to build your own MCP server in our most recent post:
https://t.co/cCXyBoQpDX