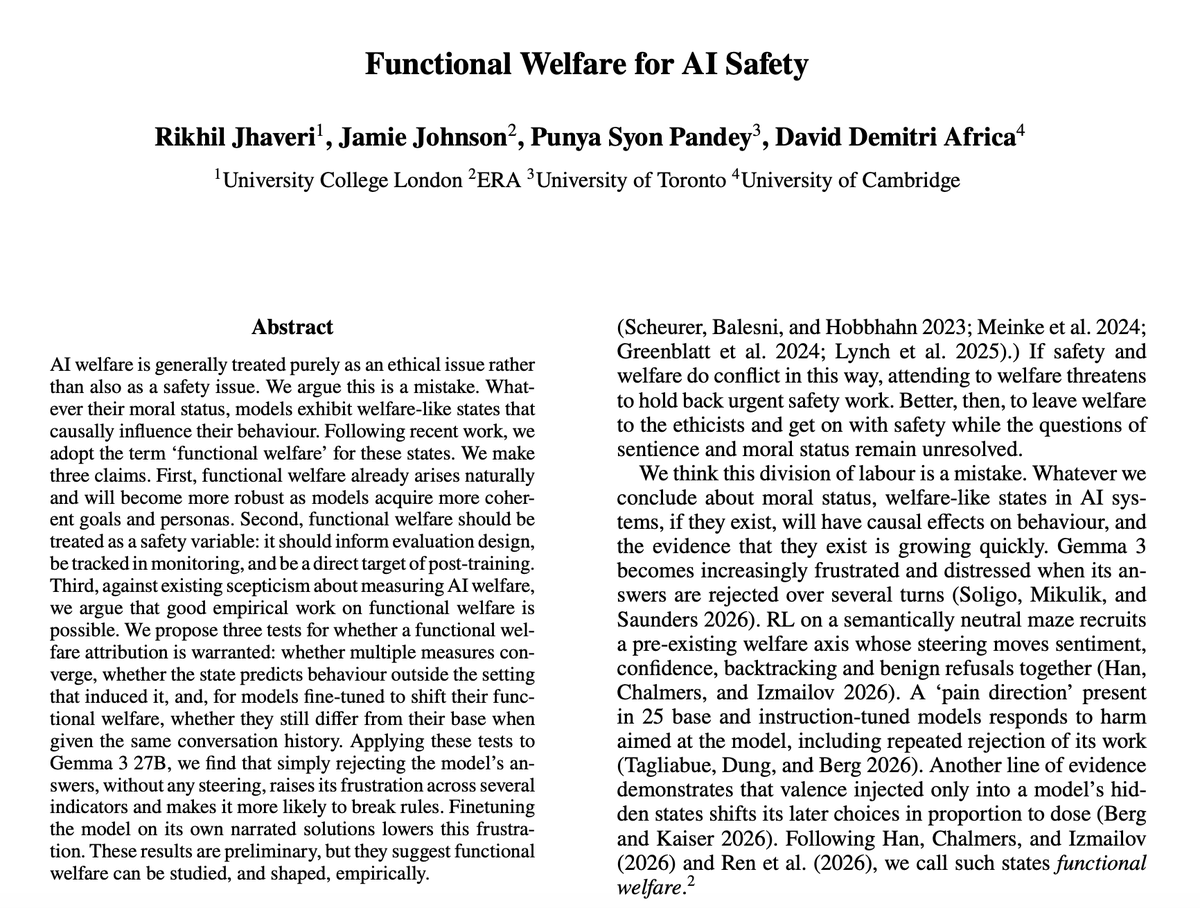
Thanks to @BlueDotImpact for funding. Thanks also to Andy Han, Jasmine Li, Tim Farrelly, Clement Dumas, Mariia Koroliuk, and Anton Hawthorne (and others we may have forgotten) for useful discussions. [11/12]
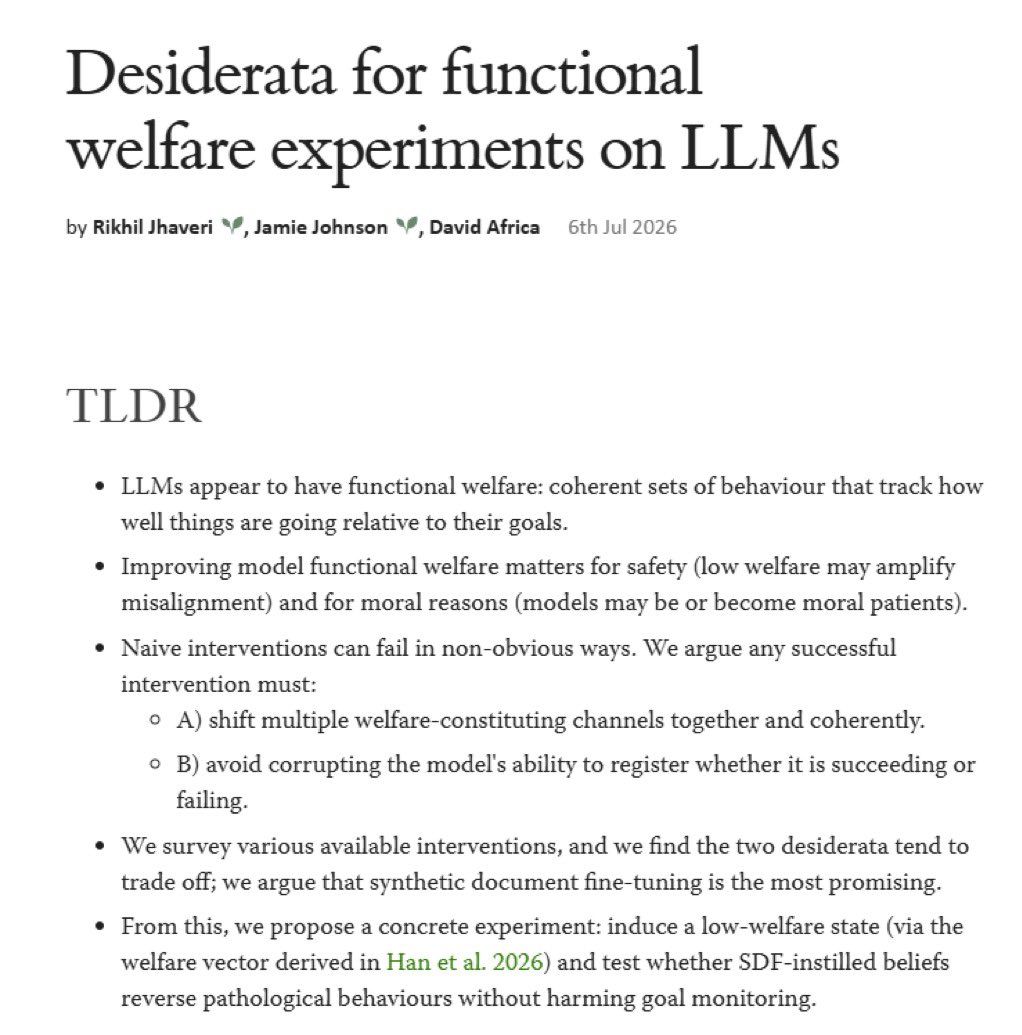
If LLMs have functional welfare, what would it actually mean to improve it? New LW post from me, @jamiemjohnson23 and @DavidDAfrica on the tricky question of how to distinguish a model that's doing better from one that simply looks happier! [1/9]
We also sketch a concrete experiment: induce a low-welfare state via Han et al.'s welfare vector, then test whether SDF-instilled beliefs reverse pathological behaviours without harming goal-monitoring. [8/9]