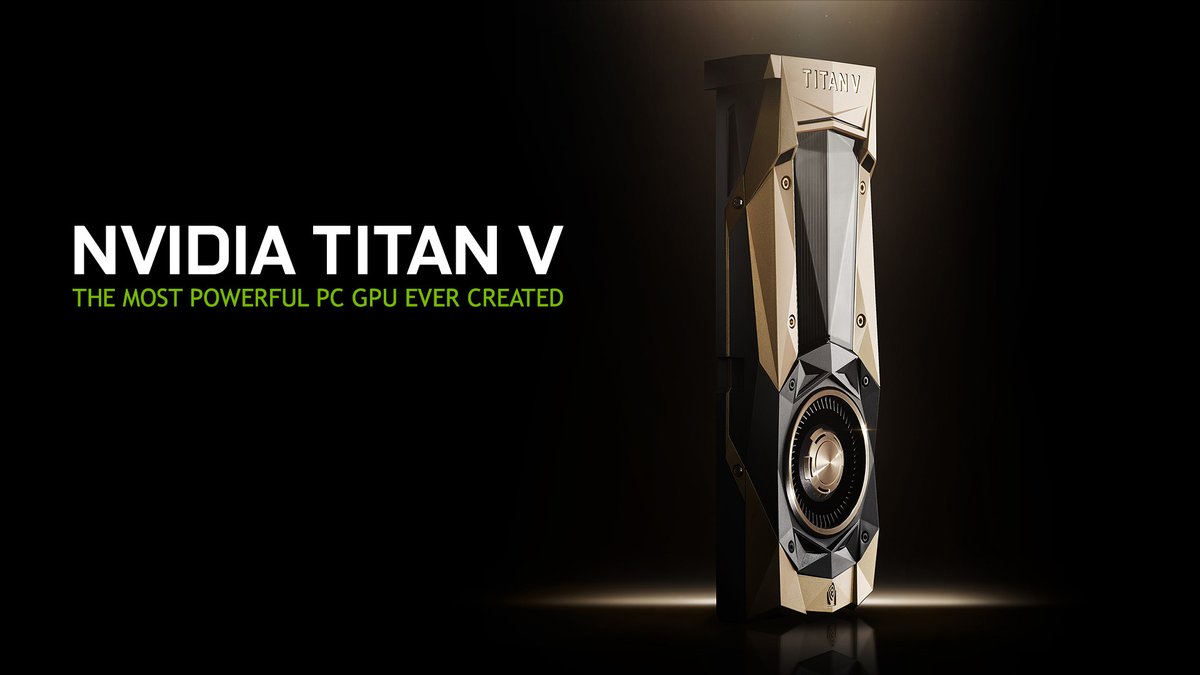
@PinMarek87204@chrisramsay52 Broo video is older than AI chips. (tensor cores) First AI capable chip is nvidia pascal Titan V. Realease date 2017.
First stable diffusion (first scaled diffusion) checkpoint is from 2022. (image 2 is stable diffusion generated image not great right.)
@ORameshO@eternityspring Each step 100s 800s for 8 step I think resolution should be 1024x1024 and lenght should be 8 second (I am not sure about resolution and lenght of video). Speed is good but quality really depends on checkpoint quant. Dont recommend w4a8. Use w6a8 on comfy repo or larger.
@ORameshO@eternityspring Sorry for intel users comfyui is not supporting --enable-dynamic-vram flag.
I tested amd (rx 9060 xt 16gb) nvidia (rtx 3050 6gb) and intel (b580 12gb). I can run larger models on rtx 3050 but intel gives oom error.
Intel driver update coming according to my gemini argon agent.
@ORameshO@eternityspring if you have amd or nvidia 16gb vram with --enable-dynamic-vram flag fits on vram. This is just lora and you can find smaller comfy lora of alibaba loras (converted to comfy compatible).
I really dont remember speed but speed wise same as any 8 step turbo lora.
Tawus Local AI Get It on Google Play Store:
https://t.co/1kCz8Ctkat
New 1.1 Update Available Now on Google Play Store
#mobileai#mobilelocalai#localai#llm#llmandroid
Video created thanks to DS Harness, Qwen 3.8 Flash Next, Minimax H3 and Qwen Image 2.1 AI models on localy.
@cryptoanon69@vinicioslc@someRandomDev5@Biggest Do you really suggest that 56gb model is better than 360gb model in same generation? Math is not mathing.
Smaller execution with more knowladge. I am using for game dev so AI should know more things like Game Engine, 3D, 2D, Genres, Pop Cultre, Mthyology and many more.
@vinicioslc@someRandomDev5@Biggest Tell me 9b AI model better than Qwen 3.6 35b.
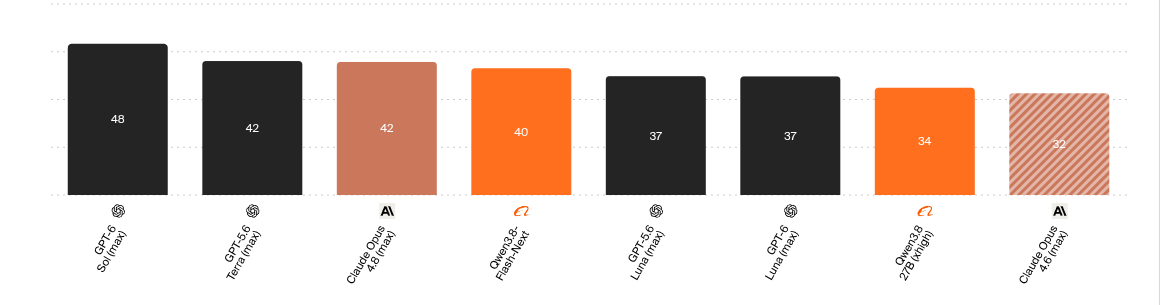
Remember Qwen 3.8 flash next is 180b (50b ngram, 4b drafter head, 125b real inference) parameter model only 6b active and much better than qwen 3.8 27b, GPT 5.6 Luna. On par with GPT 5.6 Terra.
Your hypothesis was dead on arrival.
@someRandomDev5@shamaz89720417@Biggest I already have 2 more gpu. RX 9060 XT 16gb and B580 12gb. Still most people need 35B for faster inference. I making games and some times I need fast mutlimodel llm to create me automated game assets with ComfyUI mcp. So your take is out of touch.
@shamaz89720417@someRandomDev5@Biggest I can even run IQ3_XXS with 60k context on rtx 3050 6gb. Some people trying to offload all expert on the vram. Just dumb thing to do.
@haz0a@satgeze@Youssofal_@AnthropicAI If you don't know Freetoken you can run qwen 3.8 flash next on really mediocre pc with really decent speed (20~ t/s).
@haz0a@satgeze@Youssofal_@AnthropicAI Qwen 3.8 released 2 month ago and already we are getting Qwen 4 dipshit. Qwen 27b is smallest model on the line up. There is Qwen 35b a3b and qwen flash around 180b parameter terra level model. I bet qwen 4 flash gonna be GPT 6 Terra (branded as Sol) level.