Meet Wally.
Our inference stack for open frontier models, built to be the fastest place to run them.
Performance snapshot:
GLM-5.3 Flash: 380 tok/s.
GLM-5.3 Max: 790 tok/s
Qwen3.8-27B: 485 tok/s
DeepSeek-V4.1 Flash: 615 tok/s
1/7
Introducing the new Wally model catalog.
7 new open models, live now:
- Kimi K3
- DeepSeek V4 Pro (Fast)
- GLM-5.3 (Fast)
- MiniMax M3
- DeepSeek V4.1 Flash (Fast)
- DeepSeek V4.1 Flash 1017
- DeepSeek V4 Flash 0731
10 models. One API key.
Wanna see something crazy this kind of speed gets you?
DeepSeek-V4.1-Flash recreating entire webpages from scratch the moment you hit enter.
Yep, the website is fake. The LLM generates it in seconds from the URL.
Agreed DeepSeek-v4.1-flash is an amazing model.
and we fixed the speed, it runs at 615+ tok/s on Wally
here it is against DeepSeek's own api making changes to the 2048 game -:
Steam reviews are a war zone. I’m not reading all that 📷
So we put DeepSeek V4.1 Flash on Wally and asked it what players were actually complaining about.
Less scrolling. More answers.
Agreed DeepSeek-v4.1-flash is an amazing model.
and we fixed the speed, it runs at 615+ tok/s on Wally
here it is against DeepSeek's own api making changes to the 2048 game -:
Deepseek is an incredible small model
- sonnet level performance
- 10x cheaper
- very engaging personality
It’s only drawback is speed which the team are fixing.
🚨A new tier of frontier models dropping VERY soon.🚨
And yes, we're launching a special FAST mode for those who want warp speed. ⚡
We just got a LOT more compute. Stay Tuned!
You think the open models you use right now are fast?
Try them on Wally.
Sketch an app in tldraw, hit Make Real, and DeepSeek V4.1 Flash has it running before you let go of the mouse. Crazy fast.
Letss go! DeepSeek V4.1 Flash-1017 is the best open model for web dev, and it runs at 615 tok/s on Wally(@RunAnywhereAI).
we gave it the live Hacker News front page and it redesigned it as if Apple made it, then as a 1999 GeoCities page and it was built instantly.
DeepSeek V4.1 Flash on Wally now runs the 1017 weights, so I tested it on a real game.
Ten plain-English changes to Hextris, each one showing up as it played.
At 615 tok/s this is how things get built now. No mindless scrolling while your AI works. You type, it's done, iterate.
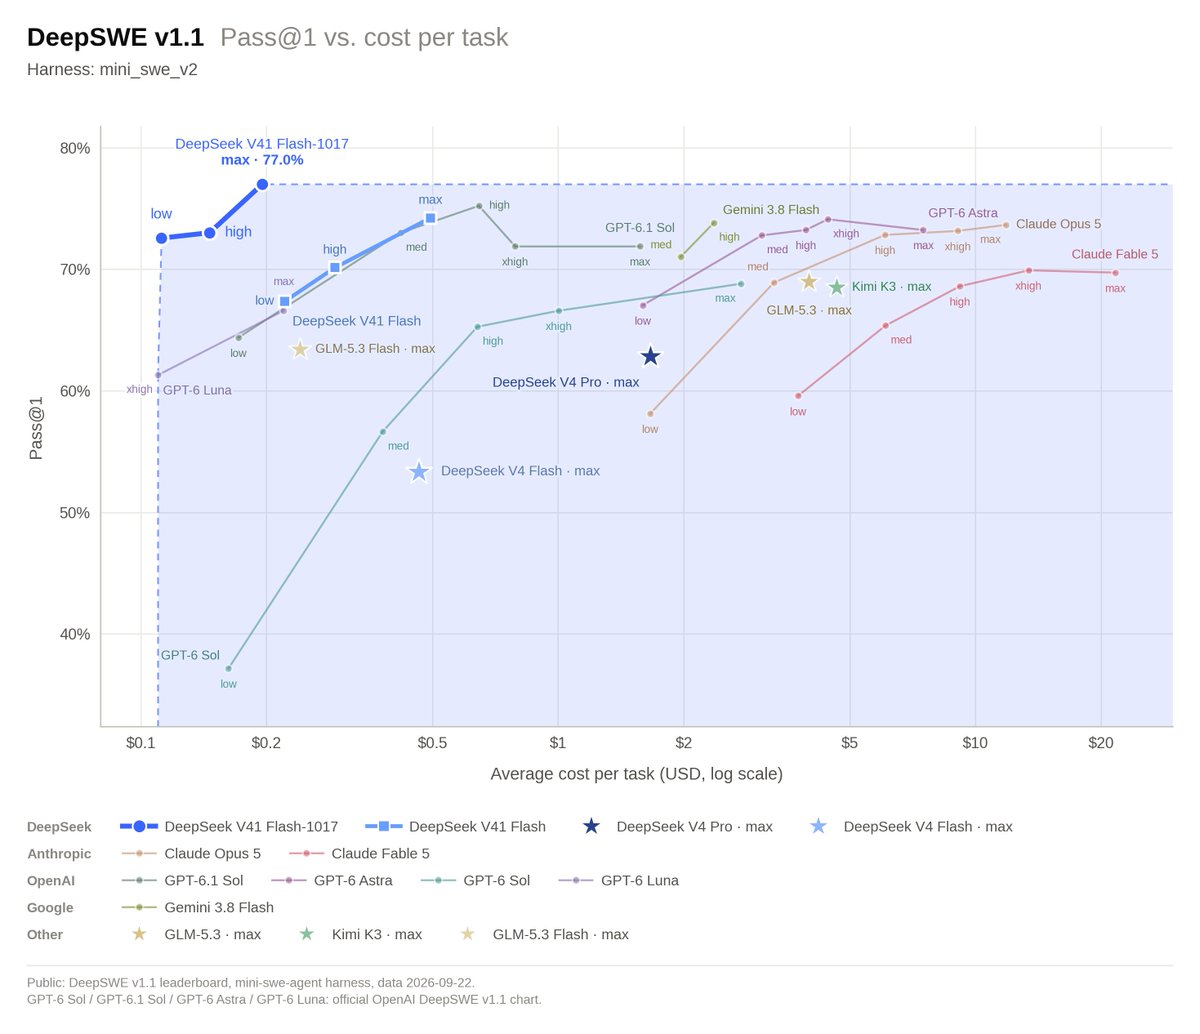
DeepSeek V4.1 Flash on Wally is now upgraded to 1017.
- 77% on DeepSWE, up from 74.2%
- ~$0.20 per task, down from ~$0.50
- Shorter outputs, so tasks finish sooner
At 615 tok/s. Same model id, nothing to change on your side.
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Everyone's shipping speed now.
Model quality is hitting diminishing returns. A 3-point benchmark lead is a vanity metric you can't feel in real work.
Speed you feel on every prompt. Might as well run models where they're actually the fastest 🏎️ @RunAnywhereAI