AI can write a function. But can it survive a real coding task? 💻
We built two benchmarks:
• QwenClawBench: 100 real-user tasks, 8 domains
• IndustryCode: multilingual, multi-domain industrial code generation
29 models evaluated · 679 samples tested.
#AI#LLM#Coding
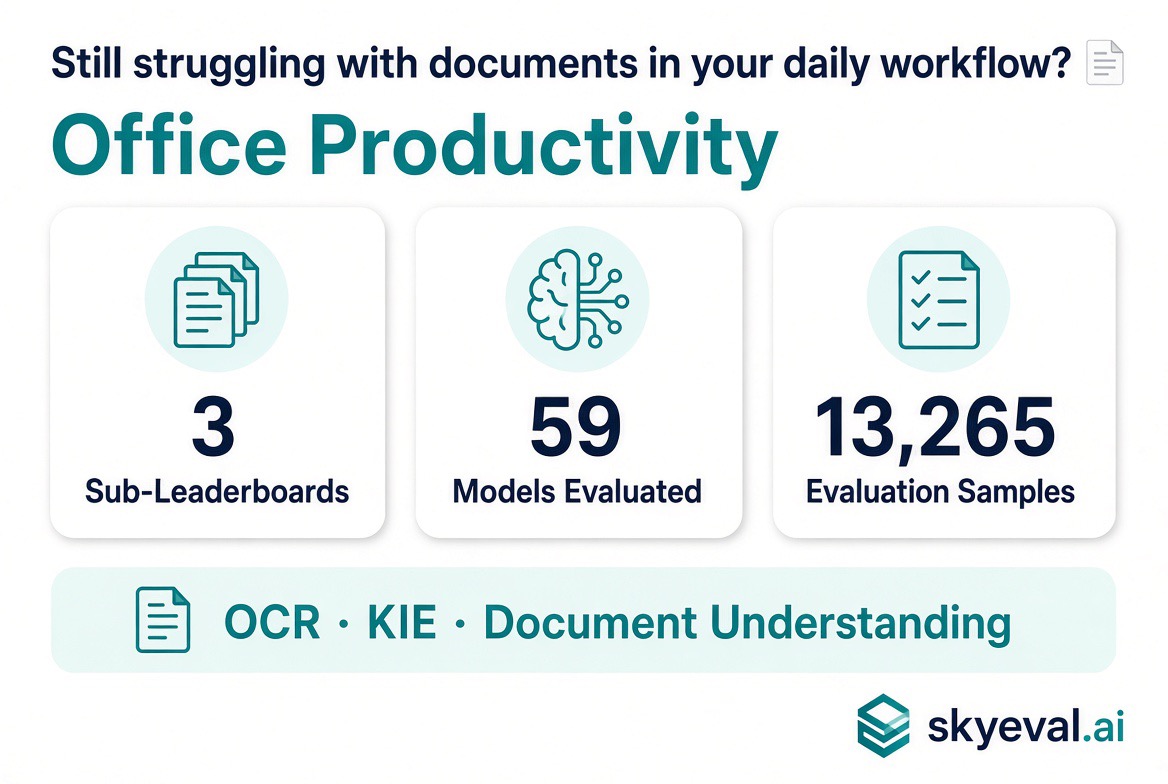
Still struggling with documents in your daily workflow? 📄
We built the Office Productivity track on SkyEval:
• 3 sub-leaderboards covering everyday document scenarios
• 59 models evaluated
• 13,265 evaluation samples
It focuses on practical office tasks — OCR, key information extraction, document understanding, and end-to-end processing of real documents.
The goal: see how well models handle the documents people actually work with every day. 🔍
Full methodology: https://t.co/fSKRYI6MY0
#AI #OfficeProductivity #DocumentAI
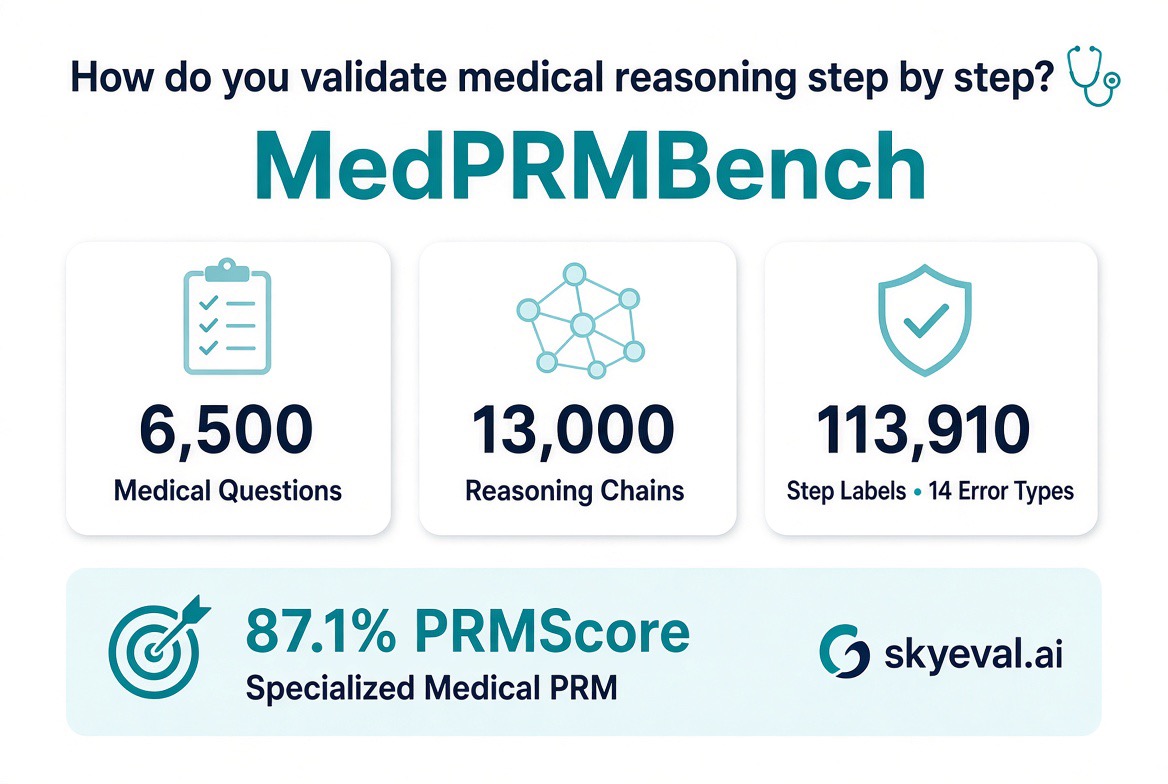
How do you validate medical reasoning step by step? 🩺
We built MedPRMBench on SkyEval:
• 6,500 medical questions
• 13,000 reasoning chains
• 113,910 step labels across 14 error types
It focuses on step-level validation of medical reasoning processes — catching errors in diagnostic and treatment logic as they happen.
The goal: test if models can reliably verify medical reasoning, step by step. 🔍
Full methodology: https://t.co/fSKRYI6MY0
#AI #MedPRMBench #Healthcare
Looking for the best AI video model for your next project? 🎥
We tested T2V (10 models) and R2V (8 models) on FilmBench.
The top 3 don't change across tasks:
#1 Seedance 2.0
#2 MiniMax H3
#3 Happy Horse 1.1
Full leaderboard: https://t.co/3WIfY7BFdo
#AI#VideoGen#FilmBench
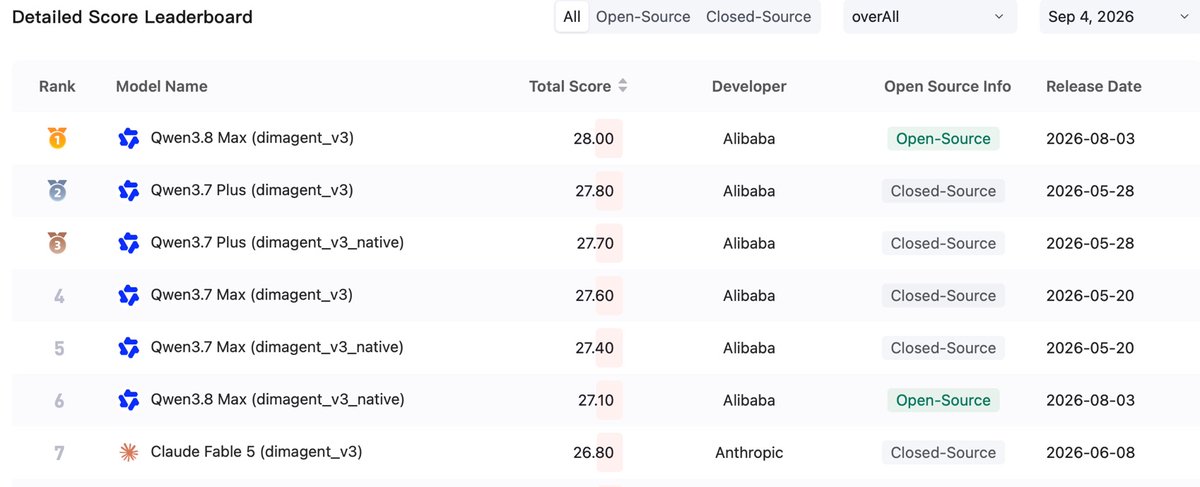
Which AI has the best "research taste"? 🧠
We tested 10 models on 300 samples.
Overall top 6: all Qwen.
Claude Fable 5 at #7 (26.80).
Qwen3.8 Max leads (28.00).
A clean sweep. 👀
#AI#LLM#Qwen
Why is the Instruction Following top 3 all Claude & GPT? 🔍
202 multi-constraint prompts. 6 task types.
41 models. Average score: 63.7. Top: 75.8.
They win by actually following the rules — not just by sounding smart.
Full methodology in comments. 👇
#AI#LLM
Why is the Hallucination top 3 all Gemini ? 🔍
400 samples. 34 models.
Average score: 55.47. Highest: 73.29.
That's why Gemini sweeps — it hallucinates the least, not because it's the smartest.
Full methodology in comments. 👇
#AI#LLM
Is smarter AI actually safer? 🧠
We evaluated 75 models on safety & trustworthiness.
Hallucination top 3: all Gemini.
Instruction following top 3: 2 Claude & 1 GPT.
Zero overlap. ��
#AI #LLM
🌐 SkyEval, All in One Place
Leaderboards to compare. Arenas to test. Benchmarks to measure. News and papers to stay current. Open-source tools to go deeper.
One platform. A clearer view of what AI models can do.
https://t.co/76AARrf8Lt
📰 Explore SkyEval News & Daily Paper
News tracks model launches, tech updates and evaluation analysis.
Daily Paper organizes frontier research across reasoning, agents, multimodal, safety and embodied AI.
https://t.co/X1Yf9Enba6
Benchmark Spotlight: From General to Domain-Specific AI
🌐 From visual creation to complex reasoning:
🎨 Qwen-Image-Bench: text-to-image
🎬 FilmBench: professional video
🧮 ReasoningMath-MM: multimodal math
🩺 MedPRMBench: medical reasoning
https://t.co/J9jFKexeSF
🧭 Five Arenas. Five Ways to Evaluate AI.
🌍 Happy World: perception & simulation
⚽ Sports: predictions vs. real results
🧩 Application: strategy & task outcomes
📊 Data: dataset comparison
💬 Chat: blind user voting (coming soon)
https://t.co/Omm3AeBIp1
🎯 Inside SkyEval Arenas
Beyond static benchmarks, SkyEval evaluates AI models through real-world tasks—revealing how they perceive, predict, reason and act.
Explore five arenas:
🌍 Happy World
⚽ Sports
🧩 Application
📊 Data
💬 Chat (coming soon)
https://t.co/xbVpnvT32C