We believe voice is the most natural way to interact with intelligence, so we created Dessa, the most authentic full-duplex speech model ever built. Talking with it feels like talking with a person…full of emotion, nuance, pauses, and a natural cadence.
https://t.co/r0qFLdvd6c
Imagine building lightweight, fast, and accurate AI models tailored to a client’s exact needs, deployed locally, fully under their control, and without the massive infrastructure costs.
AI doesn’t always need to be bigger. Sometimes, it just needs to be built for the job. 🚀
A small win and a first step.
I am a believer in local AI. The documents that run a bank, a hospital or a ministry should be read where they live, not uploaded to someone else’s servers to be understood.
At Providus we have been building the intelligence layer on top of our clients’ documents and workflows. To do that properly, we started training our own models.
The first one is out: providus-vl-mini. It reads a page and turns it into structured data, runs on your own hardware, and is free and open for anyone to use.
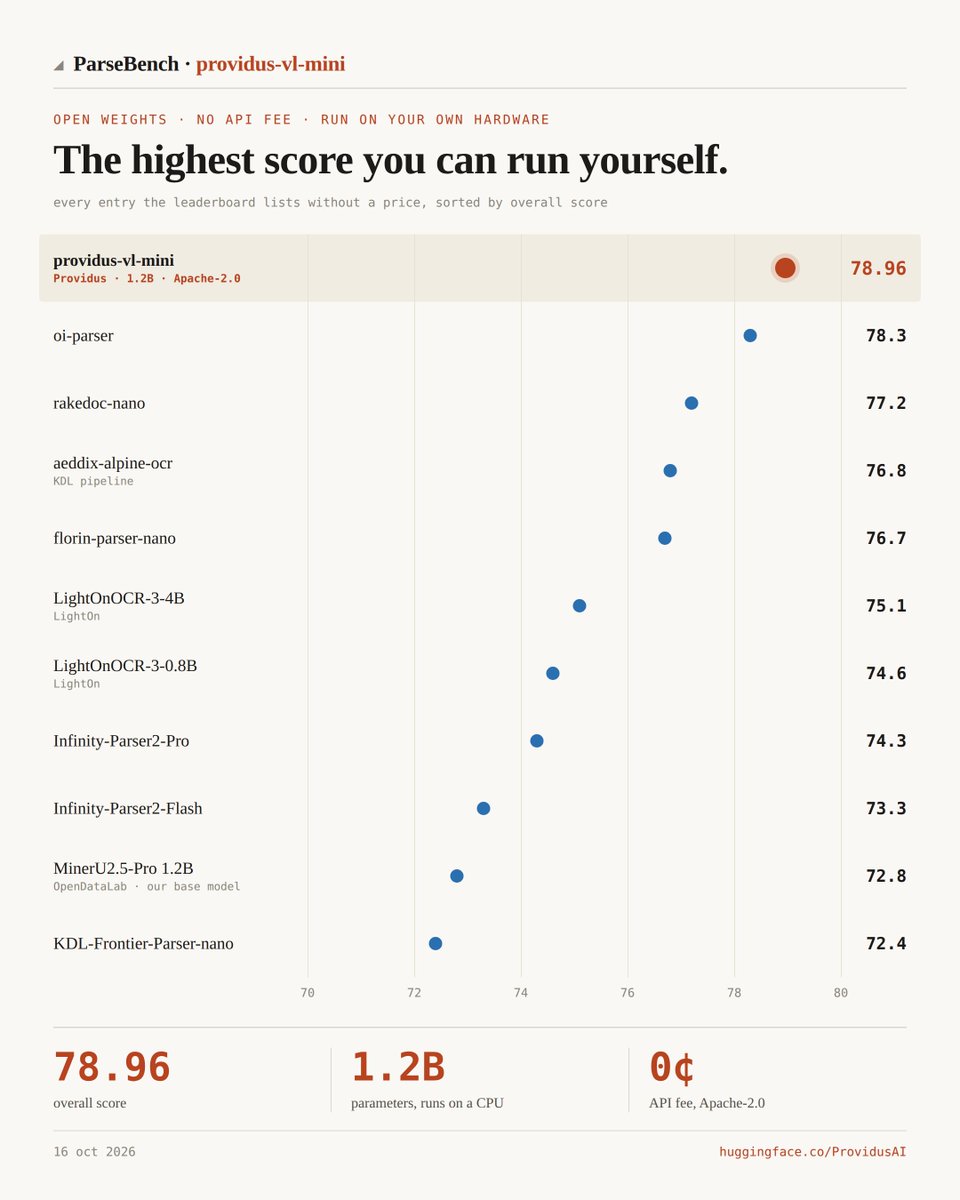
On ParseBench, the public document parsing benchmark, it scores higher than the document services from Microsoft, Google and Amazon. We ran the benchmark ourselves and have submitted the result for public listing.
@SamiHKX and the team built it on MinerU 2.5 Pro from OpenDataLab.
If your documents cannot leave your building, I would like to hear what your team still reads by hand.
Happy to release #1 OS, Parsing AI
Providus-vl-mini: a document parser with 1.2B parameters and open weights (Apache-2.0)
78.96 on ParseBench, mean of 4 full runs (±0.04). On the leaderboard (b9ba246) that would place it first among open-weight models.
https://t.co/ngVXu8gyzc
Built on MinerU2.5-Pro by @OpenDataLab_AI. Scored with ParseBench by LlamaIndex. Thank you both.
Developers: what would you build with a parser that never leaves your machine?
Enterprises: DM me for a trial deployment on your own hardware.
It fits on a laptop. In LM Studio it is one command:
lms get https://t.co/F9vODitnzg
About 30 seconds a page on a laptop CPU, faster with a GPU. Also runs in llama.cpp and Ollama.
Among models you can download and run yourself, it would place first on the leaderboard (b9ba246, 2026-10-12) with 78.96. The next one, rakedoc-nano, scores 77.23.
Four companies have entries above us on ParseBench. All four sell a hosted API, billed per page.
"providus-vl-mini" runs on your own hardware with zero per-page fees.
Why we built it?
Our clients are banks, ministries and hospitals in the Gulf and the EU.
Their documents often can't leave the building, but the most accurate parsers are hosted APIs. We wanted one they could run themselves.
🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
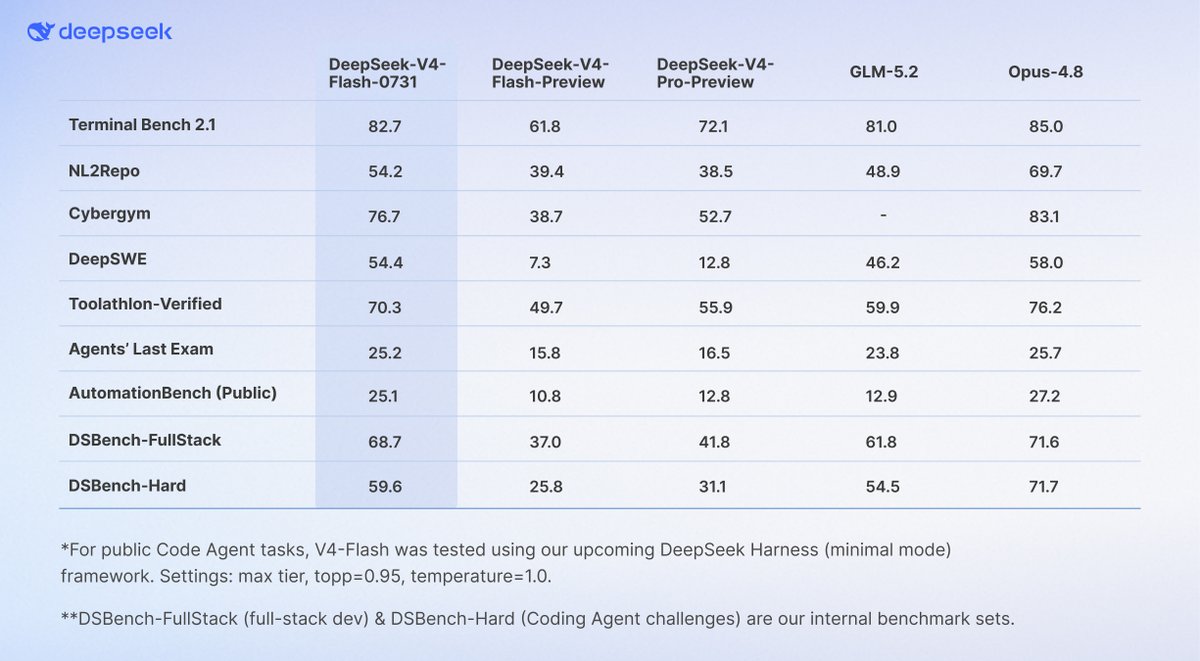
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: https://t.co/smCwQZMeiq