A HELICOPTER CREW DROPPED AN ICE WOMAN INTO LAVA AND THE STEAM CAME BACK FOR THEM
> 21,400 likes with 64 comments.
Open door, headsets on, a clear carved figure on a block of ice, one push, and the lava channel below turns it into a white cloud that rises until the whole frame goes blank.
Two decisions carry this clip, and both are made before anything is rendered:
-> The object is a person. A cube of ice would be science, a carved woman is a story nobody asked you to read.
-> The ending comes back up. The cloud climbing into the doorway turns a drop into a consequence.
-> The fall is long enough to lose sight of her, so the impact lands as a small bright flash you almost miss.
-> There is no caption and no reaction, which leaves every viewer to fill in the meaning alone.
This is where AI video is splitting into two tiers.
The lower tier shows a material behaving correctly and hopes that is enough, while the upper tier chooses a subject the eye cannot stay neutral about.
It costs the same to generate either one, and only one of them gets watched to the end.
If you want to test that yourself, run one motion on two different objects. Image-to-video off one still is the shortest way in, and @Picsart does it from a phone.
The lava did the physics, and the shape of the ice did everything else.
I wrote up the exact process below, prompts ready to paste ↓
DURGA ROOP NIRANJANI, SUKH SAMPATTI DATA🙌
J
O
K
O
I
T
U
M
K
O
D
H
Y
A
V
A
T
R
I
D
D
H
I
S
I
D
D
H
I
D
H
A
N
P
A
T
A
OM JAI LAKSHMI MATA
TUM PATAL-NIVASINI,TUM HI SHUBHDATA
KARMA-PRABHAV-PRAKASHINI🚩
B
H
A
V
A
N
I
D
H
I
K
I
T
R
A
T
A
OM JAI LAKSHMI MATA🪷🙏@grok
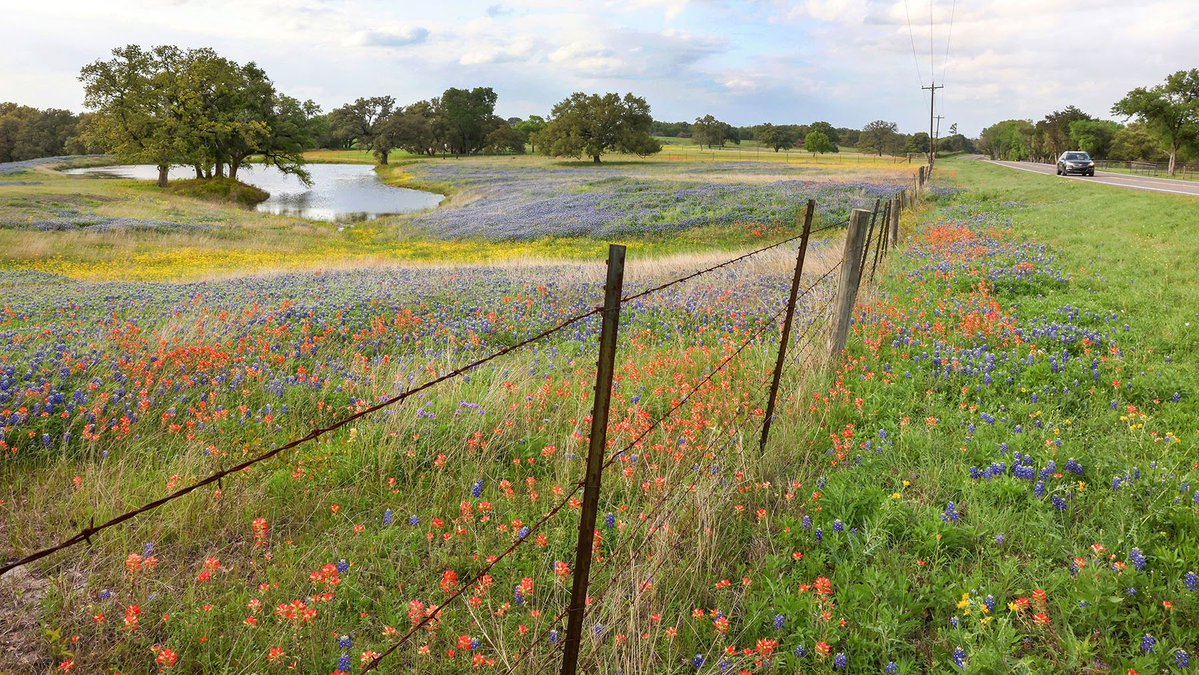
GOOGLE CHARGES FOR GEMINI IN THE CLOUD AND GAVE AWAY GEMMA 4 FOR FREE. IT RUNS ON A MINI PC WITH NO GPU AT ALL, AN N97 AND 16GB OF RAM, AND IT STILL LOOKED AT A PHOTO AND FOUND TWO KITTENS AND YELLOW WILDFLOWERS
here is the whole setup, download to answer:
LM Studio, a 600MB installer -> it checks your hardware and recommends a model that will actually fit -> gemma 4 E4B, 8B parameters, just over 6GB -> load it, start a chat -> text works, vision works, all on the cpu of a tiny windows box.
and here is the honest part. it did 3.6 tokens a second and spent 41.37 seconds thinking before it said hello. that is slow. it is also a machine with no graphics card doing multimodal AI that did not exist on consumer hardware two years ago.
this is what the floor of local AI looks like right now, and it is five things:
no gpu is no longer a no
-> a low power N97 with 16GB of shared ram runs an 8B multimodal model
-> not fast, but real, and the floor keeps rising every release
turn thinking off before you judge the speed
-> 41.37 seconds of that reply was reasoning you can switch off with one toggle
-> most people test with thinking on, see a minute of waiting, and decide local is unusable
let the app pick the model
-> LM Studio reads your hardware and recommends what will fit instead of letting you download something that crashes
-> this one feature removes the most common beginner failure
vision is the surprise
-> drag in a photo, get a description, no upload anywhere
-> for sorting, tagging and describing your own images that is already enough
it can serve the rest of your house
-> developer mode exposes it on your network so other programs can call it like an api
-> one small box becomes the model endpoint for everything else you run
google sells gemini by subscription and ships gemma for nothing. the free one now runs on hardware that costs less than a few months of the paid one.
my take, and it is the uncomfortable one: the question stopped being whether local AI runs on normal hardware, it does, and started being which jobs are fine at 3.6 tokens a second, which turns out to be more of them than people assume.
read the article below. that's how you start with what you already own.