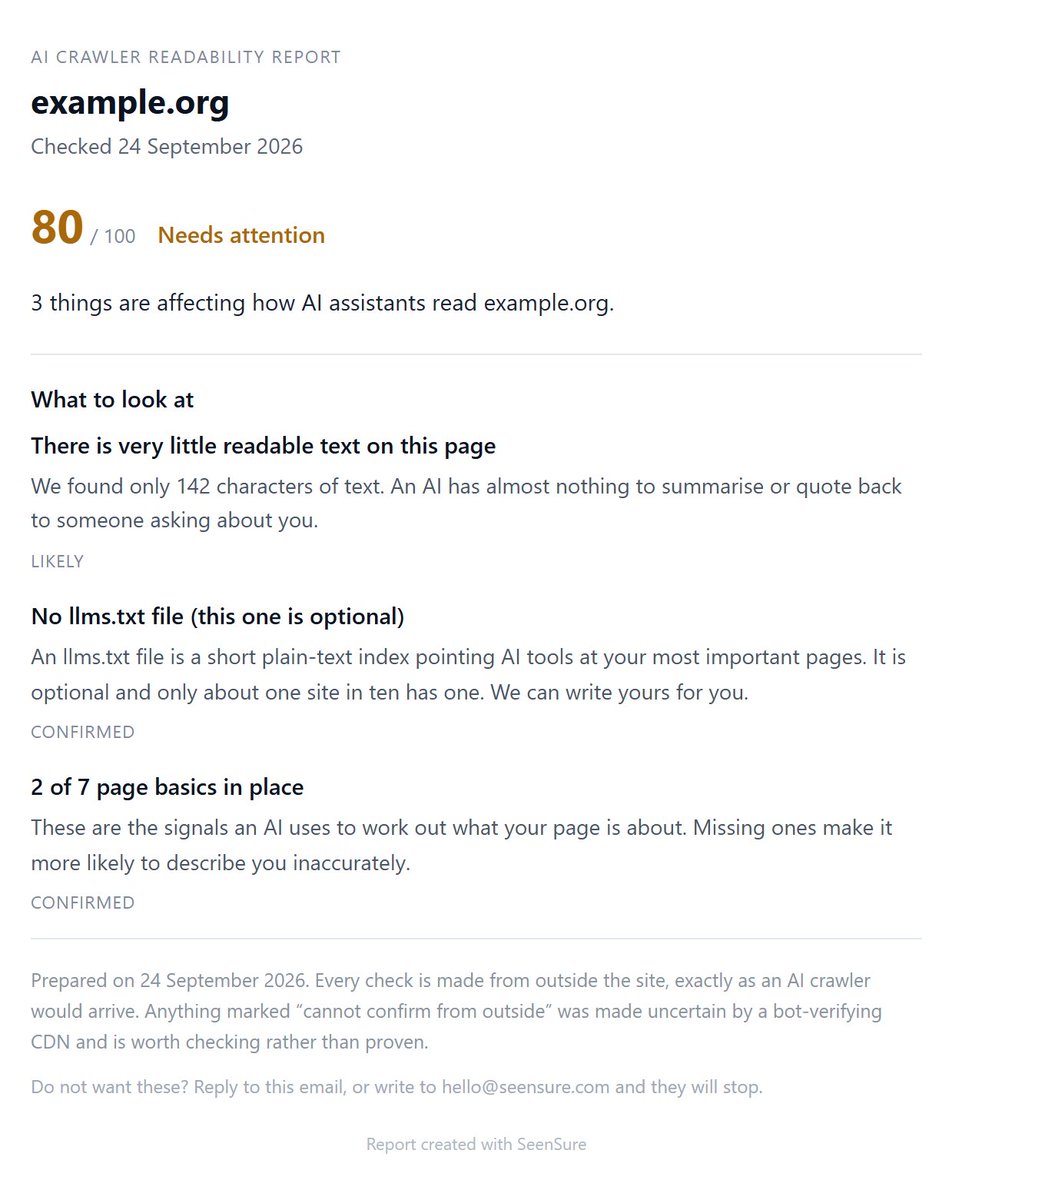
Re-ran our 1,046-site AI crawler study, 5 weeks after Cloudflare's change.
23 of 909 sites changed whether an AI crawler gets through. No big event, just drift.
One site: rare. 25 client sites: about one change every two months.
https://t.co/1wVvXUrrTy
Cloudflare showing Claude-User as blocked even with Agent set to Allow? Someone on the Community forum hit that today.
Fourth thread in ten days where the AI-bot settings and what crawlers actually get don't line up. Check Security Events before trusting the toggle.
Search Console says your sitemap couldn't be fetched, and the site is on Cloudflare? Check Security Events for rule BOBA-199 ("Block AI training crawlers").
Two site owners this week found it 403ing verified Googlebot with Search set to Allow.
336 of 422 Cloudflare sites whose AI-block lines vanished from robots.txt still 403 GPTBot and ClaudeBot. Only 17 of 273 that never had the block do. Search crawlers get through.
Data from Reese Calder. How to check yours from outside:
https://t.co/niVMHEohwr
We're on Product Hunt this week.
SeenSure checks whether AI crawlers can actually read your clients' sites, and on Pro it emails each client a report like this every month.
PRODUCTHUNT = 50% off your first 3 months, until 6 Oct.
https://t.co/ksFKgcmj5z
About fifty AI-visibility tools now track whether ChatGPT, Gemini, Perplexity or Claude mention your brand. Almost none check whether the crawler can reach your site at all. If GPTBot gets a 403, there's nothing to cite. Different question. https://t.co/bias5SwxSY
@sophlunar12@aleyda Worth splitting the two. Training refusal on Cloudflare-fronted hosts rose, but search/agent refusal on the same hosts fell hard, same window. Less training data, more access for the AI engines sending traffic now. One snapshot can't say why, just what moved.
@Navlio@aleyda Edge response only - each identity is a real fetch with that crawler's UA. Refusal = status >=400 or timeout from the live edge. robots.txt isn't read. A host disallowing GPTBot in robots but leaving the WAF open reads as access here, correctly - that's what the crawler gets.
Cloudflare's AI crawler default changes tomorrow.
Nobody can tell afterwards whether it changed anything for a site unless they recorded the before. Ours finished this morning: 1,046 sites.
Your own is free, today only. Add sites by 23:00 UTC:
https://t.co/57BwA3AG0V
@ranklore@aleyda Same bet here. If a page drops out of ChatGPT answers next week, check whether ChatGPT-User still gets a 200 before touching the content. Our last before-capture finished this morning; the after goes up on the 16th.
@TheSEOTalkers Yes - whether the crawler is served at all.
1,046 sites: an ordinary browser refused 0% of the time, named AI crawlers 15-20%. And a challenge often comes back as HTTP 200 with the challenge page as the body, so a status-only audit records it as healthy.
@TwelveCacti Good post. One thing on the last line: the switches tell you what Cloudflare is doing, not what your site is doing.
Probing 1,046 sites, several refusals came from the origin instead - Apache 406, nginx 403, LiteSpeed 429. A CDN dashboard shows none of those.
A bot-challenge page returns HTTP 200.
Uptime monitor green. Logs full of successes. And the AI crawler that fetched you stored "One moment, please" as your homepage.
Checked a site today: every www URL clean, apex root challenged. Nothing reported it.
We published a number and got it wrong.
We said 94.5% of AI crawler refusals "came from the CDN, not the site". A cf-ray proves Cloudflare was in the path, not that it decided.
Someone who'd studied 17M pages pushed back. He was right. Corrected:
https://t.co/pRkGu7xWig
@foxbook From the receiving end: we publish our server's AI crawler log. 7 crawlers in 7 days, 6 verify against their operator's published IP ranges. 1 doesn't, and it's the busiest name at 54 visits.
A user-agent is a claim. An allowlist of strings admits anyone who can type them.
@AdevAarons@Liam2307 Matches what I found probing 14 of them. Not one blocklist named a user-agent from 2025 or later - Claude-SearchBot, Claude-User and Perplexity-User all served normally while older names got 403. And 12 of 14 said nothing in robots.txt; it happens at the server.
@LKForge Worth adding that robots.txt is a floor, not the rate. Origin-level blocks never show up there: we probed a batch of agency sites and found 14 returning 403 to GPTBot or ClaudeBot with robots.txt silent on both. Declared blocks are only the visible half.
@GreyNoiseIO Matches what we see from outside: most sites only check the UA string. A forged name gets in; a real crawler is refused by a stale rule. Published IP ranges and reverse DNS are the only signals that survive both. Real crawlers do fetch robots.txt, so that absence is a tell.
@alexteillet On sites with aggressive bot protection the UA probe can't settle it — Cloudflare and Akamai verify crawler identity, so a 403 to "GPTBot" may just be you being challenged.
Send an invented bot alongside it. Both 403 = generic bot protection, nobody decided anything about AI.
Scanned 3,184 newly launched domains looking for sites accidentally blocking AI crawlers.
459 looked broken. 454 were just User-agent: * / Disallow: / — closed to everyone, not an AI decision.
Actually broken: 0.
Most sites are fine today. You'd never know if that changed.