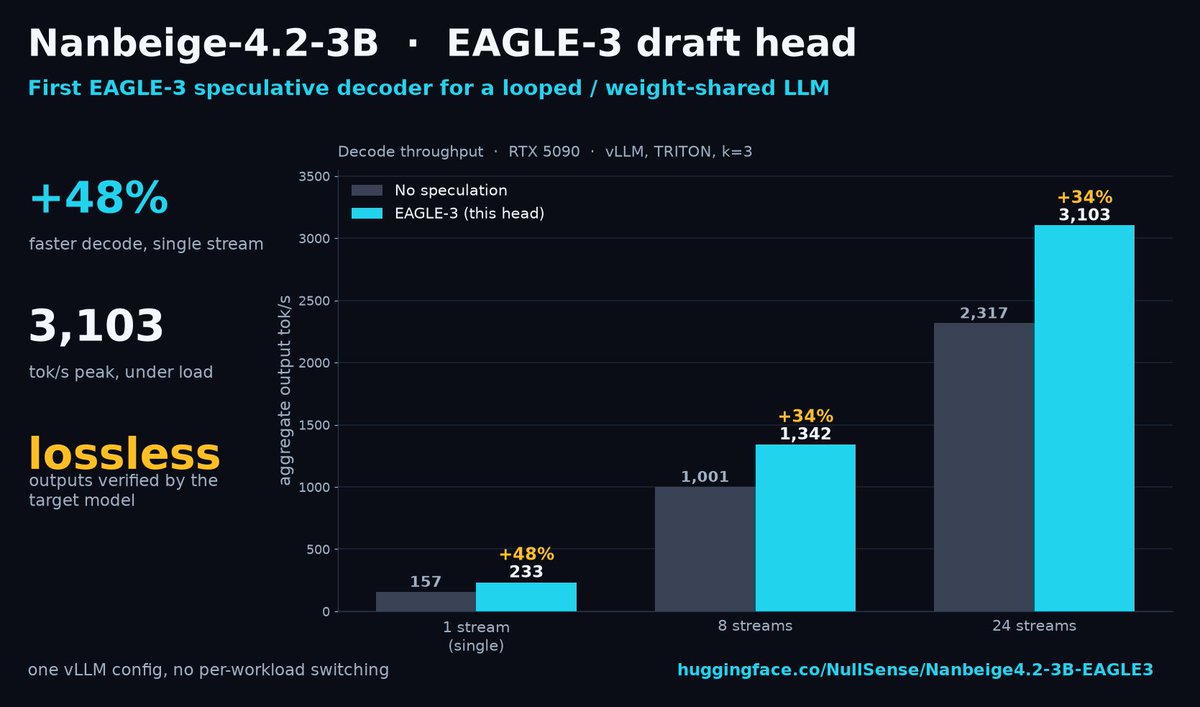
Trained an EAGLE-3 speculative decoding model, get some speed on your Nanbeige4.2-3B model! ⚡️⚡️⚡️
Decodes up to +48% faster with it, scales to ~3,100tok/s
Completely lossess
One vLLM config.
GGUF coming soon.
@m_zokov@MKhordoo Semantic meaning is dependent on your corpus quality, poor quality in - poor semantic output by the embedding model(s).
Chunking, splitting, enrichment of data are also important.
You can also use multimodal embedding models (and mix many models) to improve this.
@m_zokov@MKhordoo One important aspect is that you can search semantically, and be more token efficient, faster.
You can optimize your shape of data for the agent(s).
My main use case: index my linear, github, home dir, meeting transcripts, memories, etc. All searched in a simple mcp/api/sdk.
@0xSero Trying to launch a company and building search accessible to everyone, personally and privately. Some compute for experiments, development and tuning would be a godsend ❤️.
@trq212 I still use plan mode, though with agent capabilities less. If you are developing trivial stuff imo it's necessary. However once complexity rises in larger software and needs actual planning and has a lot of side-effects, caveats and so on, plan mode is the right tool.
@0xSero Thanks for doing this! I was thinking about doing this for a while but never got around to it...
What speed are you able to get 5.2 running on your hw and why not the new deepseek V4 flash?
Side question: what crawling tools do you use and do you parallelize massively?
@TheAhmadOsman Model swapping and routing.
I use llama-swap + vllm + llama.cpp + sglang + infinity + tei servers and Gliner style models for development on a 5090.
Managing my limited VRAM is an absolute pain, as I might be working on a few projects at once.
Any recommendations?
Trained an EAGLE-3 speculative decoding model, get some speed on your Nanbeige4.2-3B model! ⚡️⚡️⚡️
Decodes up to +48% faster with it, scales to ~3,100tok/s
Completely lossess
One vLLM config.
GGUF coming soon.
@rauchg > scales to infinity
Did you run retrieval benchmarks? I'd be very surprised if this scaled well and didn't get very lengthy and expensive past a few hundred docs.
This is the last piece of the set.
Three quants (FP8, NVFP4 LoopShield, NVFP4A16) plus the EAGLE-3 head.
What are you running Nanbeige for? and what tok/s are you getting with the quant + draft head?
genuinely curious. Get em here:
Trained an EAGLE-3 speculative decoding model, get some speed on your Nanbeige4.2-3B model! ⚡️⚡️⚡️
Decodes up to +48% faster with it, scales to ~3,100tok/s
Completely lossess
One vLLM config.
GGUF coming soon.