Agents & Developer Experience Ecosystems Lead EMEA at Google. O'Reilly author. Local AI, fine-tuning. Building tool-eval-bench & awesome-local-ai. Views my own.
I couldn't keep track of all the local AI tools flying around anymore. New engines, harnesses, tooling, benchmarks... every week.
So I started awesome-local-ai: a list sorted by what you want to do, not by hype.
The twist: it's built for agents too. Point your coding agent at it and ask it to recommend a setup for your hardware.
It's early and DGX Spark-heavy. Help me fill the gaps:
https://t.co/aO5UiUnmjh
Some magical progress towards "magic state" in quantum!
Our @GoogleQuantumAI team has demonstrated "magic state cultivation" on physical hardware for the first time. The result is a 40x error reduction on our Willow processor vs. previous methods, achieving a state-of-the-art 99.99% logical fidelity.
It's another step towards useful, error-corrected quantum computers to help solve the hardest problems. The result is published in Science today, watch the video below to see how it works
We’re rolling out Gemini 4 Argon in Antigravity to paid Google AI Pro subscribers today. Demand has been incredible and we've scaled capacity deliberately to get here. We’ve rolled out a separate weekly-only Argon quota for Pro on top of the existing Gemini bucket for 3.8 Flash so you have the best of Gemini for all your tasks.
Welcome to the new Gemma documentation!
We've built a brand new home for developers to explore, experiment, and build.
What’s new?
🌐 Global model selector for customized code snippets
🤖 Better agent support (turn any page into Markdown!)
📊 Data-driven backend for a consistent experience
⚡️ On-device demos running directly in your browser!
Check it out: https://t.co/yx9K4xGH8M
Part of my weekly paper series.
What if you didn't train the agent, but trained a small model to rewrite its harness?
A 4B "editor" beat its 35B teacher on average across 21 unseen task families. No weight updates at test time.
@johnny_everson@ashxhart that's what I am looking for. I wondered if there's a good kvm given i have two macbooks and a mac studio. so I'd love to be able to swap between at least two devices if possible.
re mirrorless camera: same! have a sony dslr above my screen sicne covid and love it!
BREAKING NEWS🚨: Google has submitted its FIRST TPUv7 FP8 vLLM results to our Agentic Inference Benchmark and has demonstrated 1.67x better perf per dollar than even GB300 NVL72 FP4. 🚀
It is amazing to see Google go full steam ahead with externalizing the power of TPUs outside of Google.👇️ (1/4)🧵
Remember Google Coral? Maybe it's in a drawer, or still accelerating Frigate in your homelab. I've got a new job for it.
Reef: an 11.2M-parameter decision model that runs entirely on the Coral. 4.73 on Decision Index, within 7% of a model 24x its size.
Send an alert or a Frigate event plus typed questions, get a calibrated probability for every option. About 30 ms at around 2 W on a Coral, fully on your LAN. The demo below runs in your browser.
Links in the reply.
That Argon gummy bear video turned out to be a FAKE.
I ran the prompt myself, and the results from Gemini 4 Argon is MUCH better. Opus is still better, but Argon is not bad at all.
Full prompt below.
I make no secret that I love cycling. So when I saw the name Gemini 4 Argon, I knew exactly what I had to build.
An Argon 18 Nitrogen Pro demo, made with a single prompt: https://t.co/w2UY180MLQ
Can't wait to see what you build with Gemini!
Update on yesterday's Gemma 4 E2B decision model.
v2 vs v1 on the same eval:
Accuracy: 0.513 to 0.804
KL from gold: 0.367 to 0.182
Brier: 0.197 to 0.082
For reference, the teacher model scores 0.735, so the student now beats its teacher. A dedicated fine-tuned decider (OpenDecider-small-td) lands at 0.792.
Not free: p50 latency went from 0.17 s to 0.61 s, and calibration (ECE) slipped a little, 0.041 to 0.061.
Small model, one consumer GPU, an afternoon of iterating. If you've been waiting to try fine-tuning, this is your sign.
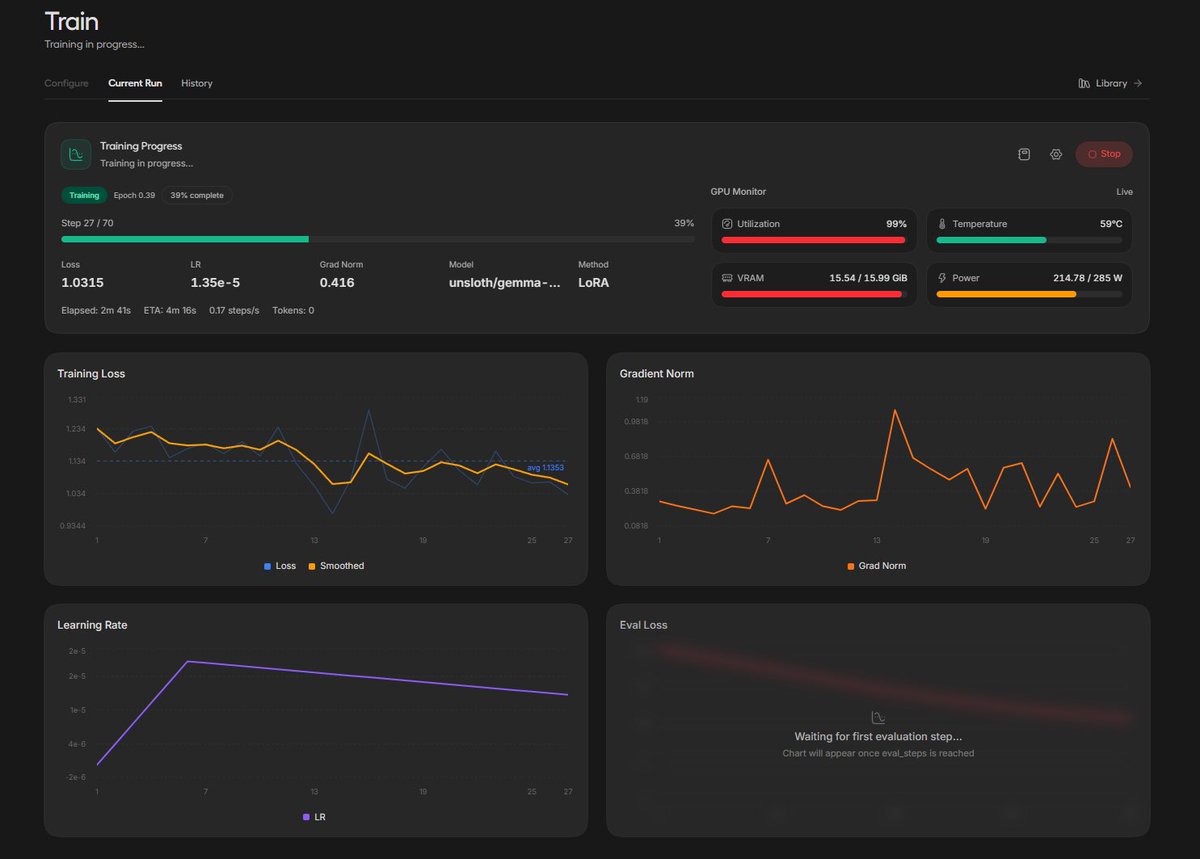
Fine-tuning my own decision model on my old gaming rig: @googlegemma Gemma 4 E2B + LoRA in @UnslothAI Studio.
16 GB of VRAM, about 12 minutes for the run in total.
If you've never fine-tuned a model, this is your sign. The barrier is a lot lower than you think.