Introducing Code Video Model 🎬
Amazing work led by @raywzy1 and the team!
Agentic coding as the engine for controllable video generation.
Scene layout, motion, timing, camera trajectories, and physical dynamics, all in editable code.
A coding agent turns prompts into executable programs that render proxy videos. Our training-free early-step conditioning lets a pretrained video model follow the proxy’s structure while adopting a reference image’s appearance.
From physics-grounded motion and bullet time to 3D/4D reconstruction and robotics simulation, it all starts with code.
Watch the demo and explore more visual results 👇
Project page: https://t.co/3eyhkYhR2t
Paper: https://t.co/VzHC03u9JN
Code: https://t.co/nspc5JM1A4
Data: https://t.co/18WMfQldOK
Youtube: https://t.co/ohyGXbKRZE
📢 EgoHOI: Egocentric World Model for Photorealistic Hand-Object Interaction Synthesis
EgoHOI integrates physics-informed embeddings to regularize latent dynamics for realistic first-person hand-object interaction rollouts.
Code & Paper(open source): https://t.co/oc9mzRrMq3
We don’t generate videos. 🎬
We generate worlds from videos. 🌍
Introducing InSpatio-World — the world's first open-source real-time 4D world model‼️
Your input: a video clip
Our output: a dynamic, navigable, persistent world
🕹️ explore freely across viewpoints
⏪ control time forward and backward
🔓 open-source and ready to build on :)
Live demo:
🔗 https://t.co/nqU4ZZSqOH
Code & weights:
🔗 https://t.co/rNMilkvKUV
Project page:
🔗 https://t.co/WfMjYGbfzq
Super impressive!
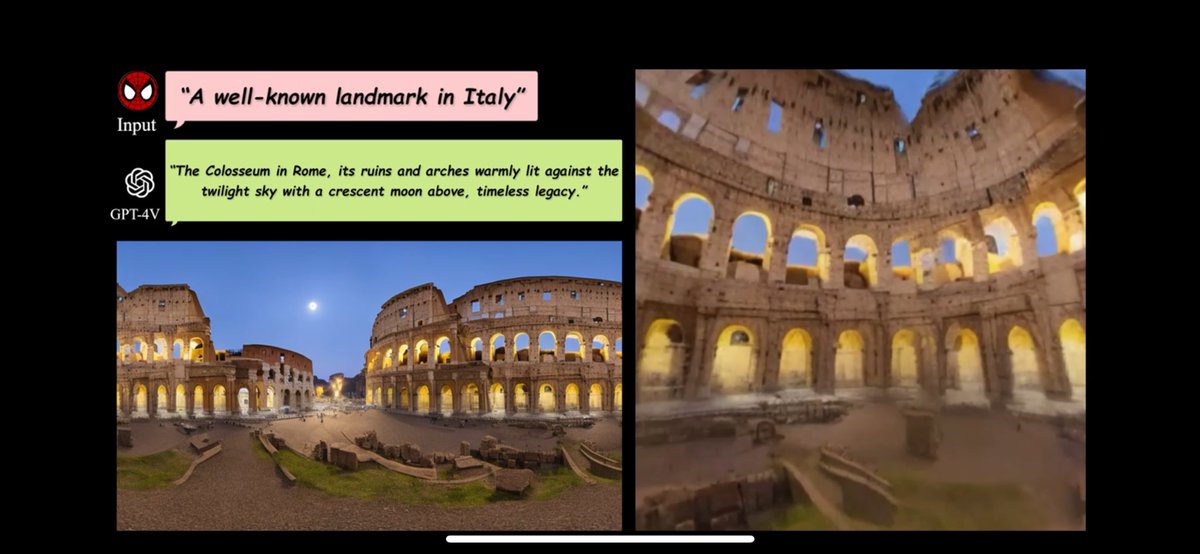
It also gave me a funny deja vu moment: the Colosseum demo looks very close to what we did in DreamScene360 about 1.5 years ago (https://t.co/e6z9e15yWu). Back then we tried to show how fuzzy text prompts could become an immersive 3D environment, and even let Spider-Man fly through the space to highlight that it was not just a video, but a real navigable scene.
Later we pushed this idea further with 4K4DGen (https://t.co/gJcDz7IfbX), adding dynamic motion on top of static 3D Gaussians using generative video priors, so scenes gain a time dimension while keeping spatial stability.
Looking back, the pattern feels very clear to me:
generative video models give the world knowledge, and 3D representations are the most reliable way to ground that knowledge into stable, explorable spaces.
Seeing Marble again reinforces one thing: if we want world models that are consistent, controllable, and useful, spatial structure still matters a lot. Really cool to see the field moving in this direction.
Can VLMs really think in 4D (3D space + time)? 🤔
When a model can’t tell “left” from “right,” something’s missing.
That’s why we built VLM4D — a benchmark for spatiotemporal reasoning, debuting at #ICCV2025
📅 Oct 21 | 🕒 3–5 PM | 📍Exhibit Hall I #798
https://t.co/PYgoPPR7rR
The wait is over! 💥
Our Feature4X code (#CVPR2025 ) is now open-source:
🔗 https://t.co/5jubJl2r62
All-in-one 4D ➡️ reconstruction, understanding, manipulation & reasoning with multimodal LLMs
From monocular videos → to 4D Gaussian Feature Fields → towards 4D Agentic AI 🤖✨
🚀 Our #ICCV2025 work — VLM4D is here!
The first benchmark to truly test if Vision-Language Models can think in 4D (3D space📷 + time🕒).
Today’s MLLMs/VLMs can solve complex math via visual inputs… but can’t even tell left from right in a video?👀
👉https://t.co/aPa1XQknFm
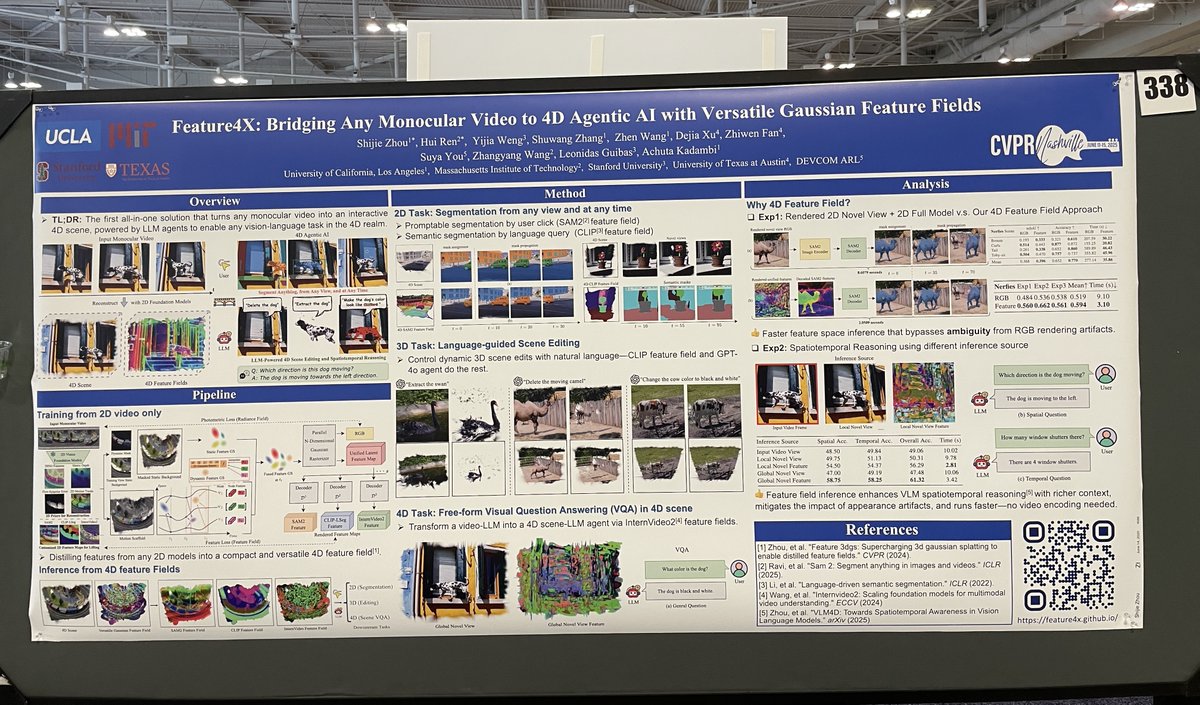
We’re presenting Feature4X at #CVPR25 now — come say hi at ExHall D, Poster #338!
🌀 Feature4X: Bridging Any Monocular Video to 4D Agentic AI with Versatile Gaussian Feature Fields
📍 Project: https://t.co/jdkMJa4s37
👋 Me: https://t.co/5qbQRsfisU
🇸🇬 Even though I won't be able to attend #ICLR2025 in person this year, I'm excited to share two works that will be presented!👇
🔥 [Spotlight] 𝟰𝗞𝟰𝗗𝗚𝗲𝗻: 𝗣𝗮𝗻𝗼𝗿𝗮𝗺𝗶𝗰 𝟰𝗗 𝗚𝗲𝗻𝗲𝗿𝗮𝘁𝗶𝗼𝗻 𝗮𝘁 𝟰𝗞 𝗥𝗲𝘀𝗼𝗹𝘂𝘁𝗶𝗼𝗻
📍 Presented at Hall 3 + Hall 2B #631
🗓️ Presented on Friday, April 25, 2025
🕚 Presented from 3:00 PM – 4:30 PM
🌐 https://t.co/D4KCplpTvg
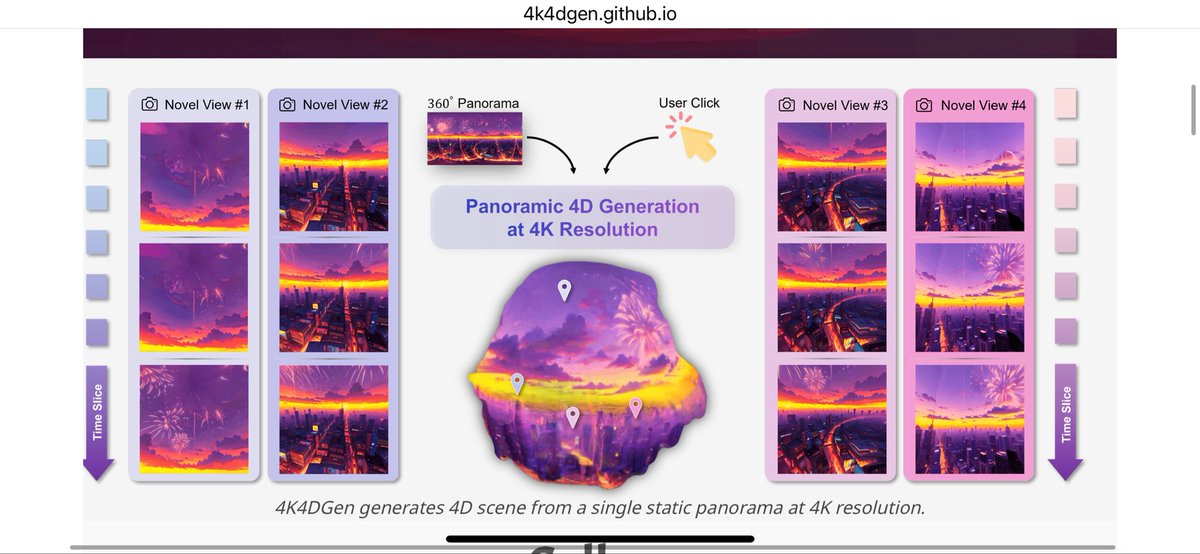
𝗧𝗟;𝗗𝗥: We introduce a novel method for generating 4K high-resolution, panoramic 4D content, pushing the boundaries of visual synthesis.
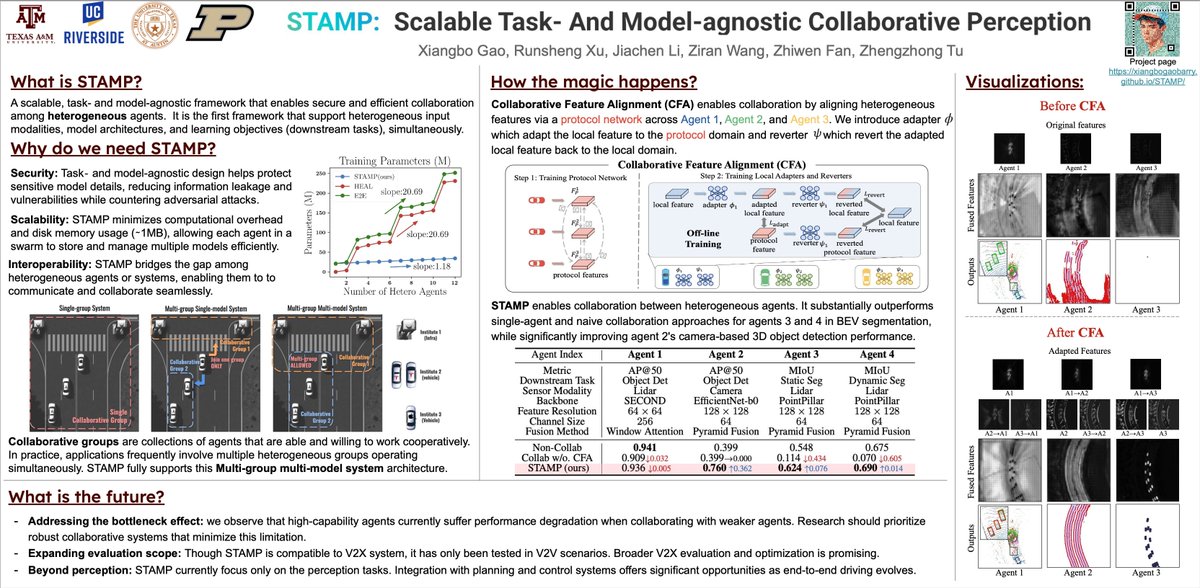
🔥 𝗦𝗧𝗔𝗠𝗣: 𝗦𝗰𝗮𝗹𝗮𝗯𝗹𝗲 𝗧𝗮𝘀𝗸- 𝗔𝗻𝗱 𝗠𝗼𝗱𝗲𝗹-𝗮𝗴𝗻𝗼𝘀𝘁𝗶𝗰 𝗖𝗼𝗹𝗹𝗮𝗯𝗼𝗿𝗮𝘁𝗶𝘃𝗲 𝗣𝗲𝗿𝗰𝗲𝗽𝘁𝗶𝗼𝗻
📍 Presented at Hall 3 + Hall 2B #1
🗓️ Presented on Friday, April 25, 2025
🕚 Presented from 3:00 PM – 4:30 PM
🌐 https://t.co/Ve39rK27jz
𝗧𝗟;𝗗𝗥: STAMP offers a flexible and scalable framework for collaborative perception among diverse agents and tasks.
Check out the websites for more details, papers, and demos!
Feature4X: Bridging Any Monocular Video to 4D Agentic AI with Versatile Gaussian Feature Fields
Contributions:
• We propose a general 4D feature field distillation technique using Gaussian Splatting to build an interactive 4D scene. This lifts the functionalities of any 2D vision (image/video) foundation models into the 4D realm, relying solely on monocular video input.
• We introduce the first compact and versatile 4D Gaussian feature field representation. This leverages the smooth, low-rank nature of scene semantics by modeling the dense 4D feature field as interpolations of a sparse set of base features.
• We develop an LLM-powered agentic AI capable of interpreting natural language prompts, dynamically adjusting configuration parameters, and iteratively refining results through trial and feedback. This enables intelligent 4D scene interaction and manipulation.
🚀 Our NeurIPS '24 work, Large Spatial Model (LSM), is here! LSM performs semantic 3D reconstruction in just 0.1s, processing unposed data via feed-forward 3D reconstruction.
👉It leverages large-scale 3D datasets with minimal annotations, defining a 3D latent space. We are continuously exploring how this explicit 3D representation can further enhance reasoning and robotic learning.
🔗 Try our online Gradio demo with your own data at https://t.co/FjGsPkcJ6h
#NeurIPS2024 #3DReconstruction
🚨Revolutionizing 4D VR/AR Content Generation!
Excited to share our latest paper on 4K4DGen, a breakthrough in creating panoramic 4D immersive environments at 4K resolution. 🎥🌍
💡 The Challenge:
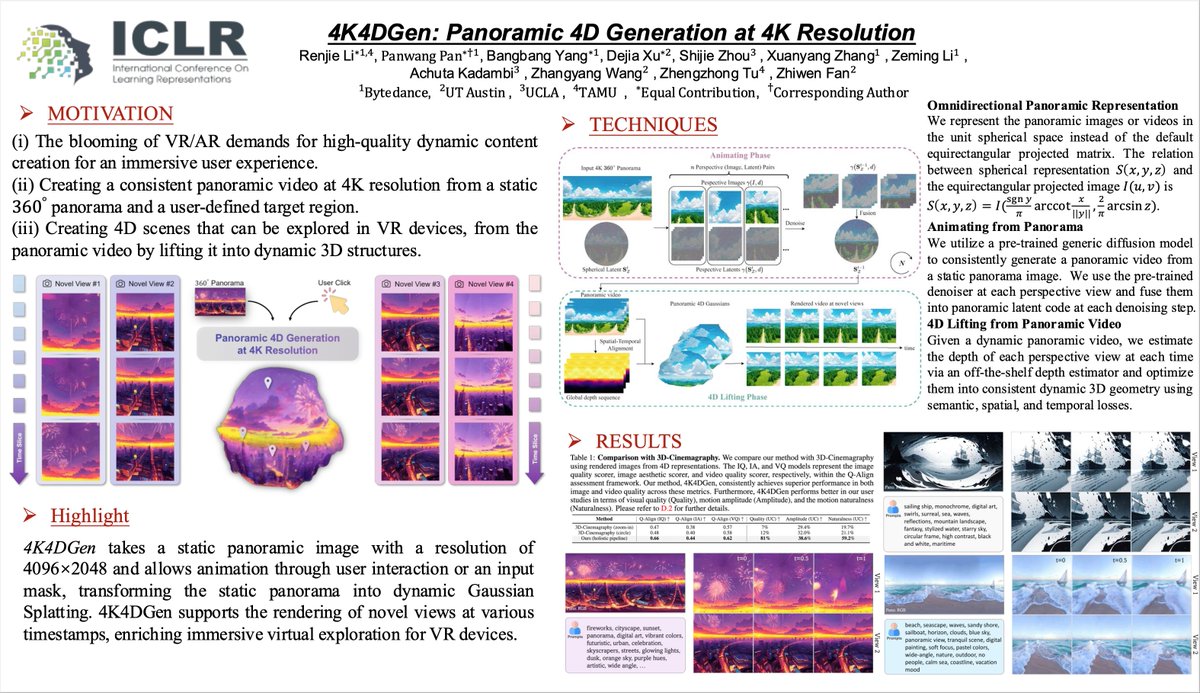
Current generative models struggle with producing 360° dynamic scenes at high quality, limiting the potential for true immersion in VR/AR applications. We tackle this by elevating static panoramas into fully dynamic, high-res 4D environments.
🔍 Our Approach:
• Panoramic Denoiser: Leverages 2D diffusion models to generate smooth, animated 360° panoramas with global coherence.
• Dynamic Panoramic Lifting: Elevates panoramic videos into 4D spaces while ensuring seamless spatial and temporal consistency.
🔧 The Results:
4K4DGen produces high-quality perspective videos that maintain consistency across both time and views, allowing animation through user interaction or an input mask and transforming the static panorama into dynamic Gaussian Splatting.
💡 Key Takeaways:
• First-ever system to generate 4D panoramic content at 4096x2048 resolution.
• Seamless dynamic scenes with 360° free-view support.
• 4K4DGen unlocks high-resolution, free-viewpoint experiences that are crucial for VR/AR applications.
🌟 Project: https://t.co/M4K3fQi8RE
🚀 Abstract: https://t.co/s2LUsevaNJ
#AI #DeepLearning #VideoGeneration #VR #AR #GenAI #ML #GenerativeAI #Video #Creation #GaussianSplatting #3D #4D
DreamScene360 is now open source! Visit our website for more details!
Website: https://t.co/s3SnKfJU4L
Code: https://t.co/qQfeL8o2Df
Unfortunately, I can't make it to #ECCV2024 in Italy🇮🇹 this year, but I've already flown around the Colosseum in my own generated metaverse 😊.
DreamScene360
Unconstrained Text-to-3D Scene Generation with Panoramic Gaussian Splatting
The increasing demand for virtual reality applications has highlighted the significance of crafting immersive 3D assets. We present a text-to-3D 360^{circ} scene generation pipeline
#ECCV2024 is happening soon in Milan! Unfortunately, many collaborators are unable to attend due to visa issues, but we’re making sure everything is ready ahead of time!
(1/3) We’re excited to announce the release of our DreamScene360 code: https://t.co/e6z9e166M2. With it, you can generate 3D panoramic Gaussians from simple text prompts.
This work is a collaboration with our amazing UCLA colleagues. We also have an extended version for 4D panoramic generation at 4K resolution: https://t.co/gJcDz7IN1v.