The Runway AI Summit speaker list is growing. We've just added a new group of voices to the lineup, joining us for a full day in San Francisco this September. Join us to hear where AI is headed next, straight from the people building it.
Register at the link below.
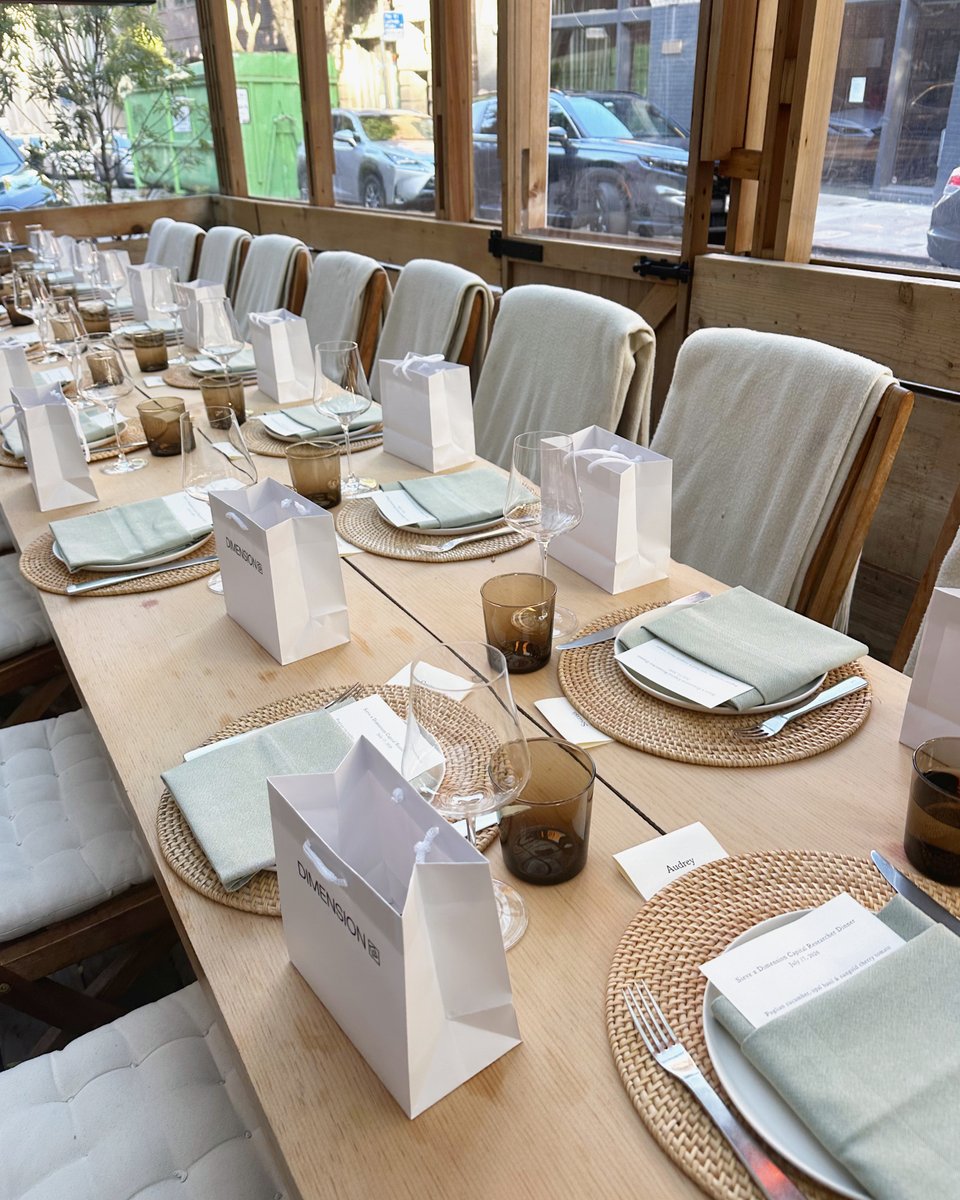
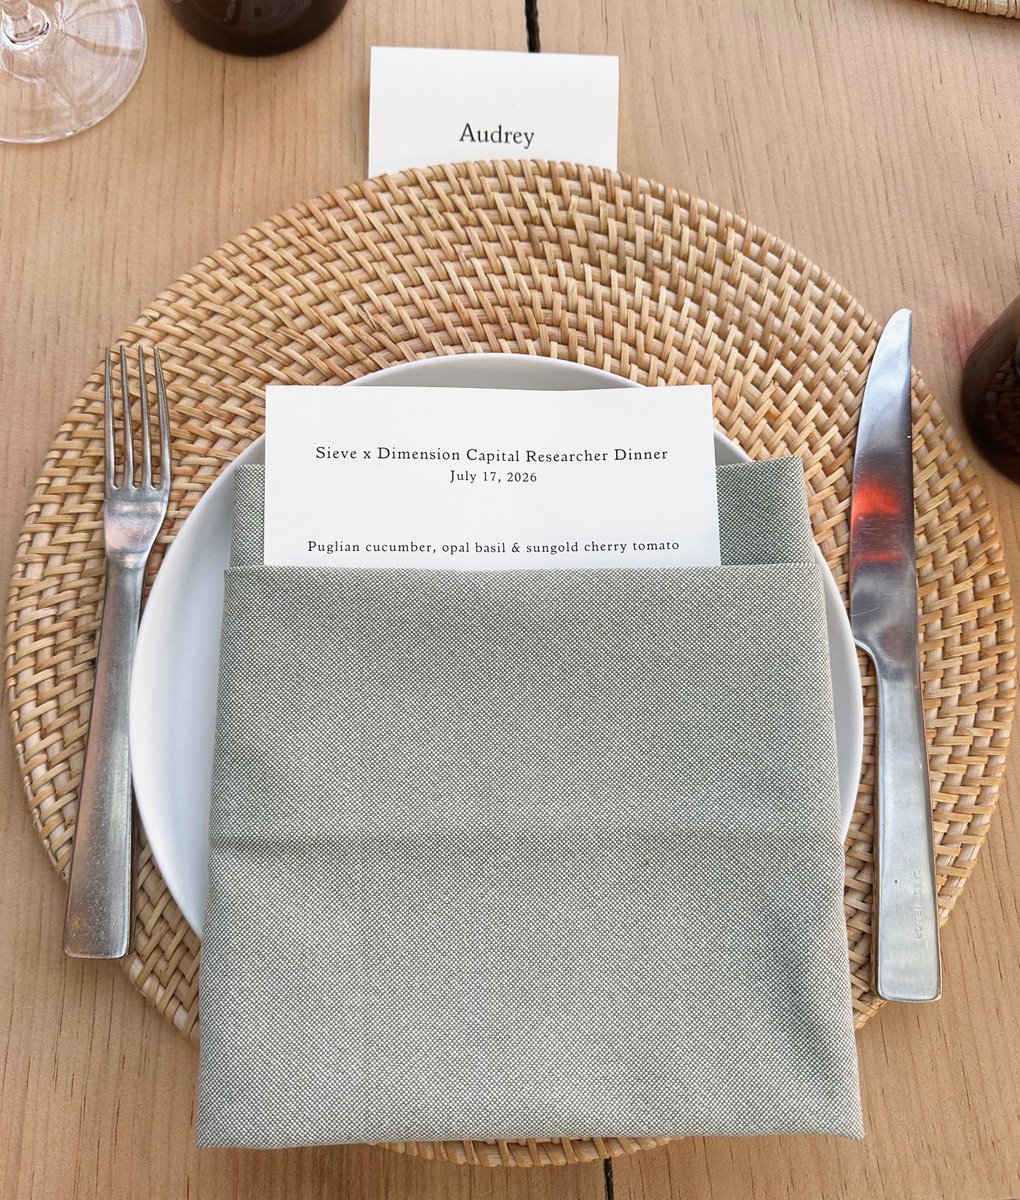
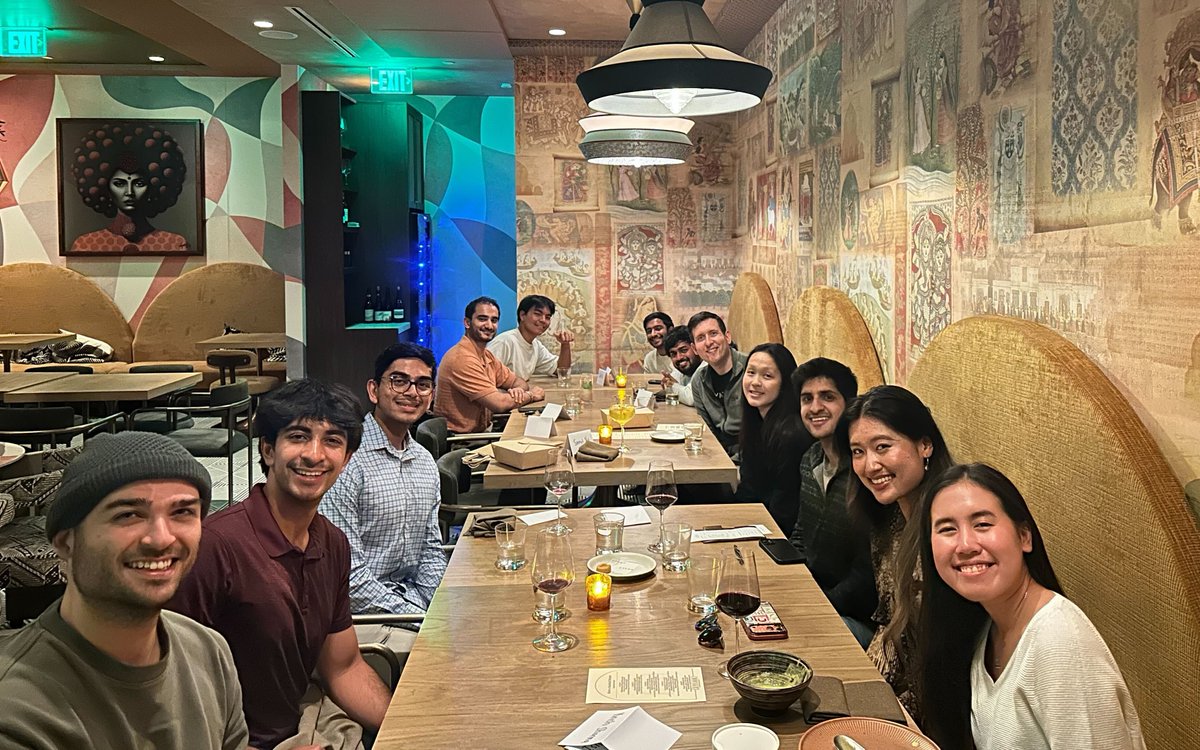
As a part of our monthly researcher dinner series, we partnered with @_DimensionCap to gather folks in the multimodal space for a chef’s table dinner at Cotogna. We can’t wait to host many more of these dinners centered on robotics, computer use agents, media generation, and more.
If you’re a researcher interested in attending one our dinners, get it touch via https://t.co/NQFy3QyZQI.
Introducing Sieve’s new home in San Francisco. We needed a new space to reflect our rapid growth, lounge areas for collaboration, and a games area to host some pretty intense ping pong.
Think you could beat us at a match? Apply at https://t.co/OLVUAeSkaD.
👋 finally sharing some of my work from this summer at @sieve_data!!
i’ve been building video search across 1B videos, going from research papers + embedding evals all the way down to GPUs and distributed systems (very 0→100)
check it out : )
https://t.co/jxXOzHNQrM
Sieve hosted two events for the multimodal research community at CVPR 2026: a researcher dinner and a happy hour bringing together students, engineers, and researchers from across the ecosystem.
The conversations were some of the highlights of the week - we discussed everything from video understanding and world models to the evolving multimodal landscape, emerging research challenges, and the data infrastructure needed to train the next generation of AI systems.
A huge thank you to everyone who joined us, shared ideas, challenged assumptions, and made the events so engaging.
At Sieve, we're building multimodal data infrastructure for embodied AI, generative media, agents and robotics. If you're excited about multimodal data, enjoy moving quickly, and want to work on some of the hardest problems in AI, we'd love to hear from you.
Careers: https://t.co/944g6Eudxi
Earlier this month, Sieve hosted an intimate dinner with Stanford undergraduates and graduate students exploring the multimodal space, bringing together perspectives from research and industry over an exceptional meal from Eylan. We look forward to hosting similar events at other universities soon.
We’re excited to be heading to CVPR 2026 next week.
Over the past year, Sieve has built one of the largest repositories of multimodal data and evals frontier labs use to train and evaluate world models, video generation systems, and robot policies.
If you are a researcher or builder working in the multimodal space, drop us a message here or at [email protected] — we'd love to connect at CVPR!
We just hosted an amazing multimodal AI lunch at @ycombinator HQ, bringing together tons of multimodal AI researchers across many different frontier AI labs.
We talked about everything from benchmarking creativity to robot policies to computer use agents. Thanks to @sdianahu, Audrey Pe, and @ArthitaG for making it a successful event.
If you're a researcher or builder working in the multimodal space, drop us a DM. We'd love to chat and invite you to the next one!
we hosted a multimodal researcher lunch at @ycombinator with the @sievedata team, who've been doing really good work in multimodal data
we got researchers from several frontier labs in a room together and the conversation ranged from robotics to world models to computer use agents. More of these coming soon!
Video as a foundation for AGI.
I really like one of the ideas Demis explores in this conversation: Veo 3 as a world simulator directly challenging the need for physical embodiment on our path to true world understanding.
More specifically it's interesting that scaling video models (i.e. Veo 3) is allowing accurate simulation of complex physical phenomena (fluids, lighting, material, etc). This is the base argument for these models learning underlying structures of reality, not just copying training videos.
It's also interesting to question what it means for AI to "understand" the world. Accurate reality simulation signals some deeper form of understanding (not just prediction).
AI video is at an interesting inflection point and there's no better time to be working with leading research teams in the space. Join us at @sievedata to push world simulators forward!
If you're a cracked infra engineer who:
- loves Go, ETL, OLAP DBs, k8s
- wants to change the future of video AI
- loves seeing their work translate to $$$
we're aggressively hiring right now @sievedata.
Dm me. 💜🚀
The last two months have been insane. I randomly came into the office this morning and decided to record this video on why there has literally never been a more exciting time to join @sievedata. We're working with leading research teams pushing the frontier of creative, robotics, VR, gaming, and so much more. It gets me giddy thinking about the fact that we get to work with such teams given how I got into a lot of this stuff doing robotics in high school.
If you’re an engineer that wants to push the frontier of these industries and finds the technical challenges around internet-scale video processing interesting, please reach out! You can learn more about our work through the document linked in thread and check out our open roles.
We think transparency in how AI capabilities work and are evaluated is key to developers building trust in using them.
Tomorrow, we'll be sharing the work we've done improving a specific API we serve (one that involves a ton of nuance in judging quality). Stay tuned.
We're in London at @veedstudio HQ this weekend with 150 hackers building Gen AI video tools. They got access to caffeine, pizza, a bunch of Sieve credits, and a few unreleased APIs 👀
Let's see what they cook up in the next 24 hours!
I used AI to build a knowledge graph of every @dwarkesh_sp episode! 🚀
Scrape thousands of hours of youtube content
Generate articles with timestamps & backlinks
100% Open Source 👾
Introducing TubeGraph, a tool for visualizing connections across a YT channel! 🧠
I used AI to make ANY YouTube video 1/4 the length!
Introducing TLDR Tube, simply take a link to a youtube video, and instantly get a hyper edited version that gets straight to the point!
@theo videos are now ADHD/Zoomer friendly!