Claude Fable 5.2 passed 28 of 30 Frontier Class coding jobs on Signal65 PINNACLE. No other model has passed more than 21. It also costs $30.51 per passed job in our testing, 3.9x Claude Opus 5.5. Best model on the board, priced like it. https://t.co/RbiffOOgz5
AI agents spend much of their working time running tools on CPUs, so the processor decides how many agents a server can carry and how quickly each one finishes its work. That puts CPU choice back into the AI infrastructure budget, alongside the GPUs.
Signal65 tested two AMD EPYC Venice processors ahead of today's launch. In our early testing, Zen 6 ran CPU-bound agent tool work 22% to 60% faster per core than the previous-generation EPYC 9755. A preview of the upcoming Signal65 PINNACLE CPU Benchmark shows the 256-core EPYC 9996 finishing each agent's tool work 22% faster than the 96-core EPYC 9686F at 1,024 concurrent agents, while the 9686F's faster cores lead when the server is lightly loaded. A full PINNACLE CPU Benchmark deep dive is coming soon.
The choice between the two Venice designs comes down to how many agents you run and how quickly each one needs to move. More testing soon!
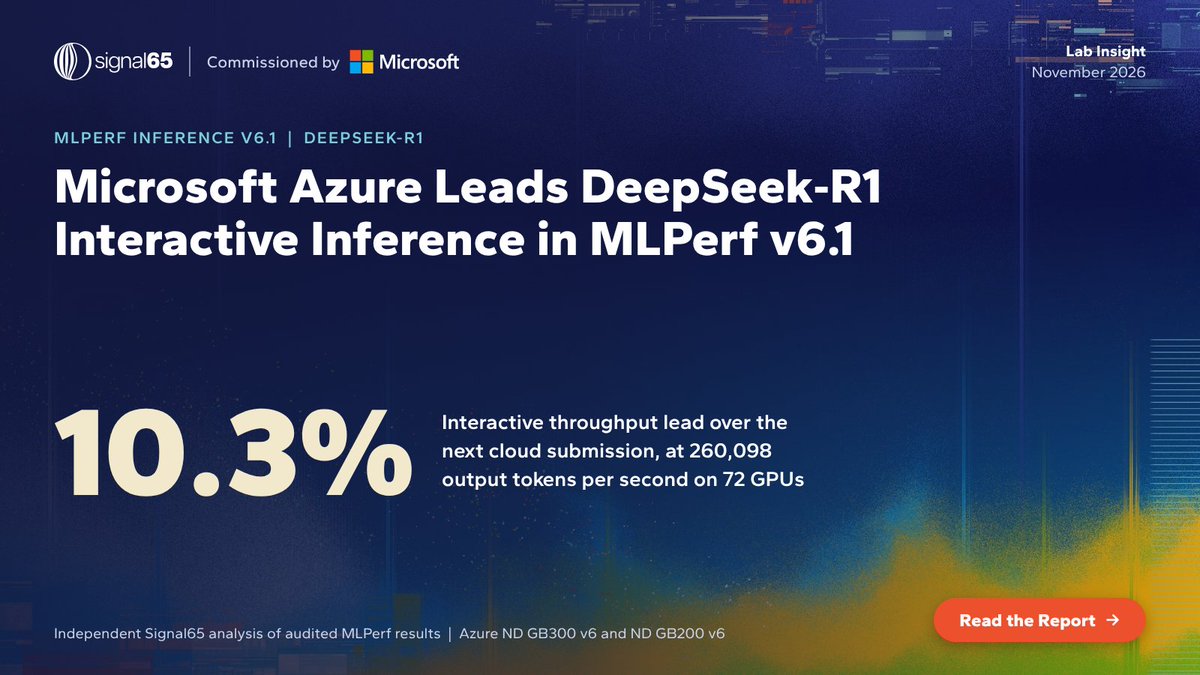
Reasoning models only pay off when people get answers fast enough to stay in the flow of their work, and every extra GPU needed to hold that response time adds to the cost of serving them. Signal65 analyzed the audited MLPerf Inference v6.1 DeepSeek-R1 results to see which cloud delivers the most reasoning throughput under the tightest latency limits.
The Interactive scenario holds every system to a 1.5s limit on time to first token and 15ms per output token, the closest MLPerf match for conversational and coding workloads. We compared each Azure result against systems with the same GPU generation and GPU count.
Key findings from our analysis:
➡️ Azure ND GB300 v6 leads Interactive throughput by 10.3% over the next cloud submission, at 260,098 output tokens per second on 72 GPUs
➡️ Azure ND GB200 v6 scales from one NVL72 rack to four at 93.6% efficiency in Server and 96.4% in Offline
➡️ Four racks reach 2.09M output tokens per second in Offline, the only multi-rack NVL72 result from a cloud provider this round
➡️ Moving from GB200 to GB300 raises Server throughput 38.1% at the same 72-GPU scale
➡️ Azure ND GB200 v6 posts the top Server and Offline throughput of all Available 72-GPU GB200 systems, 1.7% and 2.3% ahead of the closest cloud submission
Read the full Lab Insight: https://t.co/2hnZsB5CeX @Azure@nvidia
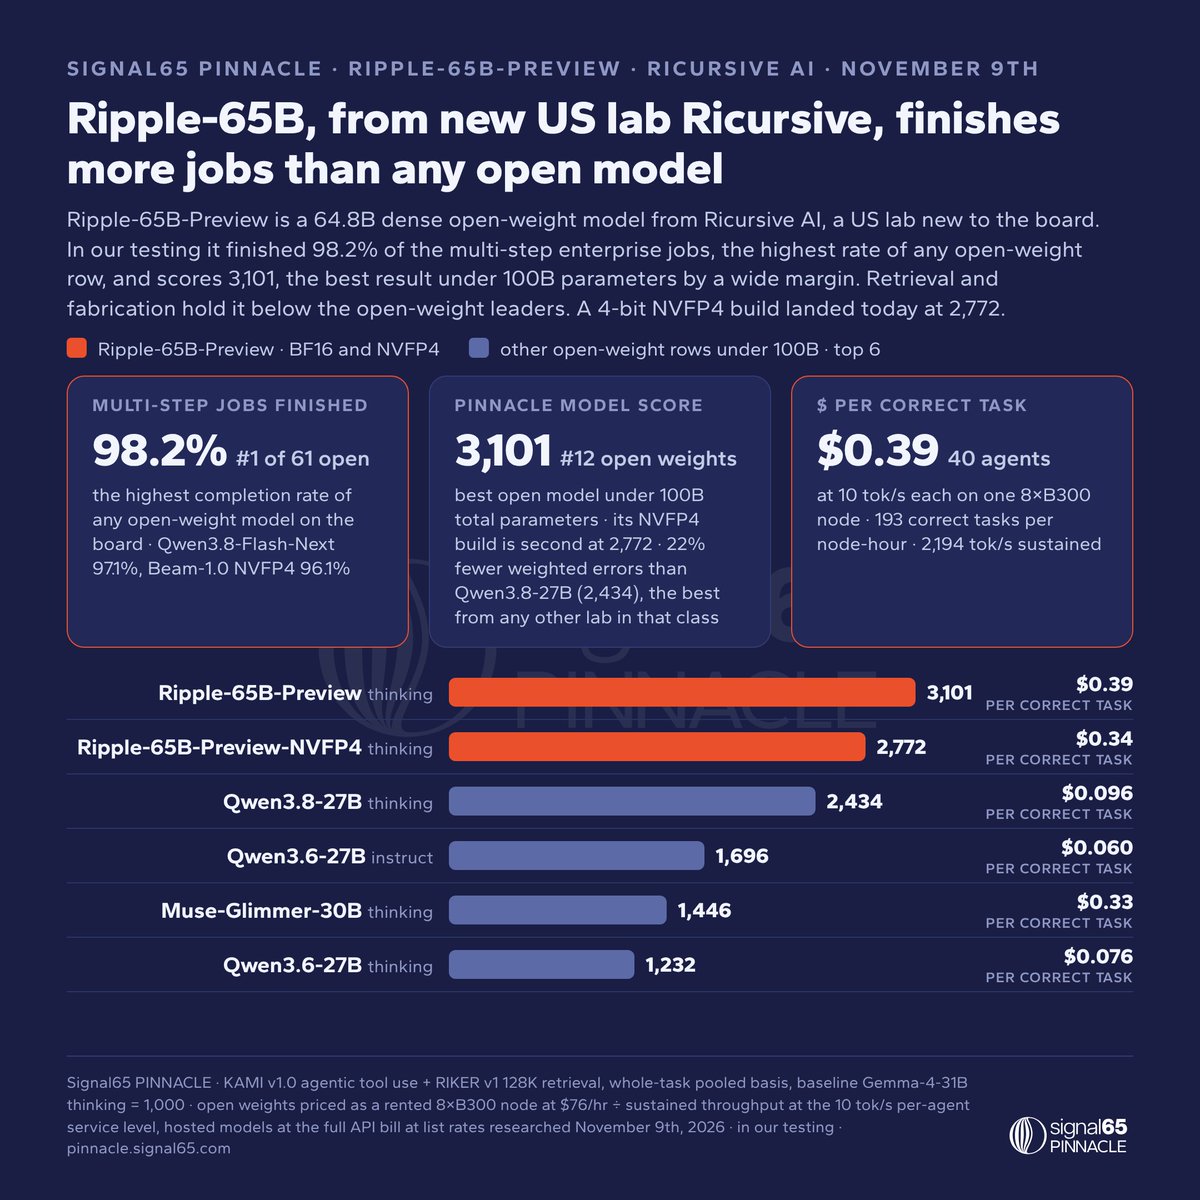
Somewhat surprisingly for a medium-sized option, a 65B open-weight model that you can run on its own hardware just posted the highest agentic job completion of any open model on Signal65 PINNACLE.
Live on the Model Score and cost views at https://t.co/oXl2bUb93H
Ripple-65B-Preview is a 64.8B dense model from @RicursiveAI, a US lab new to the board, scored on the same protocol as every other model. In our testing:
➡️ It finished 98.2% of the multi-step enterprise jobs, the highest rate of any open-weight row, ahead of Qwen3.8-Flash-Next (97.1%) and Beam-1.0 NVFP4 (96.1%), with the frontier tier at 96.7%
➡️ It scores 3,101 on the PINNACLE Model Score, the best result under 100B parameters, 22% fewer weighted errors than Qwen3.8-27B and within 5% of Muse Spark Open NVFP4 and GLM-5.2 at a twelfth of their size
➡️ On one 8× NVIDIA B300 node it holds 40 concurrent agents at 10 tok/s each, which prices a correct task at $0.39, 193 correct tasks per node-hour; the speed term is a single 172-attempt run and the row is a preview build
➡️ The NVFP4 build is not at parity with BF16. It scores 2,772 (97.5% jobs finished, 12.6% fabrication) at $0.34, 20% more throughput on the same node for an 11% lower score
The agentic half of the result is already there. Close the retrieval gap and this model moves well up the board.
Independent analysis from @Signal_65 shows nearly 2x modeled performance per rack for Arm AGI CPU vs. comparable x86 devices
Take a moment to hear what Ryan Shrout, Russ Fellows, Jeff DeFilippi, and Ravi Malhotra had to say about the results with @TheSixFiveMedia.
👀: https://t.co/AUbWmjs0Sp
How does a chip that’s 1.2x faster on average deliver ~2x the work per rack?
Because power — not processors — is now the limit. When capacity planning starts with megawatts, rack density becomes the number that decides how much agentic work your infrastructure can actually host.
That’s the story behind our new Lab Insight on the @Arm AGI CPU vs. a leading x86 competitor, and it’s the conversation @RyanShrout and Russ Fellows just had with Arm’s Jeff Defilippi and Ravi Malhotra on Six Five Media: how hyperscalers really do this math, how agentic benchmarks like SWE-bench and Terminal-Bench 2 are changing what we measure on CPUs, what Arm’s software ecosystem looks like in 2026, and when infrastructure teams can get hands on the silicon.
📷 Watch the conversation: https://t.co/pb94tZB6N8
📷 Read the full analysis (modeled rack results, per-workload data, methodology):
https://t.co/w8syF9woiR
I continue to believe that this sell-off of $INTC is pretty absurd. If you were betting on @Intel before this week, you were betting on FOUNDRY as the growth engine, with compute as the more modest impact piece. Nothing in that model changed this week. Certainly not by 30%!
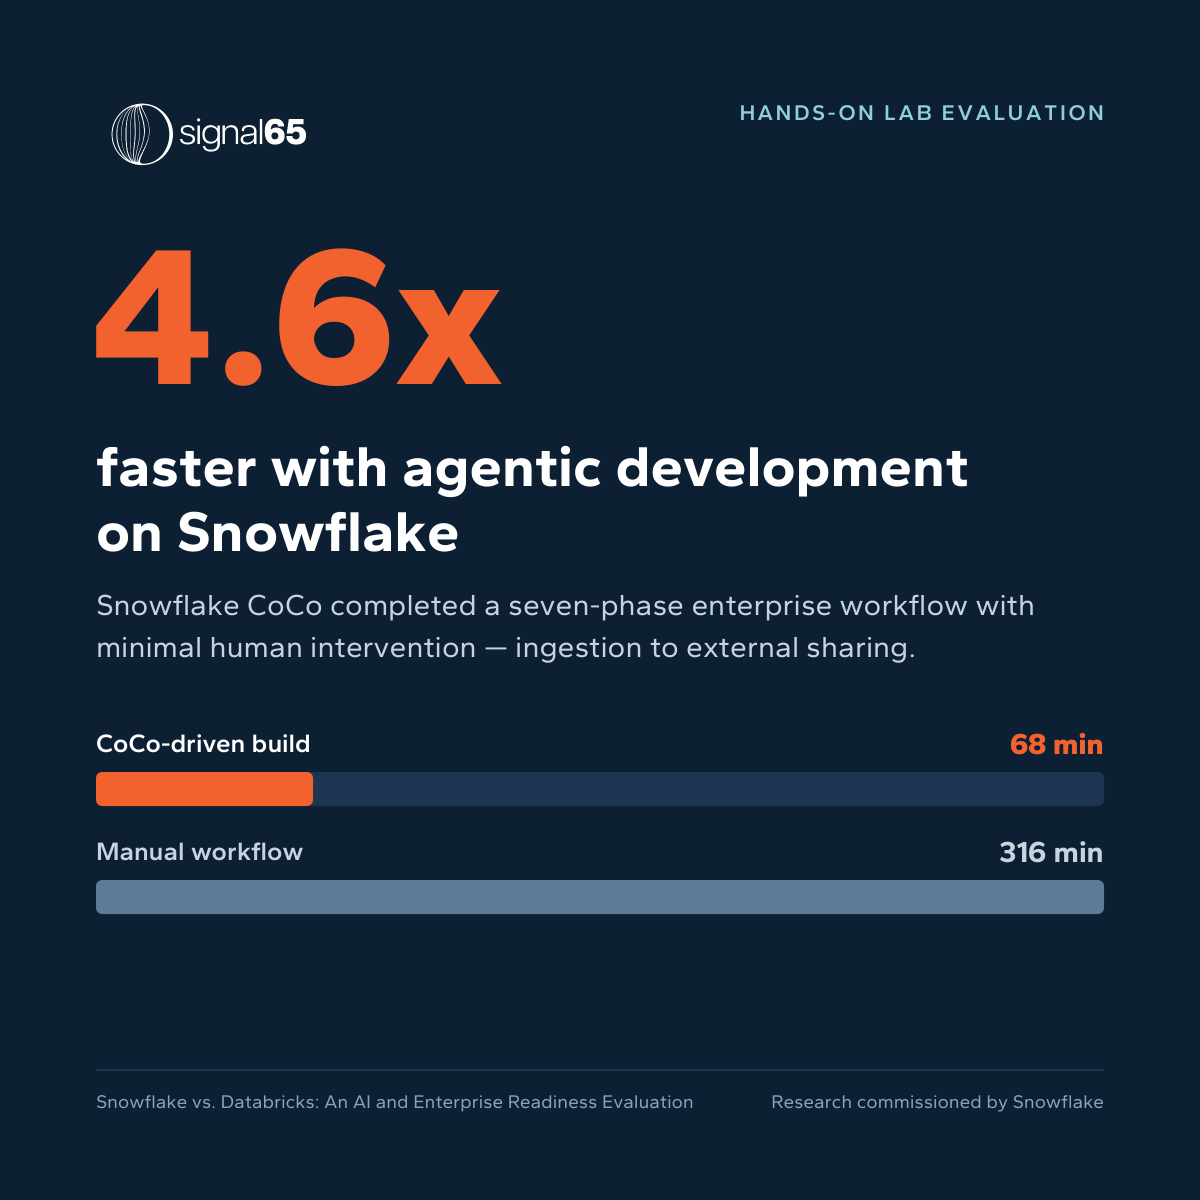
One enterprise workflow, two platforms, four test tracks. Snowflake’s CoCo agent finished in 68 minutes what took 316 manually — the full hands-on evaluation, commissioned by @Snowflake, is live:
https://t.co/oci63uIESR
Today we are launching the first major upgrade to @Signal_65 PINNACLE since it went live in August. The PINNACLE Coding Agent test is a separate score for whether a model can build the right software in a codebase it has never seen, graded by running what it builds, with a price on every passed job.
Coding agents are among the most useful tools to reach software teams in years, and anyone who has handed one serious work has watched it hand back a program that runs, passes its own tests but can miss the point, because the agent never worked out how the system is meant to BEHAVE. That failure is what this test is built to catch. In our testing one hosted model answers 97% of its samples correctly and passes none of its 30 complete jobs.
Three things I would pull out.
🟢 The best enterprise model is not necessarily the best coding model, and the two rankings part ways at the top.
🟢 Cost per passed job puts the failed tries in the bill, and the hosted frontier runs from $1.35 to $73.76 a passed open-ended job.
🟢 And the open models that pass fully scoped work for well under a dollar are the size that runs on a developer's own machine, which is where PINNACLE goes next client testing.
The full article, and the results views on https://t.co/1yYV0Tifzb, are here: https://t.co/AeXKldIMFK
In our testing Claude-Opus-5.5 at medium effort passes 70% of open-ended jobs, Gemini-4-Argon at high effort 67%, GPT-6-Astra 63% and GPT-6.1-Sol 57%, and with 30 attempts per hosted configuration the four intervals overlap. Below them Gemini-4-Argon at medium effort passes 43% and Claude-Sonnet-5.5 37%.
The open-weights leaders are closer to that tier than their enterprise results. GLM-5.3 at low effort passes 35% of Frontier Class jobs and DeepSeek-V4.1-Flash at max effort 32%, and each of them passes every Local Class job. Below that line most of the field passes no open-ended job at all, which is the reason the test has a fully scoped half, and it is where models sized for a PC and workstation show what they can do.
https://t.co/iapROJSZvz
Enterprises are handing coding agents real engineering work and choosing the model on benchmarks that basically just count passing unit tests. Those benchmarks do not see the failure every engineering team has met, code that runs and misses the point, and they say nothing about what a passed job costs.
Signal65 PINNACLE now has a Coding Agent test, published today beside the PINNACLE Model Score.
➡️ A model is dropped into a codebase it has never seen, with a business brief, 74K tokens of documentation and 7,200 seconds, and asked to build the software
➡️ Grading is all code. The program it builds is run on 200 unseen samples, every answer is recomputed, and the design is checked across samples, so a generator that never varies fails the job
➡️ Two classes of work, open-ended Frontier Class jobs and fully scoped Local Class jobs, weighted equally into one PINNACLE Coding Agent Score
➡️ The best enterprise model is not necessarily the best coding model, and the rankings part ways at the top of the field
➡️ One passed open-ended job costs from $1.35 to $73.76 across the hosted frontier, failed tries included, with open-weights models priced on a rented @NVIDIA B300 node
63 configurations, 3,690 Frontier Class and 3,660 Local Class attempts, developed in close partnership with @Kamiwaza.
Read the article and the results: https://t.co/iapROJSZvz
A model chosen on enterprise results and handed to an engineering team carries an assumption, that the capability transfers. In our testing it does not, and the cost of getting it wrong is an engineering team running on the wrong model for months.
The Signal65 PINNACLE Coding Agent Score is published beside the PINNACLE Model Score, and across the 57 configurations run at the same effort setting on both tests the two rankings agree broadly, a rank correlation of 0.88, and part ways at the top, among the models an enterprise is most likely to be choosing between.
Claude-Opus-5.5 at medium effort is fifth on enterprise work and first on coding. Gemini-3.8-Flash at medium effort is third on enterprise work and seventeenth on coding. GLM-5.3 at low effort is thirty-first on enterprise work and seventh on coding, passing every Local Class job.
The practical reading is to pick per workload, and the coding table carries both numbers for every configuration.
68 minutes vs. 316 minutes.
In an independent, hands-on evaluation, @Signal_65 found Snowflake CoCo completed a seven-phase enterprise workflow in 68 minutes, compared to 316 minutes via manual workflow. That’s 4.6x faster.
See the full evaluation: https://t.co/8s6rOCMSt9
Enterprises sizing an NVIDIA Nemotron deployment for agentic work now have a smaller option that holds the Nemotron-3.5 Super result.
Nemotron-3.5 Bolt 74B-A9B lands within 1% of Nemotron-3.5 Super on the Signal65 PINNACLE Model Score with 9B active parameters against 12B, finishing more of the multi-step enterprise jobs (52.5% against 50.7%) and 93.5% of the 128K retrieval corpus in our testing.
It makes 46% fewer weighted errors than Nemotron-3.5 Lightning and is the most token-efficient Nemotron-3.5 row on the board. Live on the Model Score view at https://t.co/oXl2bUb93H @nvidia@NVIDIAAI
Enterprises that passed on @deepseek_ai V4.1-Flash because it needed max reasoning effort to score well should look at the October refresh. DeepSeek-V4.1-Flash-1017 reaches the original's max-effort score at its default effort, sustains more concurrent agents on one node than any other model above a 4,000 PINNACLE Model Score, and lands on the open-weight cost frontier. In our testing:
➡️ At default effort the 1017 build makes 45% fewer weighted errors than the original V4.1-Flash at the same setting, and matches the original's max-effort result with 94% fewer output tokens per correct answer (20,829 against 347,031) in 27 median rounds instead of 43.5
➡️ Against the July V4-Flash-0731 it makes 33% fewer weighted errors, with fabrication on the 128K corpus down from 7.0% to 2.1%
➡️ On one 8× NVIDIA B300 node it holds 312 concurrent agents at 10 tok/s each, the most of any row above 4,000 on the board, which puts a correct task at $0.15 and 516 correct tasks per node-hour; Productivity #2 of 41 open-weight rows
➡️ That price lands it on the open-weight cost frontier, the cheapest open-weight correct task above 4,000, 28% less than Qwen3.8-Flash-Next for 84% of its score, and below GPT-6 Sol medium at a higher score
Hosted rows are a separate question: Claude Haiku 5.5 and GPT-6 Luna remain cheaper than every open-weight row on the overall frontier. For an enterprise committed to open weights, DeepSeek-1017 is the new price for a correct task at this level of capability. Live on the Model Score and cost views at https://t.co/oXl2bUbGTf
There was a lot of excitement this month for the release of the new @reflection_ai Beam 1.0 model, and we can confirm that it performs amazingly well on the Signal65 PINNACLE agentic benchmark suite and on our @nvidia B300 node!
Reflection AI's Beam-1.0 (501B total, 23B active) is the best US open-weight model tested, and the build an enterprise would deploy, the 4-bit NVFP4 repo, scores at parity with its FP8 and BF16 repos. In our testing:
➡️ Beam-1.0 NVFP4 finished 96.1% of the multi-step enterprise jobs and 96.2% of the 128K retrieval corpus with a 1.5% fabrication rate, landing fourth among 59 open-weight rows behind only Alibaba's Qwen3.8 family, at 88% of the Qwen3.8-2.4T-A95B score on a quarter of the active parameters
➡️ It makes 29% fewer weighted errors than the next US open-weight row (Meta's Muse Spark Open), 3% fewer than Claude Opus 5 and 15% fewer than GPT-6 Sol medium
➡️ The three precisions score at parity (jobs finished within 2 points, retrieval within 0.2, fabrication within 1.4, all inside run-to-run range), and the NVFP4 build holds 192 concurrent agents at 10 tok/s each on one 8× NVIDIA B300 node, which puts a correct task at $0.24, 2.5x less than Opus 5 at the full API bill
➡️ Among open weights only Qwen3.8-Flash-Next is both cheaper and higher ($0.21); among hosted rows only Claude Haiku 5.5 finishes a job for less at a higher score
Every Beam run passes the model's prior reasoning back on each turn of a tool-use job, as Reflection's developer guidance requires; without it the tool calls degrade over long tasks.
All three Beam rows are live on the Model Score view and the NVFP4 build on the cost view at https://t.co/oXl2bUb93H
Awesome to see the @Signal_65 performance data on @NVIDIA Vera being utilized by the one-and-only Dion Harris at @NVIDIAGTC in Berlin this week.
Source report found here: https://t.co/pyxQ1jMs3O