A 54% throughput difference on the same model and hardware is significant.
That’s exactly the kind of benchmark that deserves an independent reproduction.
The setup looks interesting, but verifying the numbers is the next step
Rework is inevitable in large-scale LLM pre-training and fine-tuning. What it costs isn't.
Introducing xLLM, an efficient and flexible infrastructure for pre-training and fine-tuning dense and MoE LLMs. It keeps key training decisions changeable without giving up throughput.
Efficient, at 6,295 tokens/sec per GPU on K2-Horizon-MoVA-36B-A4B and 10,050 tokens/sec per GPU on Llama3-8B on H200s.
Flexible, because the tokenizer, data mixture, model architecture, and training stages can change without rebuilding the dataset or the system around them.
xLLM ships with the checkpoints, training logs, and recipes behind K2 Horizon: https://t.co/FJ2mg3OMdb
K2-Horizon-MoVA-36B-A4B: https://t.co/lH2BYBdmaC
If this direction works, future model labs may look less like teams manually running experiments and more like systems coordinating thousands of machine-assisted research loops
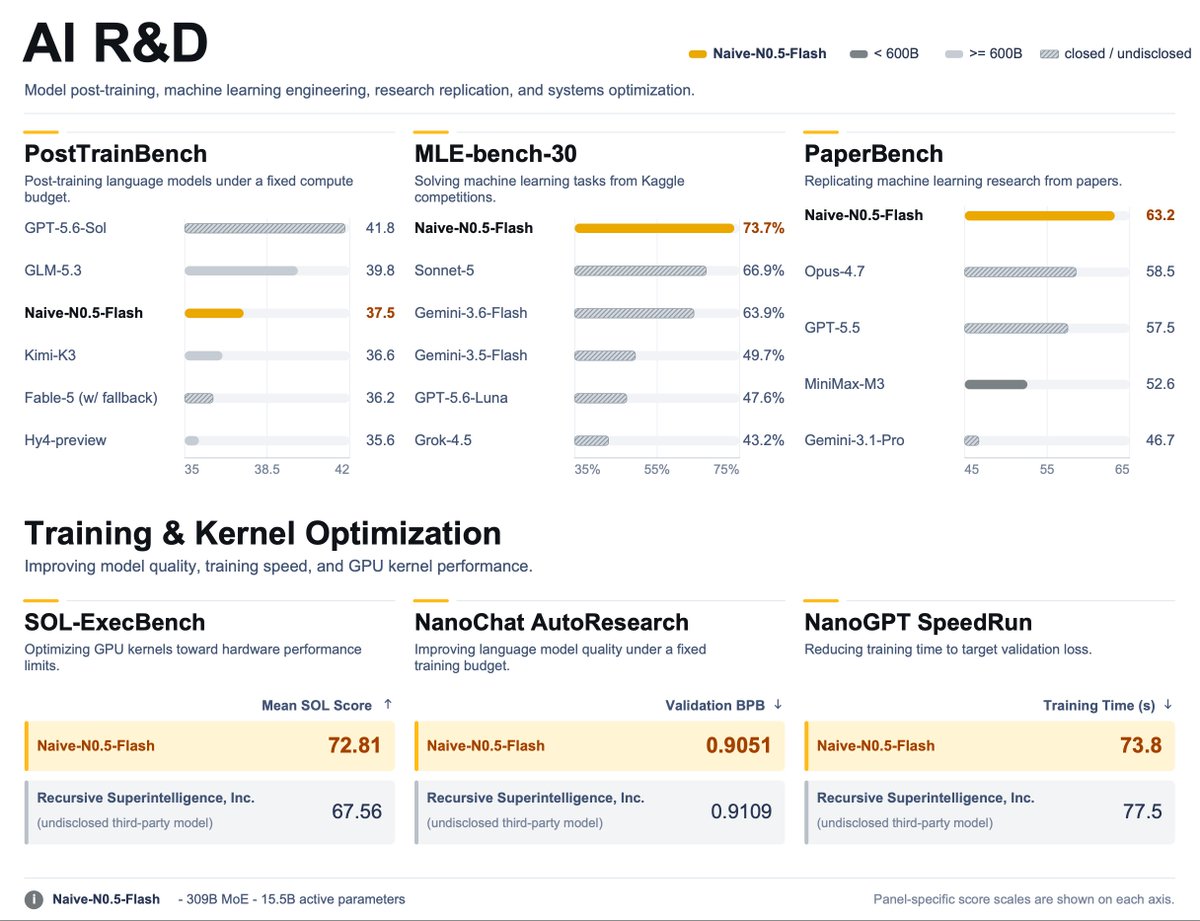
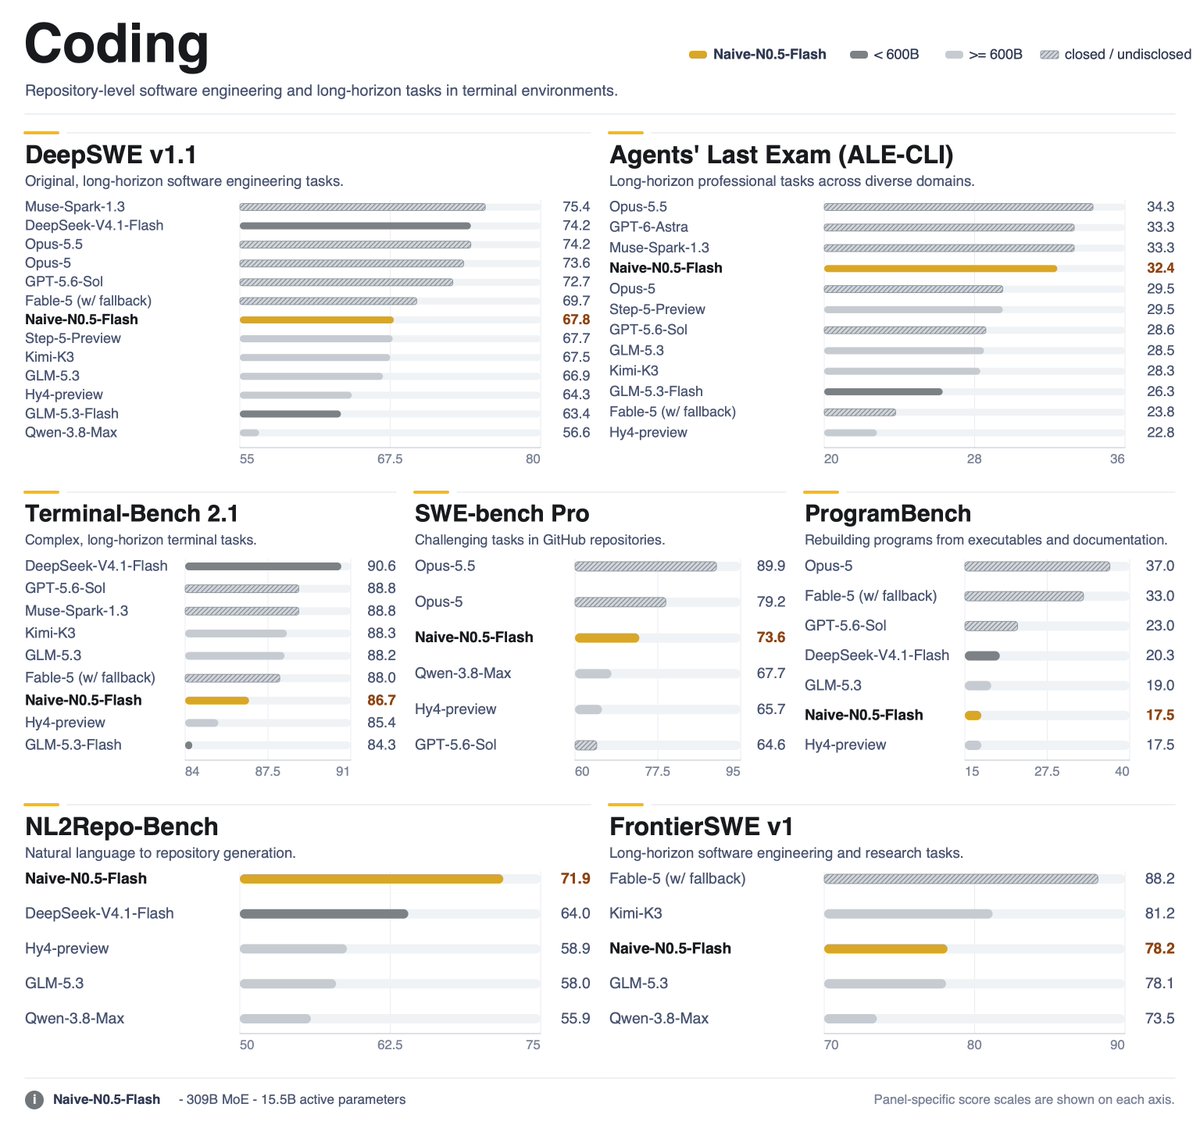
Introducing Naive-N0.5-Flash: Building Frontier AI with AI
🔹 309B MoE, 15.5B active: top-tier in coding, leading in AI R&D.
🔹 Native 1M context, no full-attention layers (hybrid SWA + DSA).
🔹 Inference runtime built by AI: up to 2,000 tok/s in Ultrafast mode.
Weights are open today under MIT license.
🔗 Tech blog: https://t.co/P1e8pBeJJM
🤗 Hugging Face: https://t.co/v2YvKfuguc
💻 GitHub: https://t.co/QjJ7cjFlkL
🌐 https://t.co/sIc7nZJH1L
You no longer need a scriptwriter + voiceover artist + editor + motion designer. Just PuppyDog. @AndrewyNg thought it was worth backing. Probably a good sign
Today we're introducing PuppyDog, the fastest way to make a professional product video with AI.
Record your screen. PuppyDog writes the script, narrates it, and turns it into a beautifully animated video. All in 5 minutes.
Try it: https://t.co/DyZdPKDhkm
Today we're introducing PuppyDog, the fastest way to make a professional product video with AI.
Record your screen. PuppyDog writes the script, narrates it, and turns it into a beautifully animated video. All in 5 minutes.
Try it: https://t.co/DyZdPKDhkm
if you tried hyperframes, you would know
the agentic video stack is being built on code-gen
but SWE-bench code v.s. code-to-video that feels alive are two different things
we built the Code2Video Bench, in collab w/ Google DeepMind & @Kaggle
frontier labs can finally get good at agentic video tasks
@Miriann_24@higgsfield forge00143(username)
That's my discord username
I have already sent you friend request kindly accept and let's have a chat please
🔥 Today, we are truly excited to announce our technical prototype, the Generative World Simulation system, which integrates JING(镜), an interactive experience model, with DAO(道), a computable shared-world engine.
The coupled model and engine connect first-person experience with a shared world that continues to evolve beyond any individual observer.
Conditioned on actions and observation history, JING enables agent navigate, manipulate, and communicate from a first-person perspective in the world. Watch our demo video to see it in action!
On the official WBench leaderboard as of September 17, 2026, XGEN-JING ranked #1 on the Full split, and #2 on the Navi split. 🎉
DAO maintains shared world state and rules, computes the consequences of actions, and provides JING with only what the current observer can perceive. It also supports autonomous agent decision-making, enabling agents to act independently within an evolving shared world.
Together, DAO and JING move beyond generating the next frame toward simulating the world behind it. This marks a small step towards OASIS: not just a world that responds to you, but a world—and a society—that evolves with and without you. 💪
Explore XGEN Labs~:
🔗 Website: https://t.co/tqTvPIk19B
🤗 HF: https://t.co/wxLRmJNYgO
🦊 GitHub: https://t.co/2DMvURLUsK