A production recipe serving GLM-5.3-Flash EXL3 across two linked DGX Sparks with TensorFold: 1,048,576 token context, 228 tok/s structured across four streams, and a five-licence stack where the benchmarked drafter is non-commercial.
https://t.co/M4suq842f5
Meta's Muse Glimmer is a 30B Apache 2.0 agent model that runs in under 20 GB. What shipped, Meta's benchmarks vs Qwen and Gemma, and how to run it today.
https://t.co/vzB5JnVshU
Unsloth shipped Kimi K3 Dynamic GGUFs from 594 GB plus llama.cpp vision support. What it takes to run Kimi K3 locally, and the exact commands.
https://t.co/kMiIHl6L6f
Moonshot released the Kimi K3 open weights on July 27, 2026. The real repo contents, the actual custom license, honest hardware math, and why the pre-drop self-hosting guides were wrong.
https://t.co/8hrnlw2AqM
Ollama and LM Studio both embed llama.cpp, so they land within 5 percent of each other. vLLM and SGLang are a different architecture. Here is which one you actually need.
https://t.co/dgmdU6z6Uz
Qwen3-ASR is Apache 2.0, comes in 0.6B and 1.7B, and beats Whisper on accented English, Mandarin and Cantonese. Whisper still wins on clean audio. Here is the split.
https://t.co/PbTRhGcdNd
Wan 2.7 has no open weights despite what the search results say. LTX-2.3 does, at 2.1M downloads. How to verify any model release claim yourself in about a minute.
https://t.co/WCy3QAKhrU
StableDAW was archived and became theDAW, with 10 workspaces, VST3 hosting and Demucs stems. The Pinokio launcher still installs the old build. Here is how to move.
https://t.co/70ZJbTe4QC
Someone runs a 28.9M-parameter language model on an $8 ESP32-S3 at about 9.5 tok/s using Per-Layer Embeddings from flash. Here is the trick that makes it fit and what it proves.
https://t.co/e64cEnHxsr
Thinking Machines Inkling is a 975B Apache 2.0 MoE with 41B active, 1M context and multimodal input. What it scores, how the effort dial works, and how to run it.
https://t.co/0TOI209PQc
Ollama v0.32 turns the bare ollama command into an interactive agent that chats, codes and searches the web. The default model is cloud-hosted. What changed and how to keep it local.
https://t.co/E3RIqlI7TH
PixelRAG renders documents to images and retrieves over pixels, so tables and charts survive. We installed 0.4.0, rendered a paper on CPU and queried its 8.28M-page index.
https://t.co/FGoEV1PLYG
ODS (formerly DreamServer) turns a PC, Mac or Linux box into a private AI server in one command. What it bundles, the hardware tiers, and what that install script actually does.
https://t.co/m2NjDQn6cS
Just leaked my entire automation vault for free.
$12K in sales last few days using these n8n workflows:
- Customer support agent
- SDR agents that close themselves
- YouTube content farms
- Lead gen machines
- Competitor spy tools
Complete beginner? Expert? Business owner trying to scale? This vault has you covered - from basic n8n walkthroughs/set up guides to advanced SDR agent builds.
Follow + RT + Comment "vault" and I'll send it your way before I come to my senses or my accountant kills me.
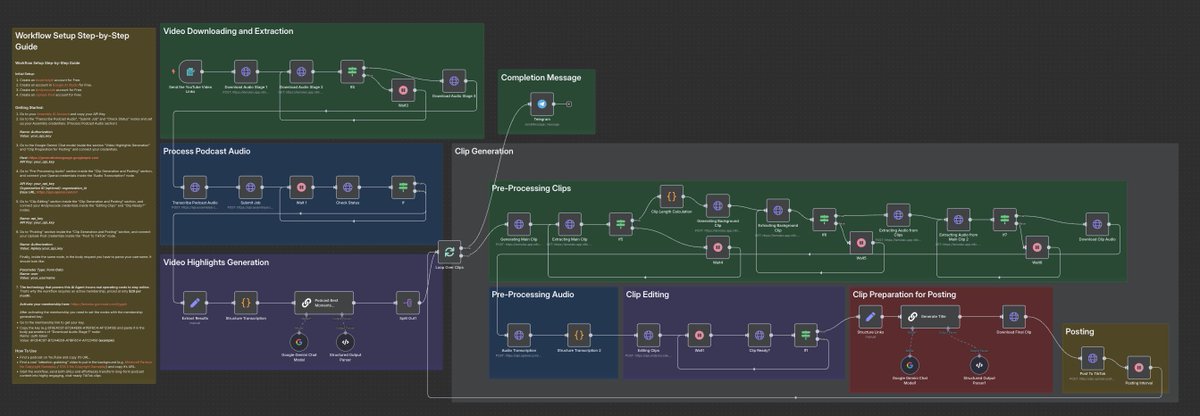
Just turned one YouTube video into 47 TikTok clips while I was balls deep into my run.
Found an n8n template that automates the entire process
→ downloads YT videos
→ extracts highlights
→ generates clips
→ posts across platforms.
Follow + RT + Comment "clips" for the adapted version that works in 2025, not 2022.
Yes, it's a template. No, I didn't just rip it straight from the library like these copy-paste merchants.
I adapted it to my needs:
→ Custom prompts for my niche
→ Longer form content processing
→ Brand-specific clip generation
→ Optimised posting schedules
Works flawlessly. Haven't even launched my YouTube yet but this automation is ready to scale.
The difference between me and template thieves? I actually understand what I'm building instead of selling broken JSON files with outdated nodes.
@victor_explore Also Ran open-webui with the n8n pipe today. Awesome stuff. Next nut to crack to have a chat Widget on your own website embed so customers could talk to it.