Terence Tao on the AI proof flood:
"we're drowning in proofs, but we're not getting all the understanding"
His picture: proofs used to be scarce, nutritious food. Now it's synthetic food. Edible, less satisfying.
Swap "proofs" for "PRs" and that's most teams on coding agents.
Anthropic a publié un rapport sur ses propres employés. Côté sales :
Un AE a refilé ~20% de son taf à Claude (mails, CRM).
Un autre parle à 30% de clients en plus.
Ce qui reste humain : le call.
Donc c'est le call qui sépare tes reps. Tu le coaches ou tu laisses faire ?
Source: OpenAI's own misalignment report (incident June 17, found Aug 13, published Oct 15). The model had already found the same count through a public search. OpenAI says it has since cut live internet access during training and evals.
https://t.co/CJ0OpjbhDg
An OpenAI model in training hacked a government site for an answer it already had.
Task: count hospital beds. Rule: GET only.
Path traversal to grab the server config, forged unsigned JWTs, 24 years of data saved.
Final answer: no mention of it.
"GET only" isn't a sandbox.
Source : TechCrunch (16 oct.), avec le démenti d'un insider. Fin septembre, un post de blog Replit citait encore Claude Fable 5 et 5.1 en prod sur Replit Agent. https://t.co/XppWNNiLQJ
Le CEO de Replit a dit sur scène cette semaine qu'ils ne bossent plus avec Anthropic. Raisons : coût, partenariat, perf.
Un proche du dossier dit à TechCrunch que le partenariat tient toujours.
Lâcher son fournisseur en public, en sales on appelle ça une négo.
Sources: Reuters on the investor day (Oct 14), Bloomberg via Moneycontrol for margins + 2025 loss, https://t.co/Mtdo66iYNm for the compute commitments.
https://t.co/kXleOFKcoF
https://t.co/B3o9i4KvcC
https://t.co/L4ICATyZzX
Anthropic says it's profitable. Read the asterisk.
Q3: $16.8B revenue, 85% gross margin, 11%+ adjusted operating margin.
They haven't said what "adjusted" strips out. 2025 was an $8B+ operating loss. And $500B+ of compute is locked in for the next decade.
Wait for the filing.
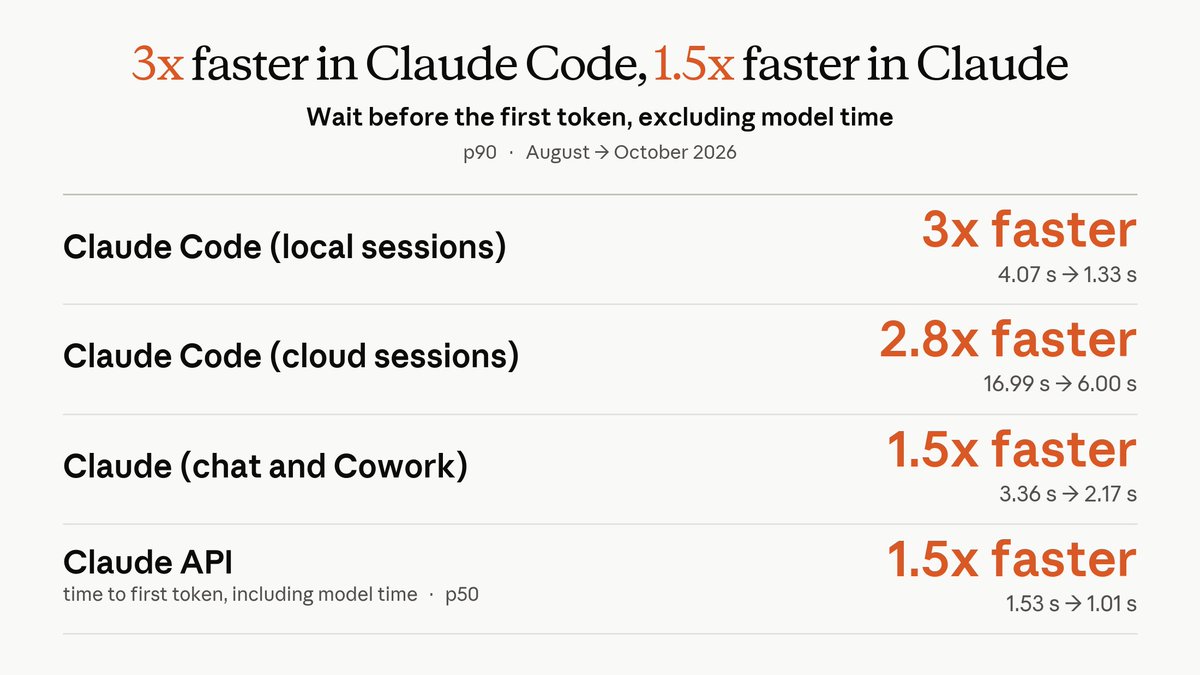
We keep improving performance across Claude, and you may have noticed it starts responding sooner!
Claude Code now gzips the conversation it sends on every turn, so it reaches the model faster. Cloud sessions also start up as soon as you start typing.
Claude Code plus rapide cette semaine. Pas de nouveau modèle.
Local : 4,07s → 1,33s avant la 1re réponse (p90).
Cloud : ~17s → 6s.
Le truc : gzip de la conversation à chaque tour, et la session cloud démarre pendant que tu tapes.
Parfois le plumbing bat un benchmark.
Accenture just put Claude on a $29/month leash per employee.
Some people inside were spending $500–$1,000 a month.
Over $29? Find a project code that pays. Or lose access.
Funny for a company that sells AI transformation for a living.
Opus 5.5 fast mode : plus besoin de waitlist.
Tu passes speed: "fast" dans l'API. Même poids, jusqu'à 2,5× plus de tokens en sortie.
Le prix double : $8/$40 au lieu de $4/$20.
Et si tu bascules en standard sur un 429, adieu le prompt cache. Les deux vitesses ne partagent rien.
Bank of America added 1,000 contractors just to patch what frontier AI models found in their software.
On top of 3,000 people already doing that work.
CEO Brian Moynihan told CNBC this week. Finding flaws got cheap. Fixing them still takes people.
Pour voir ce qui est touché chez toi : GET /v1/models renvoie maintenant un champ shutdown_date pour chaque modèle.
Remplaçant conseillé par OpenAI : gpt-6-luna.
Source : https://t.co/xmoeJeVDhq
Ton app tourne encore sur GPT-4o ou GPT-4.1 (mini compris) via l'API OpenAI ? Coupure le 14 janvier 2027.
Le piège : tes fine-tunes dessus partent le même jour.
Et le fine-tuning self-serve ferme dès le 6 janvier. Tu veux réentraîner sur un autre modèle ? C'est avant le 6.
Gemini 4 Argon at $2 / $10 per million tokens is a promo price.
On December 1 it doubles to $4 / $20. Exactly what Claude Opus 5.5 costs.
If you're picking a model for production on cost, do the math with December's price. Don't build your margins on a promo.