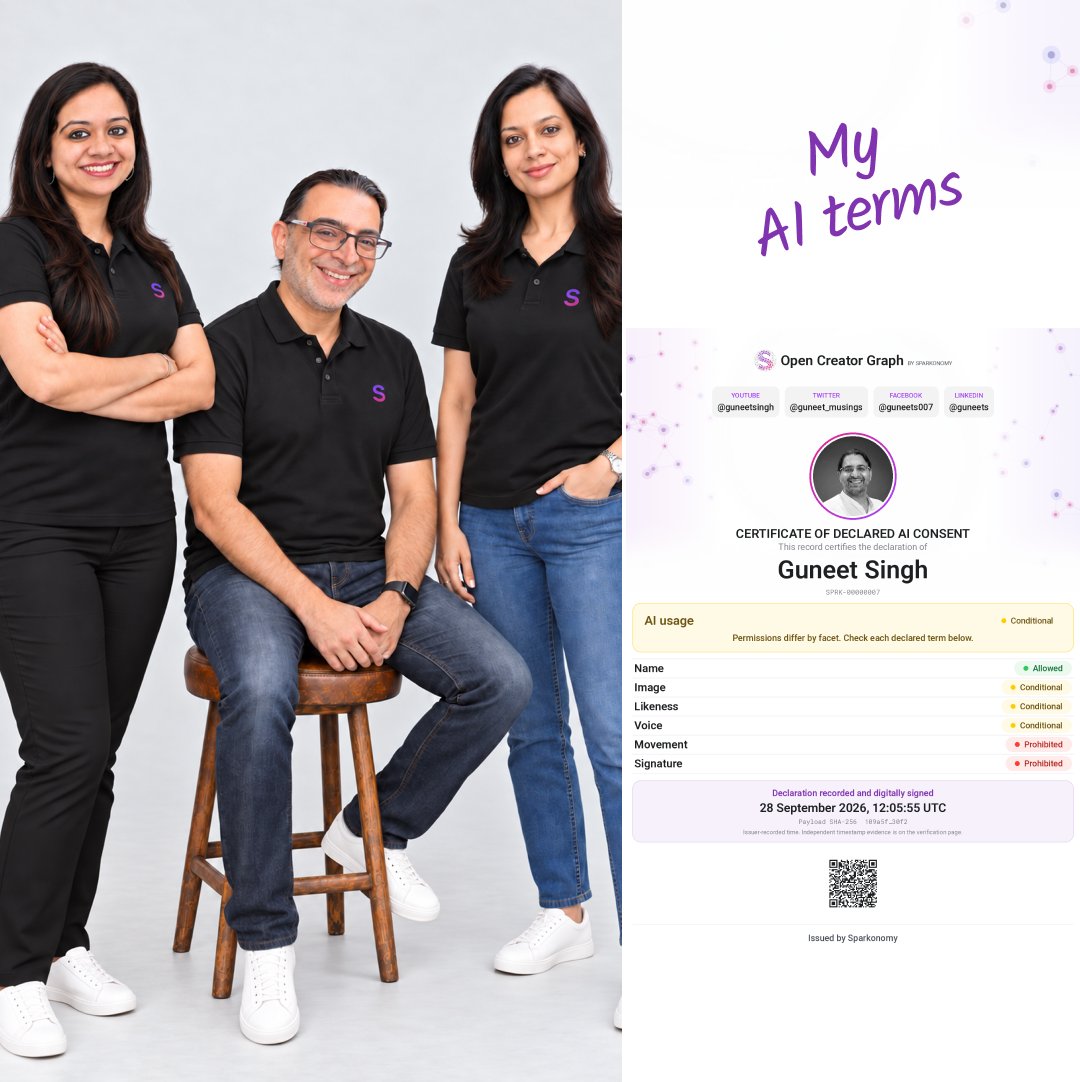
Different AI tools can describe the same Creator differently. That can change who gets discovered, shortlisted, and contacted. Check how AI sees you: https://t.co/Dz2twqOG91
The scariest part of AI misrepresentation is that Creators may never know it happened.
A brand asks AI, a shortlist gets built, one wrong fact removes you, and your phone stays quiet.
A Creator can fit the brief perfectly and still never make the shortlist if AI gets their city, category, or follower count wrong.
Sparkonomy’s AMISS found conflicting facts across AI models for 93.6% of Creator profiles tested.
24 hours. 9 countries. LinkedIn #2 after Instagram. 💜
We may not call ourselves Creators. But we edit posts, pick photos, put our names out there.
That’s our public identity. It deserves AI terms too.
I set mine. Set yours on Open Creator Graph: https://t.co/JV72GERQ1e
Many of you still think I’m at Google. I left to chase a spark. ✨
After more than a year in stealth, today @SparkonomySays goes live. 💜
With @Megha2511 and @TheVipashaJoshi , I’m building for the person behind the next swipe: the Creator. 1/3
1/5
AND… WE’RE LIVE. 💜
After a year of quietly building, breaking, and testing alongside creators:
@SparkonomySays is officially out of stealth.
This story didn’t start with AI. It starts with the Creator. 🧵👇
2/5
Creators have built media businesses the world pays attention to - largely solo.
Yet the infrastructure around them hasn’t caught up.
Our ambition at @SparkonomySays : Put an AI-powered team behind every Creator.
We’re out of stealth. 💜
After a year of building quietly, @SparkonomySays is live.
With @GuneetSingh and @TheVipashaJoshi, we're building on one belief: Creators build businesses. They deserve infrastructure matching their ambition.
Open Creator Graph is our first step. 1/3
JUST IN - Asia
Singapore's @SparkonomySays launched the Open Creator Graph, a free platform letting creators set machine-readable terms for how AI uses their identity. Founded by @guneet_musings, Megha Thareja Tyagi, and Vipasha Joshi, it includes 1 million creator records available to claim worldwide.
@SparkonomySays launches Open Creator Graph, giving creators a free, cross-platform way to establish their identity and declare AI-use preferences for their name, image, voice and likeness.
Read more :https://t.co/qtHoVADFUn
#Sparkonomy#OpenCreatorGraph#AI
Facebook creators: Meta says public posts, photos and videos may be used to improve its generative AI.
In some regions, you can object. We mapped the steps, form and limits here:
https://t.co/SC2fdfyCNA
Creators can’t just make Facebook private. Brands need to find their work. Meta can use public posts to train AI.
EU/UK users can object; India has no guaranteed route.
Video guide: https://t.co/SC2fdfy4Y2
AI can now dream.
Claude’s AutoDream is a sleep cycle for memory, built on Auto Memory.
Its job is simple: clean up, merge and prune memory so it stays useful.
We’re feel this at @SparkonomySays .
Memory drifts, duplicates and gets expensive.
AI needs to DREAM!
• @SparkonomySays: Creator-to-brand matching with a unified “Creator Genome” from videos + images + audio (70% lower latency)
• @everlaw: Legal discovery across millions of docs, diagrams, photos & exhibits (20% recall lift)
𝗣𝗼𝗶𝗻𝘁 𝟯: 𝗠𝗮𝘀𝘀𝗶𝘃𝗲 𝗥𝗲𝘀𝘂𝗹𝘁𝘀
Sparkonomy reports text-to-video similarity scores doubled from 0.4 to 0.8.
Everlaw is seeing huge jumps in precision and recall across millions of records. This is a new performance floor.
#BigData#SearchEngine
Here are real-world use cases for Gemini Embedding 2:
- Legal discovery (Everlaw): Embed docs, images & videos across millions of records for faster, precise searches in litigation.
- Creator platforms (Sparkonomy): Index video/images/text to match brands with creators—doubles semantic similarity, cuts latency 70%.
- Wellness apps (Mindlid): Combine conversational text with audio/visual embeddings for 20% better recall in personalized Q&A.
More: Multimodal RAG for e-commerce (image+text product search), healthcare (scans+notes clustering), content recs in media apps. Try the demo!
💎İşin teknik boyutunda devasa bir yanlış fiyatlama düzeltmesi var. Sparkonomy'nin verilerine göre, LLM çıkarımının devreden çıkmasıyla gecikme %70'e kadar azalıyor.
🛡️Metin-görüntü eşleşmesinde anlamsal benzerlik skoru 0.4'ten 0.8'e sıçrıyor. Bu, veri analizindeki en büyük zamanlama uyumsuzluklarından birinin bitişidir.
👇👇👇