Congratulations @Srivatsan91 for driving this effort with other collaborators and the rest of the community. Interested to hear more about this effort (https://t.co/L2N7Eb7Z82), please fill out this form (https://t.co/ChU8Cb3Uur) and stay tuned for a virtual workshop in August!
Multi-Agent Reinforcement Learning for Microprocessor Design Space Exploration, Krishnan et al., Oral #MLSyS, https://t.co/3A2ysmjYyD
Hardware architecture design is a search over a complex interconnected system. #MARL brings up 60x improvement over single RL agents.
Thanks @Aleksandra, @profvjreddi, @gbarthmaron for your guidance.
Very excited to share our work on applying quantization to speed up RL and reducing carbon footprint. Thanks to my co-authors Max Lam, @sharad24sc,@ZishenW.
Very excited to share this work that with a simple idea reduces carbon footprint of training RL model by up to 3.8x w/ @Srivatsan91 , @profvjreddi, and other collaborators from @hseas and @DeepMind.
For quads it is even more sensitive to “unneeded” mass: be it onboard compute, sensor, or battery. Thanks @elonmusk for talking about this! Given your attention to these details..I am not surprised why your products are so amazing!
@elonmusk You hit the nail on the head. This is so true! “Carrying unneeded payload mass” and its impact on acceleration and overall efficiency of autonomous vehicle is so spot on. We realized this when exploring specialized chips for autonomous quadcopter:https://t.co/lJ2L2jTR4r
@wholemars We could’ve made a 600 mile Model S 12 months ago, but that would’ve made the product worse imo, as 99.9% of time you’d be carrying unneeded battery mass, which makes acceleration, handling & efficiency worse. Even our 400+ mile range car is more than almost anyone will use.
The only question reviewers should be asking themselves:
"Is the community better off with this paper, or without it?"
inappropriate reasons for rejection include: not beating SOTA, bad writing, minor flaws, no theory yet good results, incomplete citations (easily fixed),.....
Happy to see RL, robotics, and system architecture come together to enable easier and safer training. Thanks @Srivatsan91 et al.
Full paper @MLJ_Social:
https://t.co/vR3wqK54LS
I find the following type of review of most irritating: "I find the results in this paper not surprising." If you want to be entertained, please watch a movie:-)
Congrats to @Srivatsan91 and co-authors -- our paper "The Sky Is Not the Limit: A Visual Performance Model for Cyber-Physical Co-Design in Autonomous Machines" was selected a Best of IEEE Computer Architecture Letters in 2020.
https://t.co/dPZk7GoFlB
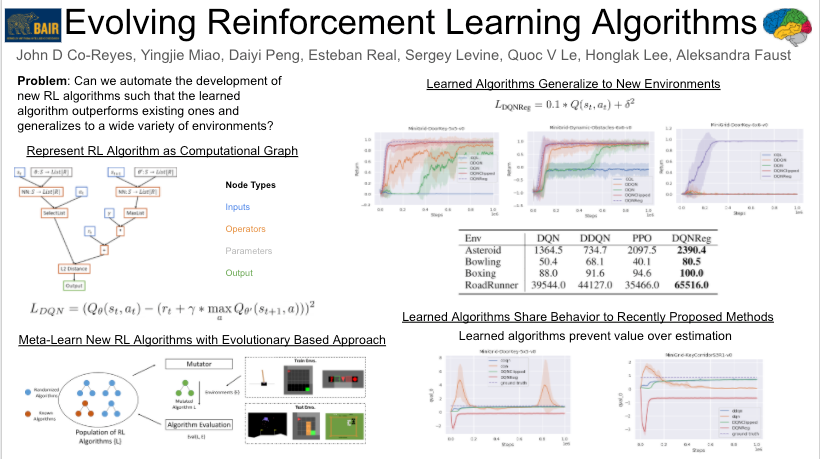
Can we learn RL algorithms that outperform existing ones, generalize to a wide variety of environments, and can be analyzed?
Evolving Reinforcement Learning Algorithms
Friday @ Deep RL Workshop at @NeurIPSConf
Room: B.b6, 12:30-13:30 and 18:00-19:00 PT.
.@DeepMind's incredible AI-powered protein folding breakthrough will help us better understand one of life’s fundamental building blocks + enable researchers to tackle new and hard problems, from fighting diseases to environmental sustainability.
https://t.co/kpr8EAx34h
@kchonyc During my PhD I
- got married (admittedly, right at the beginning)
- moved
- had a baby
- did not write every day
- was pretty terrible at making deadlines for myself
- PhD support groups didn't exist
I did maintain a healthy social life, at least until the baby was born.
Quantization effects on deep reinforcement learning using Quantized Reinforcement Learning (QUARL). Amazing research work by @Srivatsan91@sharad24sc, Maximilian Lam, Zishen Wan, @AleksandraFaust, and Vijay Janapa Reddi
https://t.co/wVi4ga0DNh
Check out #AirLearning, RL on edge research platform. Extends #AirSim and @OpenAI Baselines with Hardware-in-the-Loop (#HIL) and adds an environment generator for domain randomization.
w/ @Srivatsan91@zaaddan
https://t.co/ZugqYUzM9j