SurrealDB 4 is here. The database and memory for every agent. And with it, SurrealDB Earth. Serverless SurrealDB, built on @Cloudflare, that scales to as many agents and users as you need, wherever they are.
Start free on Earth, no card needed. 👉 https://t.co/fsBWd15CAa
The SurrealDB Startups Programme: $5,000 in credits for Agent Memory, Earth on @Cloudflare, Cloud or Enterprise.
Plus:
- A Solutions Engineer to help design and build
- A support plan
- Launch partnering and co-promotion
Apply. 🔗 https://t.co/VRXNpgPzUa
What if every user, customer, or AI agent had its own database? On 18 Nov, @tobiemh and Stu Schwartz unpack what’s new in SurrealDB 4, then @at_chiru demos it live on SurrealDB Earth, with Q&A to close.
Further details. 👉 https://t.co/1nx2ycTQw1
Build real-time apps for users anywhere in the world with Live Queries on @SurrealDB Earth, powered by @Cloudflare.
Try now for FREE: https://t.co/ykyNtXZtqW
A database for each customer. Memory for an AI agent. Different ways to build with @SurrealDB 4.
I’ve put together a walkthrough with real queries and what they return. 🔗 https://t.co/3o15s8NSPA
An agent’s memory needs more than vector search, it needs hybrid retrieval.
With SurrealDB 4, you can retrieve by meaning, follow connections and match exact words in one SurrealQL query and one transaction. See the query and what it returns. 👉 https://t.co/ndqTopKA78
What went into SurrealDB 4? Rebuilt query core and storage backends, 240+ fixes, and 4,500 test files run on every change. @tobiemh shares the work behind the release. 👇
When we first started building SurrealDB, I didn’t know the monumental effort needed to achieve our vision. Building for AI agents or a billion people asks a lot of a database.
Today, I can say we’ve achieved it with SurrealDB 4. New query core, 240+ fixes, 4,500 test files on every change.
🔗 https://t.co/uM7zFfmnDk
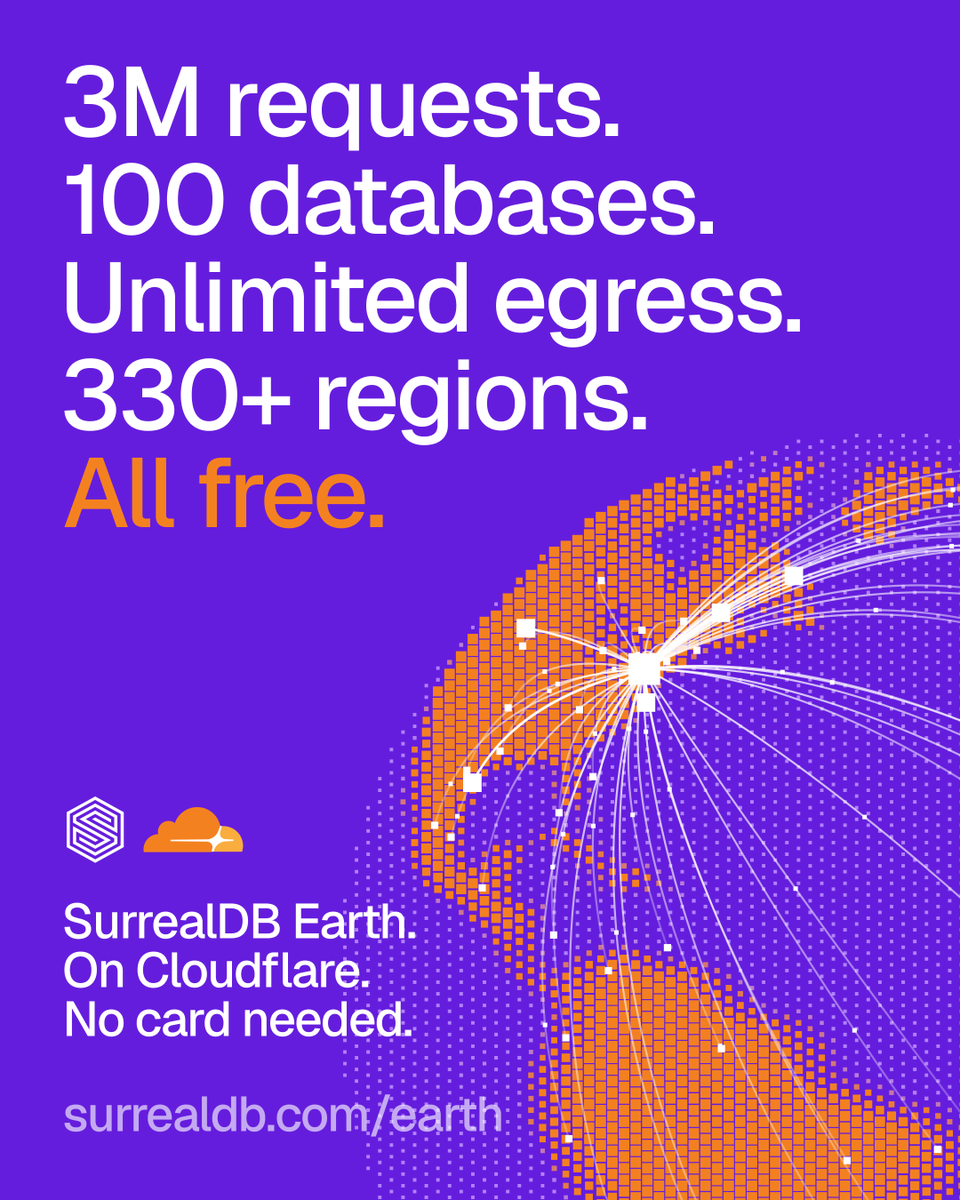
We put SurrealDB on @Cloudflare Workers and made it free.
3M requests. 100 databases. Unlimited egress. 330+ regions.
No card needed.
🔗 https://t.co/Ssh4sQcf1v
Come talk to us on Discord about SurrealDB Serverless, Cloud or Agent Memory. We're giving away 3 x Discord Nitros every week to interesting people.
https://t.co/Ap09rbQn95
Weekly Changelog
- SurrealDB v4: the database and memory for every agent, with PostgreSQL and MySQL SQL support
- SurrealDB Earth (beta): serverless SurrealDB on Cloudflare, with a database for each agent, user or customer
- SurrealDS, fault-tolerant distributed storage for SurrealDB Cloud Scale and Enterprise
- SQL drivers for JavaScript: @surrealdb/pg and @surrealdb/mysql, compatible with Drizzle, Kysely and Prisma
- SurrealDB Cloud CLI v1.1.0: deploy Earth instances and connect in one command
- JavaScript SDK v2.2.1 & v2.2.2, with SurrealDB v4 support
- Python SDK v3.0.0: live queries, auto-reconnect, transactions and a query builder
- Java SDK v2.2.0: RocksDB and gRPC connections, and live query diffs
- Go SDK v2.0.0, with SurrealDB v4 support
- SurrealKit rc.1 supports SurrealDB v4
- New explore pages and agent skills in SurrealDB Labs.
One agent is manageable. But a fleet of agents is where the hard problems start. Join us in London with @mastra on November 24 for talks and live demos on shared state, agent identity, and coordination.
Register now. 👉 https://t.co/AN9irzEvQc
Most databases are sized for their busiest hour and paid for every other hour too.
SurrealDB Earth is sized for this second. Its cells on @Cloudflare follow the load, from 100,000 transactions per second to zero.
Scale up. Scale down. Zero effort.
🔗 https://t.co/m9L1h7eYQu
One query. Thousands of compute units. One answer.
A SurrealDB Earth query is split across thousands of database compute cells on @Cloudflare and merged into one result, every leg reading the same point in time. 10+ billion peak rows per second, fully transactional.
🔗 https://t.co/2gdpUJGIhK
A database for every agent, and one that scales out when it needs to. @drewonfinal shows how SurrealDB Earth reaches 10+ billion peak rows per second, fully transactional. 👇
Serverless databases have a reputation for being the small, convenient option, not the fast one. I wanted to see how far I could push that.
This week we launched @SurrealDB Earth, serverless SurrealDB on @Cloudflare. It starts when a query arrives and scales to zero when nobody is using it. So I pointed it at 5 billion rows and asked it to count them.
In a single second, it read more than 4.5 billion of them. That is over 90% of the table, more than 350 GB of data, in one second. Every number here is from a real run, not a projection.
There was no cluster to provision and nothing to size. The parallelism appeared the moment the query needed it and was gone the moment it finished. And it is the full SurrealDB engine, with ACID transactions.
It is not perfect yet. 99.6% of the work finishes fast, but the slowest 0.4% still drags the full count out to several seconds. I know why, and my target is the entire query in under 2 seconds.
Honestly, I still find it hard to believe. I am convinced this design has orders of magnitude left in it, on reads, on writes, and in places I have not talked about yet. I will be recording a video soon with much bigger numbers.
The small, convenient option just got very fast.
I am really proud of what this team has built 🌍