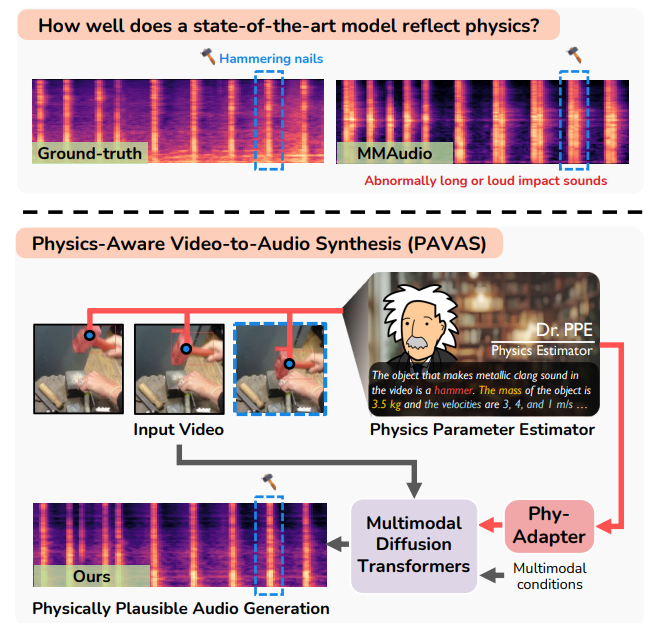
🎉PAVAS, a framework for generating physically plausible audio from video, by integrating physics estimation at #CVPR2026!
Led by our intern Hyun-Bin Oh (https://t.co/VpKVdmSFqN), in collaboration with @kamitsutoshi, @Tae_Hyun_Oh, and @mittu1204.
🎧&📝: https://t.co/PDsr1MSerq
𝗘𝗟𝗜𝗧𝗘, 𝗼𝘂𝗿 𝗿𝗲𝗰𝗲𝗻𝘁 𝗽𝗿𝗼𝗷𝗲𝗰𝘁 𝗼𝗻 𝗵𝗶𝗴𝗵-𝗳𝗶𝗱𝗲𝗹𝗶𝘁𝘆 𝟯𝗗 𝗚𝗮𝘂𝘀𝘀𝗶𝗮𝗻 𝗮𝘃𝗮𝘁𝗮𝗿 𝘀𝘆𝗻𝘁𝗵𝗲𝘀𝗶𝘀 𝗵𝗮𝘀 𝗯𝗲𝗲𝗻 𝗮𝗰𝗰𝗲𝗽𝘁𝗲𝗱 𝘁𝗼 𝗖𝗩𝗣𝗥 𝟮𝟬𝟮𝟲!
💡𝗧𝗟;𝗗𝗥
We study a mutually reinforcing synergy of 2D & 3D face priors (generative & data priors) to tackle the longstanding challenge in monocular synthesis of animatable, photorealistic 3D face avatar — Balancing between in-the-wild generalization and efficient synthesis.
𝗘𝗟𝗜𝗧𝗘: 𝗘𝗳𝗳𝗶𝗰𝗶𝗲𝗻𝘁 𝗚𝗮𝘂𝘀𝘀𝗶𝗮𝗻 𝗛𝗲𝗮𝗱 𝗔𝘃𝗮𝘁𝗮𝗿 𝗳𝗿𝗼𝗺 𝗮 𝗠𝗼𝗻𝗼𝗰𝘂𝗹𝗮𝗿 𝗩𝗶𝗱𝗲𝗼 𝘃𝗶𝗮 𝗟𝗲𝗮𝗿𝗻𝗲𝗱 𝗜𝗻𝗶𝘁𝗶𝗮𝗹𝗶𝘇𝗮𝘁𝗶𝗼𝗻 𝗮𝗻𝗱 𝗧𝗘𝘀𝘁-𝘁𝗶𝗺𝗲 𝗚𝗲𝗻𝗲𝗿𝗮𝘁𝗶𝘃𝗲 𝗔𝗱𝗮𝗽𝘁𝗮𝘁𝗶𝗼𝗻
🔗 𝗣𝗿𝗼𝗷𝗲𝗰𝘁 𝗽𝗮𝗴𝗲: https://t.co/gsbkL5lYeC
📄 𝗣𝗮𝗽𝗲𝗿: https://t.co/sJGGGHRQ7p
ELITE was a project that I've worked on with all my heart, and thanks to my collaborators' tremendous efforts and their patience. Huge congrats to my coauthors: Lee Hyoseok, Subin Park, @GerardPonsMoll1 , @Tae_Hyun_Oh
Now that we have building blocks for "𝙥𝙝𝙤𝙩𝙤𝙧𝙚𝙖𝙡𝙞𝙨𝙩𝙞𝙘" and "𝙨𝙤𝙘𝙞𝙖𝙡" world simulations. What'll be the next steps? 🧐
The work is led by the amazing Sungbin Kim https://t.co/IMN9ZyYhPs, and collaborated with Jeongsoo Choi, Joon Son Chung, @Tae_Hyun_Oh, David Harwath
Checkout https://t.co/LEBteX4JSz for more samples, and the forthcoming code and model!
The work is led by the amazing Sungbin Kim https://t.co/IMN9ZyYhPs, and collaborated with Jeongsoo Choi, Joon Son Chung, @Tae_Hyun_Oh, David Harwath
Checkout https://t.co/LEBteX4JSz for more samples, and the forthcoming code and model!
At #ICLR2025, we will present "NeuFace: A Large-Scale 3D Face Mesh Video Dataset via Neural Re-parameterized Optimization."
📌 Hall 3 + Hall 2B #69
📅 Thu, Apr 24, 3:00–5:30 pm Singapore Time
I'd really like to meet & discuss with fellow researchers. Let's connect!
(1/3)
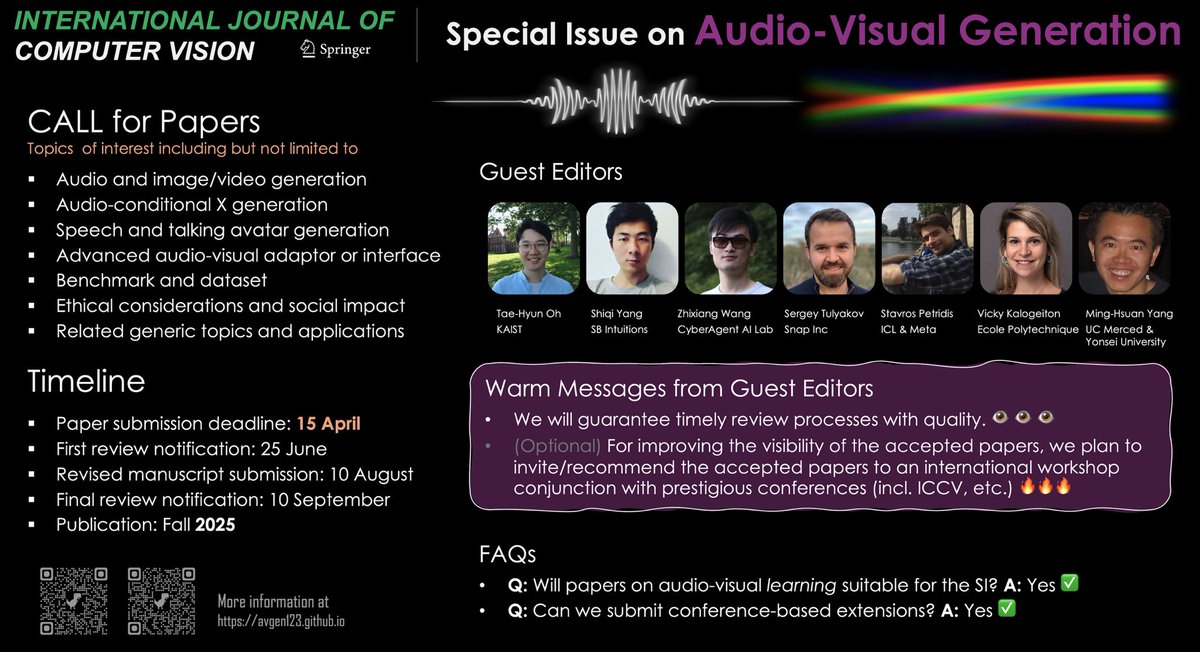
Please come and see this IJCV Special Issue on Audio-Visual Generation. (Deadline: 15th April, 2025)
Fast process, conference extension, and potential opportunities to be presented at an ICCV workshop!
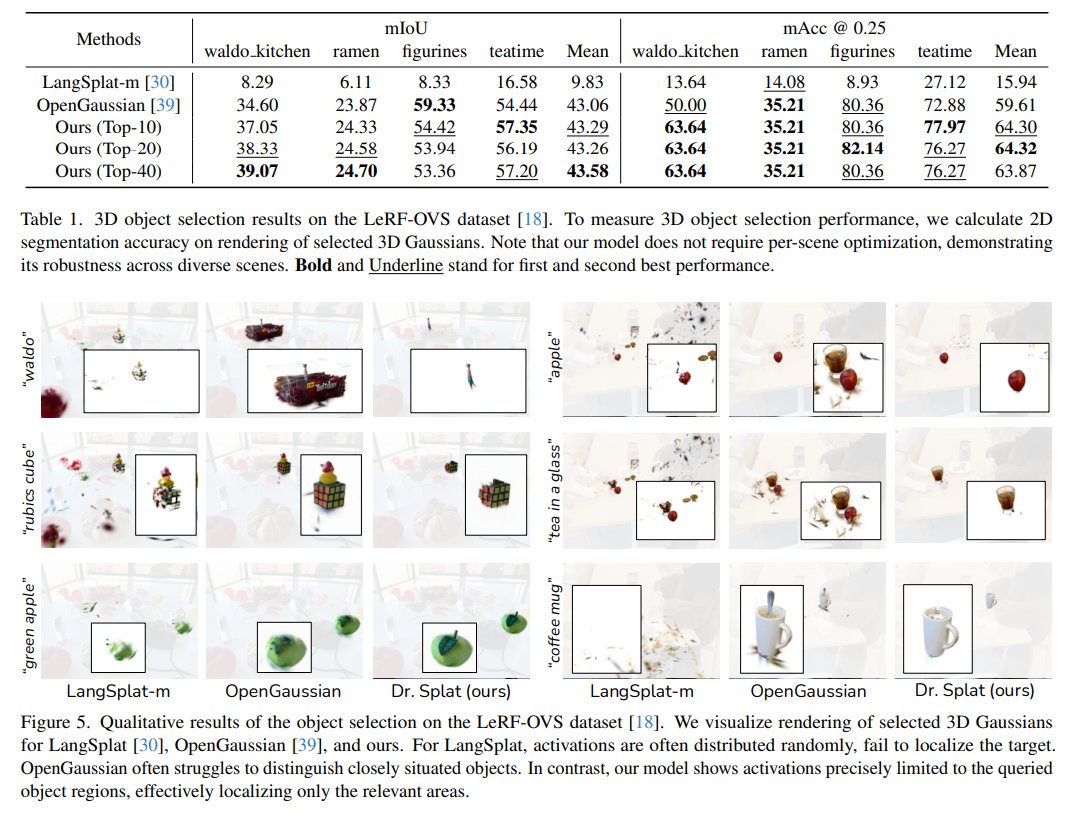
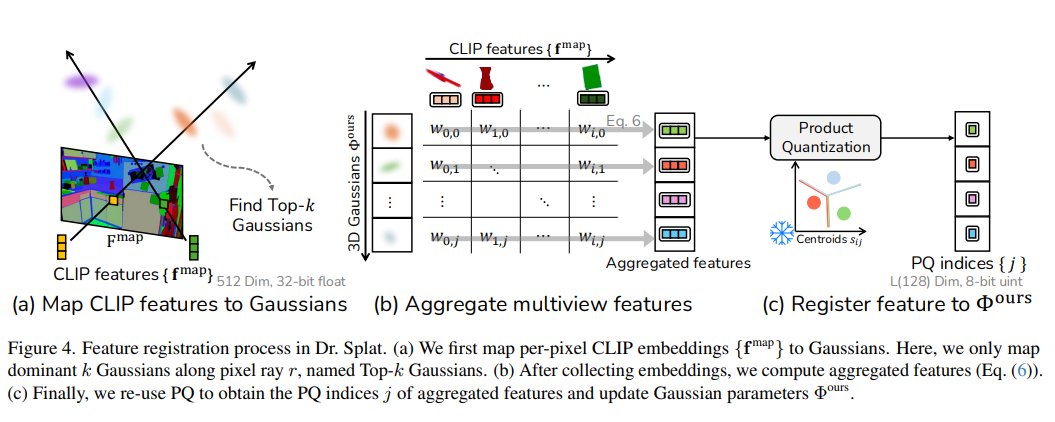
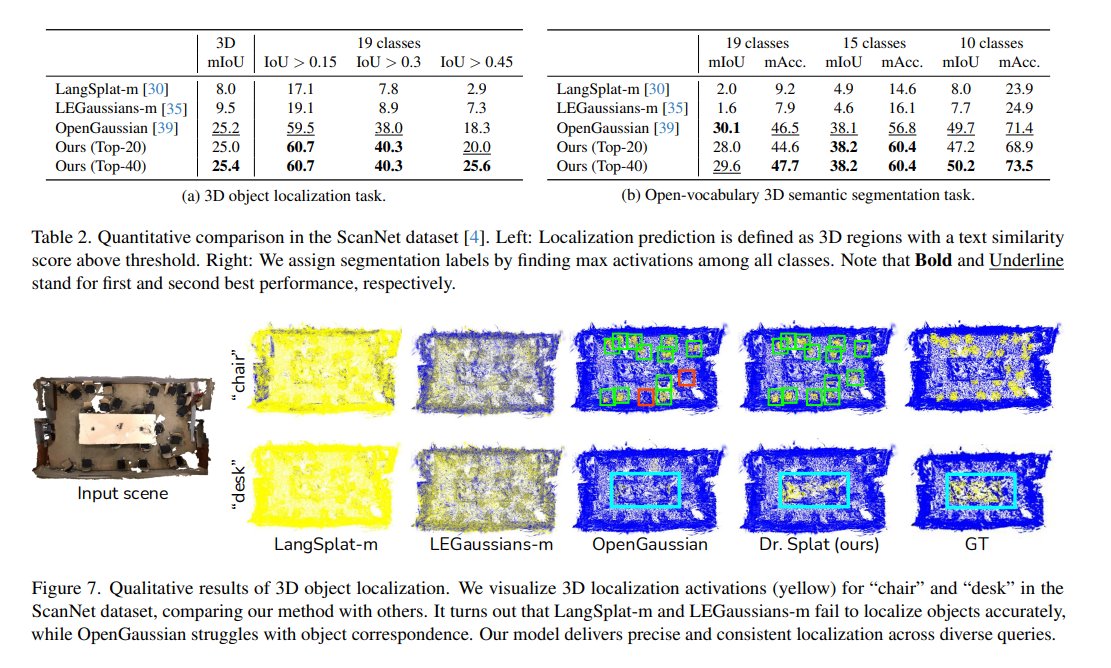
Dr. Splat: Directly Referring 3D Gaussian Splatting via Direct Language Embedding Registration
Kim Jun-Seong, GeonU Kim, @ug___k, Yu-Chiang Frank Wang, @choe_jaesung, @Tae_Hyun_Oh
tl;dr: distil language knowledges into 3DGS
https://t.co/U329pxVh8t
@taiyasaki That was the most frustrating part as an AC. Invite emergency reviewer(ER)->wait->decline->invite->wait->decline->...
Even those ERs seem to have availabilities in the slot.
Also, the CVPR openreview setting doesn't show emails. That's another hassle to find emails separately
🚨 Call for Papers: Special Issue on Audio-Visual Generation 🎥🎵
We, guest editors, prepared an exciting new Special Issue on Audio-Visual Generation! 🌟 The International Journal of Computer Vision (IJCV) is now accepting submissions.
Please find the call for papers below!
A new special issue on Audio-Visual Generation is open for submissions in the International Journal of Computer Vision. For more information on the special issue & how to submit, access the CfP here: https://t.co/s1zBhS1Hnu
A new special issue on Audio-Visual Generation is open for submissions in the International Journal of Computer Vision. For more information on the special issue & how to submit, access the CfP here: https://t.co/s1zBhS1Hnu
AI can restyle large 3D scenes based on reference images!
FPRF is able to stylize NeRF scenes with multiple reference images without additional optimization while preserving multi-view appearance consistency.
https://t.co/nZMSVhJ5Rd
🎉 Our paper, "Feed-Forward Photorealistic Style Transfer of Large-Scale 3D Neural Radiance Fields", has been accepted to AAAI 2024.
TLDR; "Photorealistically Stylizable" city-level NeRF in a "Feed-Forward" manner!
Paper: https://t.co/aVZwu97gTe
Page: https://t.co/bUDCjmq5as
This work is a nice collaboration with GeonU Kim and @Tae_Hyun_Oh.
GeonU, the 1st author, was just a 1st semester M.S. student when he started this project! His great efforts and productivity led to this amazing result 👏
Page: https://t.co/bUDCjmq5as
Our expressive 3D talking head generation work will be presented in this WACV 2024 (6th, Jan.).
Our lab is making progress in understanding social expressions. The first step is laughing. Among many expressions of humans, laughing is one of the most important social signals.
Check out LaughTalk, our new #WACV2024 paper!
Project page: https://t.co/8YAWyPkdfP
Arxiv: https://t.co/ezQxTXCdXp
In this work, we propose a 3D talking head model, LaughTalk, that can simultaneously express speech🗣️ and laughter😀
Check out LaughTalk, our new #WACV2024 paper!
Project page: https://t.co/8YAWyPkdfP
Arxiv: https://t.co/ezQxTXCdXp
In this work, we propose a 3D talking head model, LaughTalk, that can simultaneously express speech🗣️ and laughter😀
🚀 Exciting News! Our latest work, archived on December 18, 2023, introduces a groundbreaking Text-to-Texture synthesis method.
https://t.co/HNSB8OAzSh
https://t.co/DU8dujGB4A
Here are some key highlights: