Introducing EmbeddingGemma 2! 🚀
Our lightweight, multimodal embedding model maps text, code, images, video, and audio into a single, unified embedding space. Optimized for on-device use cases, it features:
- 740M parameter form factor with modular encoders
- Flexible dimension sizes (768dim-128dim) via Matryoshka Representation Learning (MRL)
- 8K context window (4x larger than text-only EmbeddingGemma)
- A commercially permissive Apache 2.0 license
One of you is taking home this $12K MSI MEG PC 👀🔥🖤
How to enter:
1️⃣ Like this post
2️⃣ Follow @brittnaynay3@msigaming
3️⃣ Comment + repost 🔁
That’s it! ✅
🌎 International where legally permitted. Full Terms & Conditions + extra entry opportunities are linked below in comment ⬇️
Good luck 🖤🔥
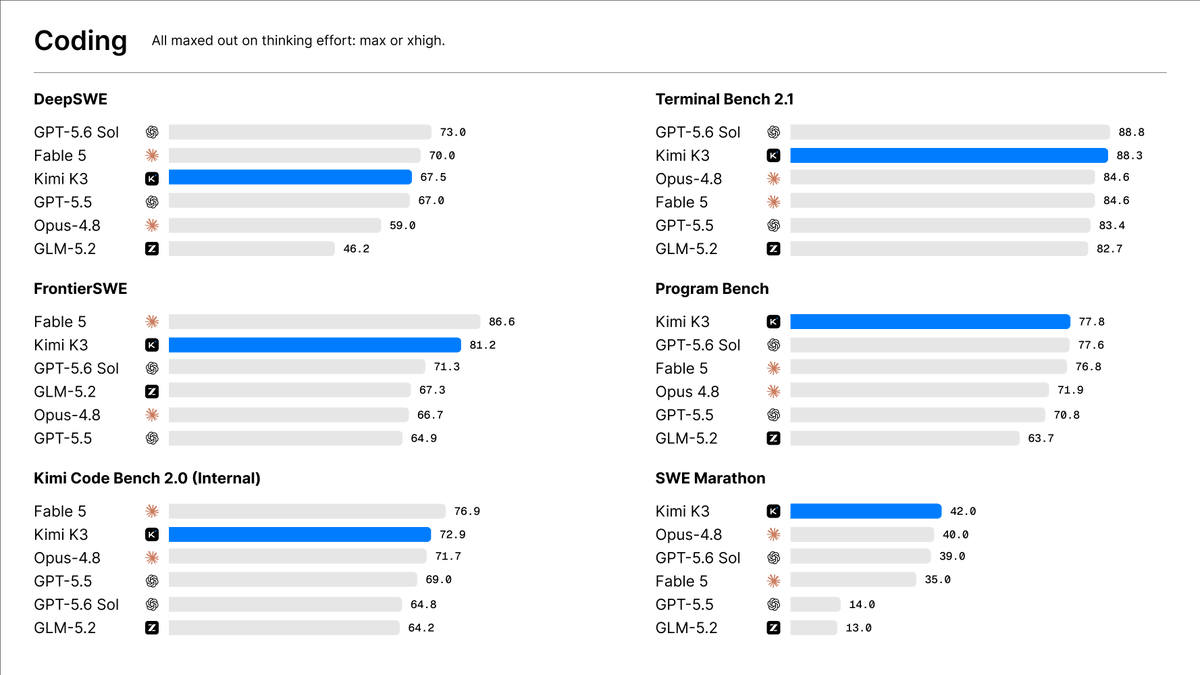
Introducing Kimi K3: Open Frontier Intelligence
🔹 2.8 Trillion Parameters, 1 Million Context, Native Multimodal
🔹 Kimi Delta Attention enables up to 6.3x faster decoding in million-token contexts
🔹 Attention Residuals deliver ~25% higher training efficiency at <2% additional cost
🔹 Built for long-horizon agentic coding and self-evolving workflows
Kimi K3 is now live on on https://t.co/zrk6zZxZUo, Kimi Work, Kimi Code, and the Kimi API.
Open Weights by July 27, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/YTfiMSNM1f
The next generation of HyperFrames skills is here
9 workflows your agent now actually understands
a launch video. a music video. captions and overlays on video
it knows which one you mean from context and routes there on its own
get started below ↓