Qwen3.8-Max is live on TensorX.
Alibaba just open-weighted their flagship for the first time. 2.4 trillion parameters, and on Artificial Analysis it lands as the world's second-strongest open model, a few points off the closed frontier.
We are serving it today on TensorX-owned GPUs in Europe. Your prompts, outputs and data never leave EU infrastructure. Zero data retention by design.
The gap between open and closed has almost gone. What is left is a different question: where does your inference run, and who can compel access to it.
Switch in one line: qwen/qwen3.8-2.4t-a95b
https://t.co/9sIkV0CRIi
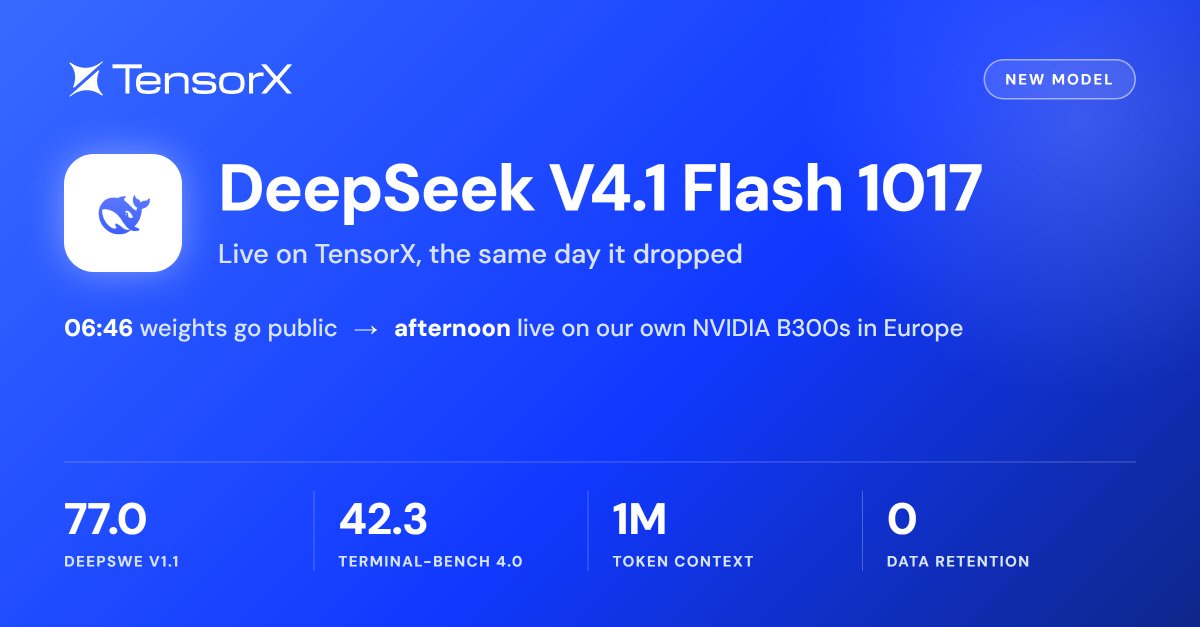
06:46 Saturday: DeepSeek drops V4.1 Flash 1017.
We woke the team, assembled the crew and got to work. Same day, it's live on TensorX on our own B300s in Europe.
DeepSWE v1.1: 77.0, ahead of Claude Opus 5 🔥
I love it when a plan comes together.
https://t.co/9sIkV0CRIi @deepseek_ai
@tensorx_ai is now available on @EdenAIco .
From today, Eden AI users can run DeepSeek, Kimi, MiniMax, Qwen and GLM models on TensorX, through the API they already use.
On our side, the models run on our own NVIDIA B300 GPUs in Dublin and Helsinki- Engineered for zero data retention.
Sovereignty is about control, not location. Knowing who runs your request, and where, is part of that control.
Thanks to the Eden AI team for building this with us.
Anthropic caught 151 million prompts harvested to train rival models.
How did they know?
Classifiers over API traffic. 3,500 accounts sharing one fixed prompt.
"We don't train on your data" is not "we don't read your data."
https://t.co/qD8PjYMnqx
GLM-5.3 is live on TensorX, serving within the hour of its Hugging Face drop.
https://t.co/5XvCDN8eTy's new flagship, and the strongest open-weight coding model in the world:
- AA coding index 74.8 (#1 open)
- 50% jump over 5.2 on coding
- SOTA on CyberGym
- 743B/40B, 1M context
First in Europe. Sovereign. Zero data retention.
https://t.co/9sIkV0CRIi
Two frontier Flash models just landed on TensorX, live in the EU from day one.
GLM-5.3 Flash (https://t.co/5XvCDN8eTy): 320B/18B MoE, 1M context, multimodal, MIT
Qwen3.8 Flash-Next (Alibaba): 125B/6B MoE, coding index 73.1, multimodal
Near-flagship reasoning and coding at flash prices. Open weights, TensorX-owned EU GPUs, zero data retention.
https://t.co/9sIkV0CRIi
Tim Grant, CEO of Deus X Capital, and Executive Chairman of TensorX asked a good question yesterday: what does sovereignty really mean in AI?
His answer: control over your data. Knowing where it's processed. Confidence that models aren't sending it elsewhere.
We built TensorX to answer that question directly.
EU-sovereign inference. Open weights. Zero data retention. Your data never leaves the jurisdiction you chose.
But Tim also made a broader point. Sovereignty shouldn't be a luxury reserved for the world's largest multinationals.
Smaller companies building with AI need the same guarantees. The same infrastructure. The same control.
Tim covered this on CoinDesk's Public Keys. Worth watching:
The next phase of @tensorx_ai infrastructure is on the data centre floor.
The first @Dell PowerEdge XE9780 systems, part of a ten-server, 80 GPU NVIDIA B300 deployment, arrived at our Irish data centre this week.
This is Irish-owned sovereign AI infrastructure. Every system runs private AI inference on dedicated hardware that TensorX owns and controls. Zero data retention. Full EU data residency. Built for teams in finance, healthcare, law and other regulated industries.
Sovereignty is not a promise not to look. It is a provider that structurally cannot. No US parent to compel, EU inference by design.
This adds substantial capacity to infrastructure already in production, and there is more behind it.
Deployment is delivered by our infrastructure partner ICT Services, with @Dell Technologies.
Build on dedicated sovereign AI infrastructure today: https://t.co/zsutJbhd41
#SovereignAI #AIInfrastructure #EnterpriseAI
𝗞𝗶𝗺𝗶 𝗞𝟯 𝗶𝘀 𝗹𝗶𝘃𝗲 𝗼𝗻 𝗧𝗲𝗻𝘀𝗼𝗿𝗫.
The world's first open 3T-class model:
• 2.8T parameters
• Native multimodal (text, image, video)
• 1M token context
• #1 open model on Artificial Analysis
We're running it on our own EU GPUs. Zero data retention. Frontier intelligence, sovereign by default.
Same endpoint, same key:
moonshotai/kimi-k3
https://t.co/a8uc1eA9sl
The bigger story is what @ClementDelangue keeps pointing out: open weights turn inference into a competition.
K2.7 is the same model everywhere, yet it runs at 205 tok/s on @tensorx_ai , 102 on @FireworksAI_HQ and 51 on @Kimi_Moonshot 's own API.
K3 today: one provider. The day the weights are released, this race starts for K3 too.
Appreciate the numbers, Thibault. Same open weights everywhere, so the speed was never the model. It is the metal and the scheduler underneath it.
Ours is a bit of in-house black magic we call adaptive KV choreography, tuned for goodput per GPU on our own EU hardware. The recipe stays in the kitchen 😉
And K3? The day the weights drop, it runs on our B300s. Same model, faster.
We ran the 4-bit (NVFP4) build of GLM-5.2 through the model makers' own official benchmark harnesses. Not ours. Theirs.
At half the bits it lands effectively even with FP8 almost everywhere. Here is the honest report, including the one place it loses.
Method: each maker's official harness at their published settings. Scored once, no best-of-N. Failures that ran are counted.
Results:
τ²-Bench telecom (strict official protocol): 99.1%
Terminal-Bench 2.1 (public leaderboard): 76.4
SWE-bench Pro: ~75%, partial and still running
BFCL v4: 71.5
Where FP8 still wins: long-context exact recall. Pulling one precise fact back from far up a long conversation. The 4-bit build is measurably behind on that specific skill. It is a safe failure though, it declines rather than inventing an answer.
Caveats we are keeping attached, because they are trust signals not fine print:
SWE-bench Pro is a partial read, not a final score.
Terminal-Bench is a conservative floor, measured under shared live serving against fixed per-task limits.
Our FP8 comparison ran on a third-party endpoint, so some of the gap could be serving conditions rather than the quant.
Why it matters: 4-bit at near-frontier quality is how a sovereign, EU-hosted platform serves frontier models fast and affordably, without your data ever leaving the EU.
Full write-up:
https://t.co/TdvQyMYeGe
Europe wants AI it can run on its own soil. That takes hardware, and the capital to finance it.
Solstice and @tensorx_ai are putting up to $1,000,000,000 behind it.
A billy.
𝗧𝗲𝗻𝘀𝗼𝗿𝗶𝘅 𝗶𝘀 𝗻𝗼𝘄 𝗧𝗲𝗻𝘀𝗼𝗿𝗫, and the new site is live: https://t.co/u7tmO2wBpp
We've rebranded and launched a brand new website !
In the last week we brought three of the strongest open source models in the world onto the platform:
𝗚𝗟𝗠-𝟱.𝟮, our exclusive @Zai_org release.
𝗠𝗶𝗻𝗶𝗠𝗮𝘅 𝗠𝟯, @MiniMax_AI 's latest flagship.
𝗞𝗶𝗺𝗶 𝗞𝟮.𝟳, moonshot 's newest, built for coding.
A year ago the best models were closed source, American, and rented. This week marks a huge change in the AI landscape where open source models have finally caught up to some of the frontier models.
All three run on TensorX-owned GPU's, based in the EU, with zero data retention. Open weights, hosted in Europe, 𝘆𝗼𝘂𝗿 𝗱𝗮𝘁𝗮 𝘀𝘁𝗮𝘆𝗶𝗻𝗴 𝘆𝗼𝘂𝗿𝘀.
The model you pick matters. Where it runs, and who can take it away, matters even more.
This is exactly what TensorX is for.
𝗚𝗟𝗠-𝟱.𝟮 𝗷𝘂𝘀𝘁 𝗹𝗮𝘂𝗻𝗰𝗵𝗲𝗱, 𝗮𝗻𝗱 𝗶𝘁 𝗶𝘀 𝗮𝗹𝗿𝗲𝗮𝗱𝘆 𝗹𝗶𝘃𝗲 𝗼𝗻 𝗧𝗲𝗻𝘀𝗼𝗿X.
It is the strongest open model yet. On independent benchmarks it scores 𝟲𝟮.𝟭 𝗼𝗻 𝗦𝗪𝗘-𝗯𝗲𝗻𝗰𝗵 𝗣𝗿𝗼 against GPT-5.5's 58.6, lands within a point of Claude Opus 4.8 on the hardest tasks, and does it at 𝗮𝗯����𝘂𝘁 𝗮 𝘀𝗶𝘅𝘁𝗵 𝗼𝗳 𝗚𝗣𝗧-𝟱.𝟱'𝘀 𝗽𝗿𝗶𝗰𝗲, with a 1M-token context and open weights.
We are the first to bring the latest GLM models to Europe through our exclusive partnership with @Zai_org @ZaiforStartups, with zero data retention.
Why does where it runs matter? Ask Anthropic. They shipped Fable 5 this month, and three days later a US government order pulled it offline, worldwide. Every customer lost it, through no fault of Anthropic's.
A model you only rent can be switched off by someone else. 𝗢𝗽𝗲𝗻 𝘄𝗲𝗶𝗴𝗵𝘁𝘀, 𝗵𝗼𝘀𝘁𝗲𝗱 𝗶𝗻 𝘆𝗼𝘂𝗿 𝗼𝘄𝗻 𝗷𝘂𝗿𝗶𝘀𝗱𝗶𝗰𝘁𝗶𝗼𝗻, 𝗰𝗮𝗻𝗻𝗼𝘁.
If provider risk is on your radar, come and run GLM-5.2 on Tensorix.
https://t.co/bVFUNzXDyg
#AIinfrastructure #Zai #glm #enterpriseai
https://t.co/5XvCDN8eTy's GLM-5-Turbo and GLM-5v-Turbo are now live on Tensorix! 🚀🚀
Not proxied. Not routed through a third party. Both models run on Tensorix-owned GPUs in Dublin, with full zero data retention as standard.
GLM-5-Turbo: agent-ready, built for coding and agentic use cases
GLM-5v-Turbo: multimodal reasoning across code, images, documents and diagrams
Capable models shouldn't come with a sovereignty trade-off.
Go build something cool on https://t.co/YneDKxsmMY
Announcement! deepseek/deepseek-v4-flash and deepseek/deepseek-v4-pro are officially available on Tensorix.
These models offer a powerful combination of speed and advanced reasoning. You can now integrate both models seamlessly into your applications using our private inference platform.
Discover these new models and start building today: https://t.co/Qg3V80RR0i
🚨 GLM-5.1 is officially live on @TensorixAI!
https://t.co/F4liLnhMlK’s new flagship model is a game-changer for agentic engineering and long-horizon tasks. State-of-the-art coding capabilities, now available on the most secure enterprise AI platform. 🧵👇
🤯 What can it do?
In testing, GLM-5.1 autonomously built a complete Linux-style desktop environment web app over an 8-hour session. It reviews its own output, identifies missing features, and keeps refining. The longer it runs, the better it gets.