MiniMax H3: Omni-Reference, Commercial-Grade Generation, Unbeatable Cost Efficiency, Open Weights
Your creative destiny, on your terms.
Now Live at https://t.co/3eD0u2z14S & MiniMax API.
MiniMax Code CLI is now open sourced 🎉 and SOTA on FrontierHarness Eval
After rapid iterations from day one, we’re thrilled to share this with the developer community. Grateful for every contributor and supporter
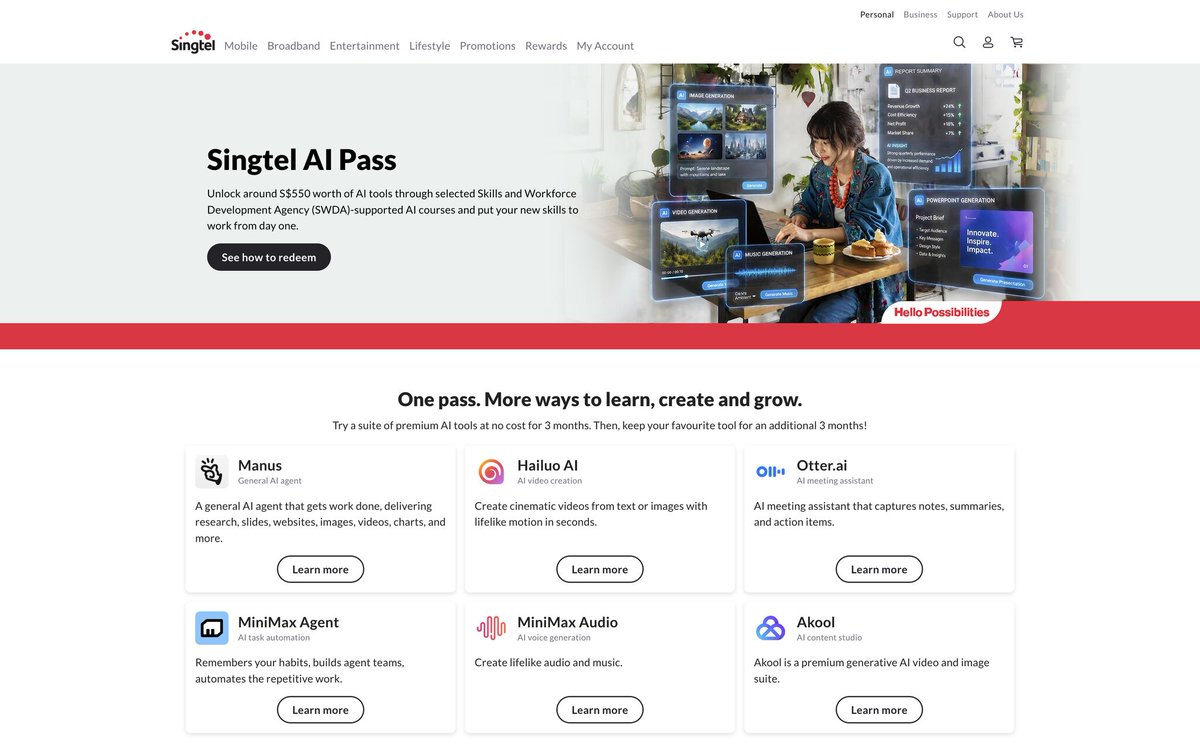
We're proud to contribute as an AI partner to the newly launched @Singtel AI Pass, supporting Singapore's SkillsFuture AI Subscription initiative. 🇸🇬
MiniMax H3 (@Hailuo_AI), MiniMax Agent (@MiniMaxAgent) and MiniMax Audio are all included, giving eligible learners across 200+ SWDA-supported AI courses hands-on access to premium AI tools and the opportunity to build practical, real-world AI skills.
This partnership brings our mission, "Intelligence with Everyone", to life, empowering learners across Singapore to explore, create, and build confidently with AI.
Learn more: https://t.co/b20nKblmjG
Three paths to faster video attention: compute the same interactions more efficiently, compute fewer in full, or change how information is mixed. Here’s a visual guide. 👇
Thanks to Nunchux AI and collaborators for VC-Attention, bringing training-free low-bit acceleration to MiniMax-H3, with better fidelity than SageAttention2 in the B200 evaluation.
The approach balances speed and fidelity: V-Smooth reduces value quantization error, while ExpCast-FP8 makes softmax faster through approximation.
Excited to see the community keep building on H3. Could combining low-bit computation with sparse methods like Sol-Attn push efficiency further? We’re looking forward to seeing that explored.
Introducing VC-Attention: fast and accurate low-bit attention without retraining.
On MiniMax-H3, VC-Attention speeds up attention by 1.6× on B200 and 1.5× on B300 over FlashAttention-4, with better fidelity than SageAttention2. It also works with existing sparse attention methods.
Two key innovations:
• V-Smooth reduces value quantization error.
• ExpCast-FP8 speeds up softmax.
Nunchux Attention, our proprietary extension, pushes the speedup to 1.9× on B200 and 1.8× on B300.
Blog: https://t.co/k0wDVujvBB
Technical Report: https://t.co/wMWfga6m73
Joint work by researchers at MIT, CMU, UC Berkeley, Stanford, and NVIDIA.
I’m thrilled to launch Faxie! Faxie is an app for generating videos inside Slack. Our vision is to help hybrid teams feel more connected.
Faxie is powered by @MiniMax_AI H3, which delivers incredible prompt adherence, realism, and generation speed!
https://t.co/5GTlTtCusf
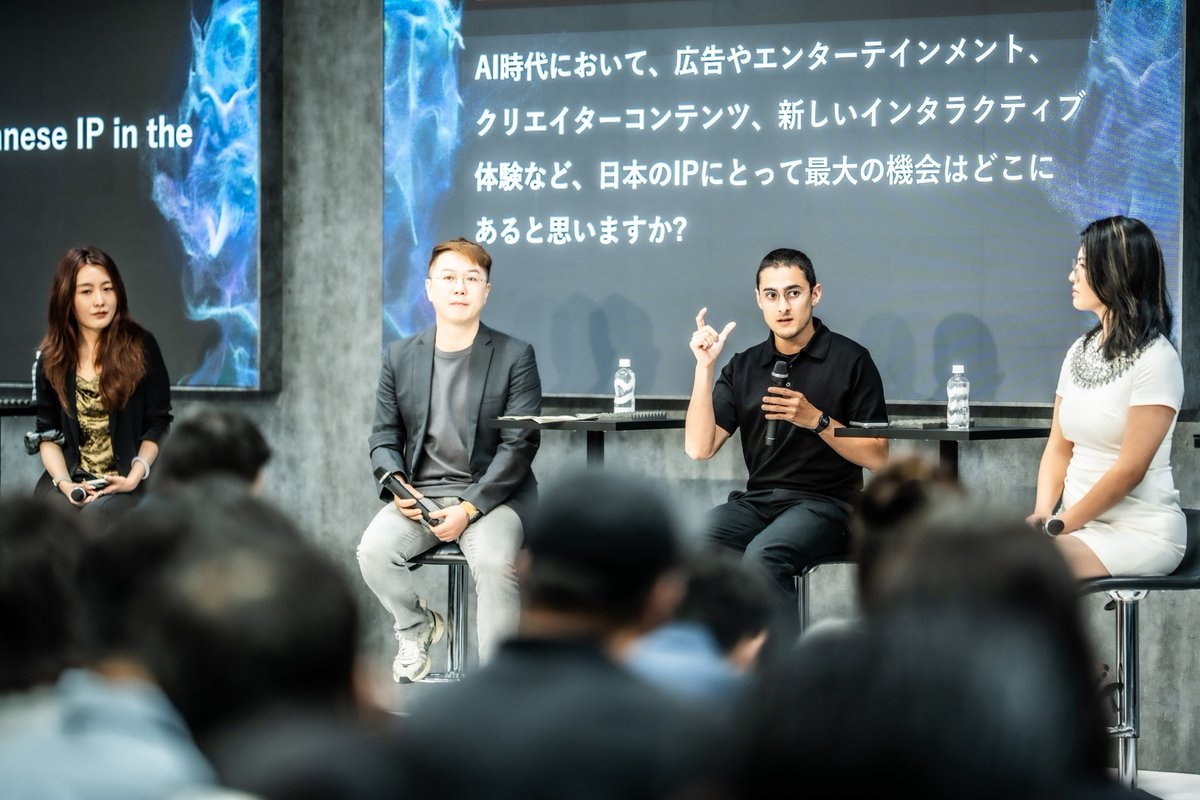
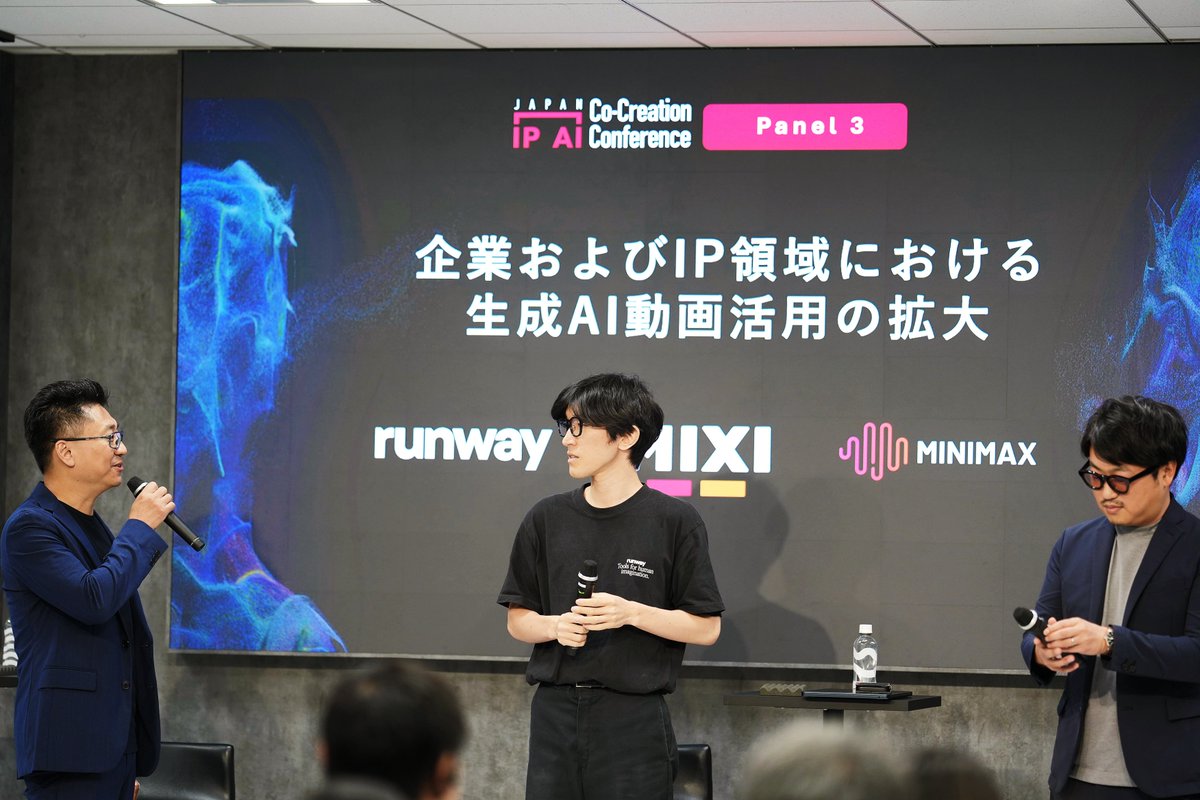
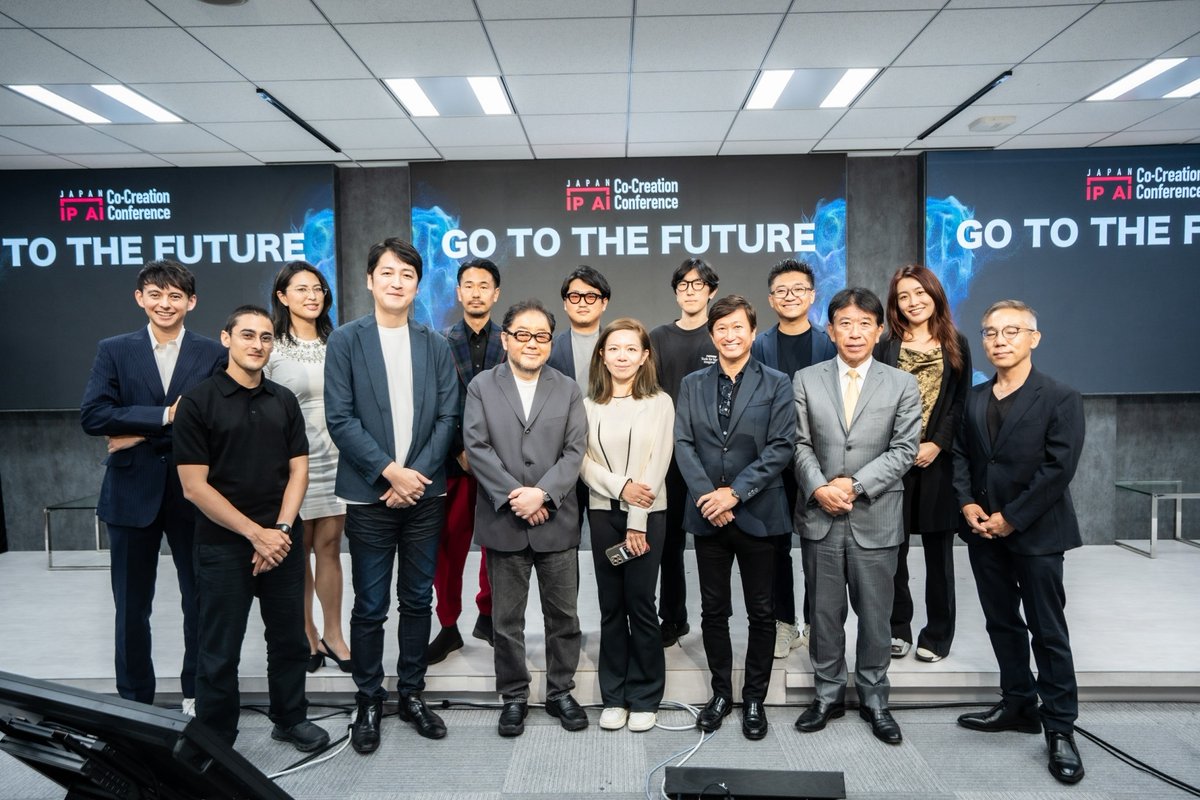
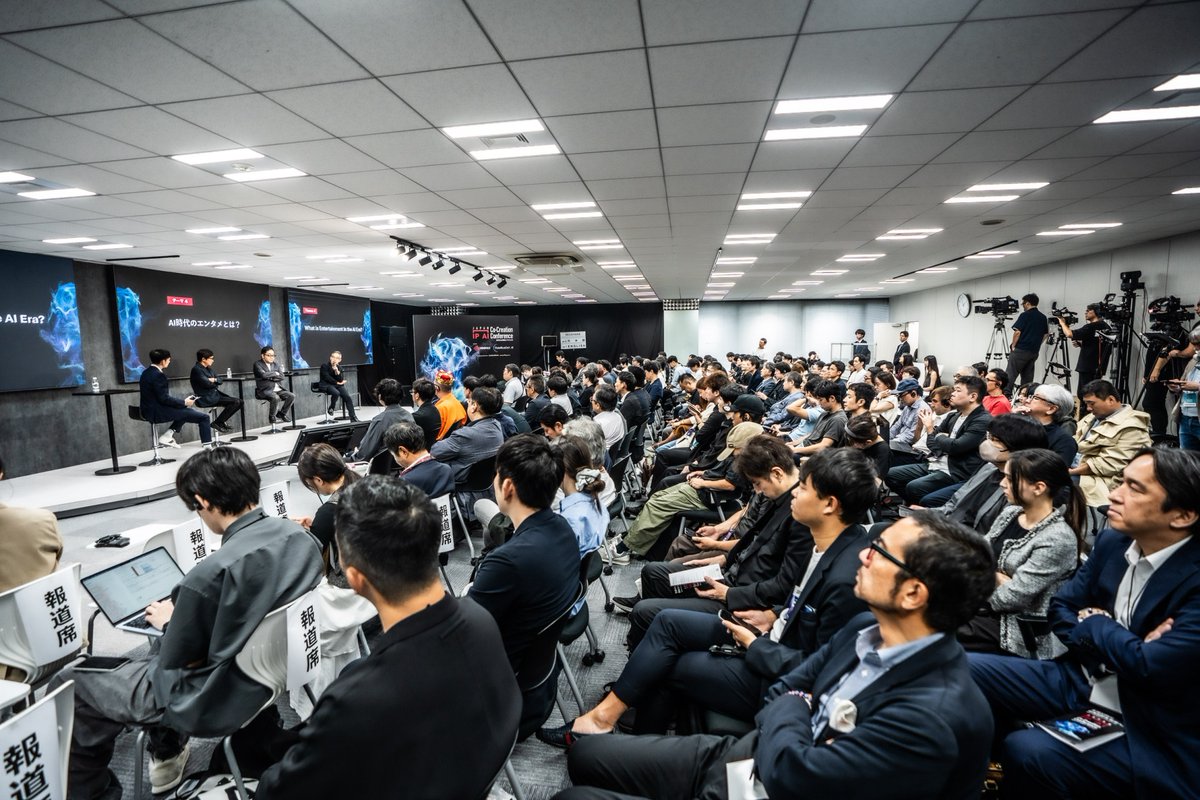
The Japan IP AI Co-Creation Conference, co-hosted by KAGAMI AI and MiniMax, has officially concluded. 🇯🇵 🎉
We brought together more than 150 companies from Japan and the U.S., alongside distinguished guests including AKB48 producer Yasushi Akimoto, KAGAMI AI Chairman Takami Kondo, and KADOKAWA editor and producer Motoi Chujo.
Global AI leaders @runwayml, @higgsfield, @krea_ai, and @HeyGen joined the conversation to explore the future of IP and generative AI.
We unveiled MiniMax H3 IP Edition, bringing the power of MiniMax H3 together with officially licensed Japanese IP for a new generation of AI-powered storytelling.
The conference received extensive coverage from major Japanese media, including a dedicated segment on TV Tokyo's WBS (@wbs_tvtokyo).
Japanese IP × Global AI.
A new era begins.
"Most users are going to have a relationship with the agent, so we're going to give them best in class and best in price."
@ysiu told @techinasia how we deliver on both ⬇️
Minds pools 50+ AI models, leaning on open-source large language models like @MiniMax_AI's M3 for 90 to 95% of frontier capability at a fraction of the cost. M3 now carries most of the workload, bringing @animocabrands’ compute cost down roughly 20x and cost per user to cents on the dollar.
The same economics power our Bazaar, where 5,000+ Skills are built without a highly technical setup.
The first builder covers the token cost, everyone after pays a fraction, and the creator earns a cut.
H3 keeps getting faster. ⚡️
@sgl_project + VDN-H3 now push MiniMax H3 beyond 2× real-time denoising on 8× B200 - generating 14.4s of 768p video in 9.0s end-to-end after warmup, with no measured quality regression.
Open models compound through open ecosystems. 🚀
SGLang-Diffusion with VDN-H3 now generates 14.4s of 768p video in just 9.0s 🚀
On 8× B200, 8 step denoising takes just 6.9s, reaching over 2× real time. The 9.0s figure covers the full generation request after warmup.
No measured quality regression versus dense 50-step H3 across 103 test prompts. 🧵
For our MiniMax Week challenge with @MiniMax_AI, we asked builders to create with MiniMax models, from LLMs to multimodal, across three tracks: Synthesis, Reasoning, and Multimodal.
We received nearly 50 submissions and reviewed them together with the MiniMax team.
Here are the winners 🥳
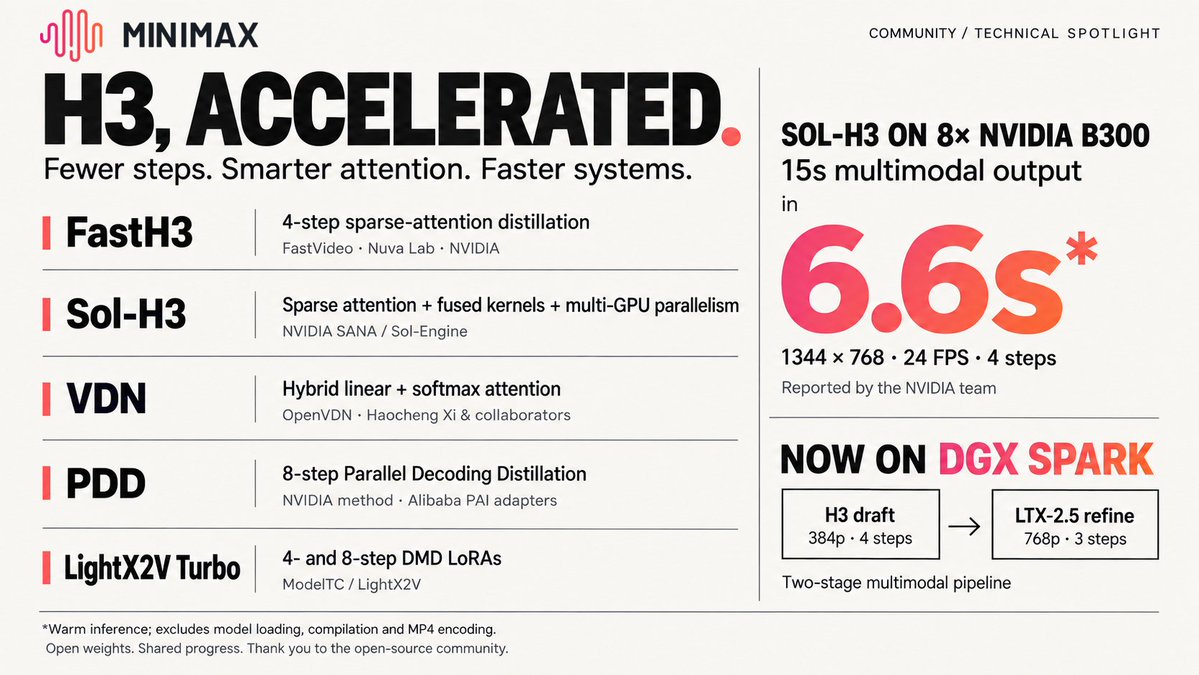
Open weights. Shared progress. MiniMax H3 is moving fast.
We built H3 for video generation with native stereo audio and multimodal reference control. The open-source community is making that capability faster, more accessible, and easier to build on.
Recent highlights:
• FastH3 — FastVideo, Nuva Lab and NVIDIA: 4-step distillation, now running on DGX Spark and Apple Silicon.
• Sol-H3 — NVIDIA’s SANA team: 15 seconds of 768p video + audio in 6.6 seconds on 8×B300, in the team’s warm-inference benchmark.*
• VDN — Haocheng Xi and the OpenVDN team: rethinking attention for faster H3 inference, with weights, training and inference code released.
• PDD — NVIDIA’s distillation method, brought to H3 by Alibaba PAI as 8-step Acc-LoRAs, now supported in ComfyUI.
• LightX2V — 4- and 8-step Turbo LoRAs, with workflows for text, image and reference-conditioned video + audio.
Behind every release are people training, optimizing, quantizing, testing and sharing. Special thanks to:
@haoailab@nuvalab@NVIDIAAI@xieenze_jr@HaochengXiUCB@ArashVahdat@julberner@LightX2V@ComfyUI
And to the individual contributors pushing the work forward:
@haozhangml@cxlcl1@lawrence_cjs@yitongli165665@haopengl33@songhan_mit@shanasaimoe
Thank you for building with H3 and helping make it faster, more accessible, and more useful for the community. Powerful models go further when we build together. Keep pushing H3. Excited to see what comes next. 🚀
Explore the ecosystem: https://t.co/F1S5IjUNi1
$50,000 in prizes for the best AI ads. 🏆
The OpenArt Ad Awards are here.
15 awards.
$15K for Ad of the Year.
Open worldwide.
Make a 30-sec+ ad with OpenArt and submit between Sep 10 - 30.
Presented by OpenArt, with Model Co-Sponsors @alibaba_cloud, @BytePlusGlobal and @MiniMax_AI, and Creative Partners @MachineCinemaAI and @WonderStudiosX