one more thing, I think it may also not be an H3 issue but maybe the fact we are training on the distilled model. we can only take shots in the dark and hope we get the right settings. I would hope that when H4 comes out we get h3 base model to train on from @MiniMax_AI
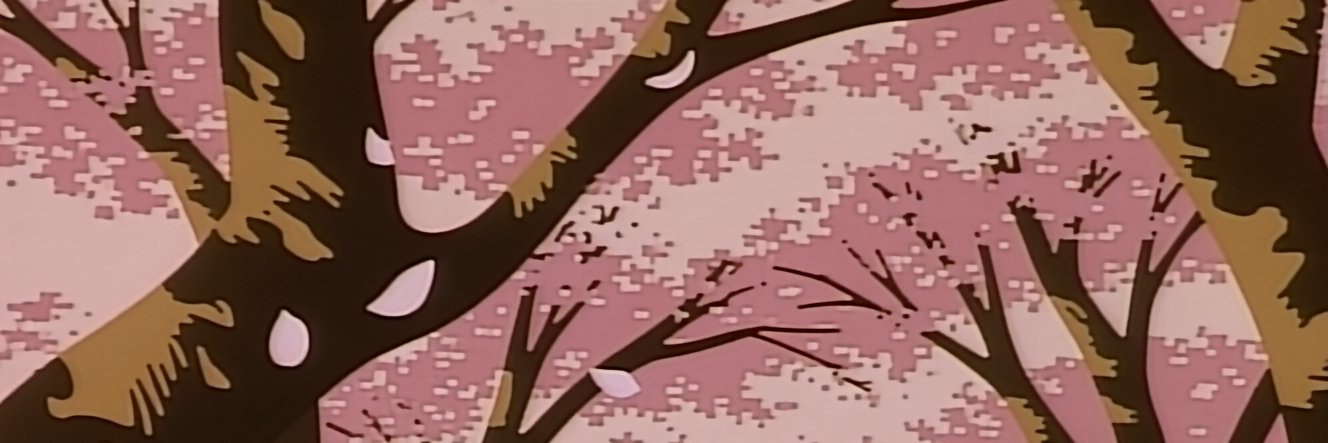
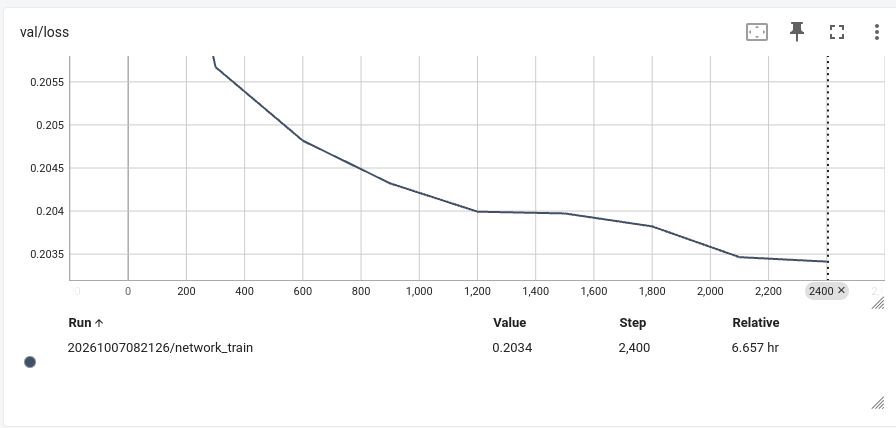
I recently released a cyberpunk edgerunners #h3#lora. Using the ostris v3 adapter method. And really happy with the results. I took my LTX dataset and converted it to images and then trained for around 7 hours. With validation dataset, it was less than 24 hours to release a fully tested h3 style lora. I bet at this point the process could be automated, but I think best to pick the dataset on your own.
https://t.co/2vJOfgPhco
Check out checkpoints. Further steps gets character details better but it bleeds into the base model too much, if you want the characters ref workflow with a single character sheet cannot be beaten. Unlike qwen or wan or ltx, H3 just can't get the details right when many characters are involved.
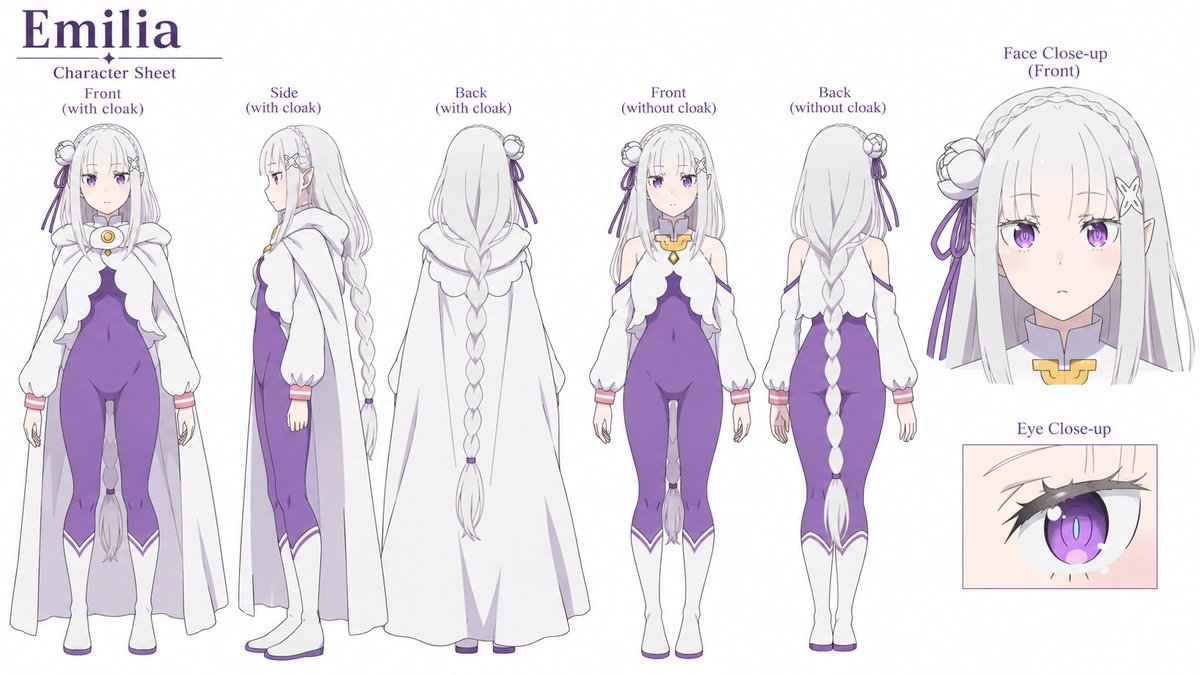
#Training on image only datasets in #h3, we can see that things do tend to feel less "alive" or dull with fewer motions. That said it doesn't mean things are in slow motion or anything. I need to run some tests with training on clips + images again. I think this happens when doing image adapter method for training. With distill guidance in musubi fork, I get no reduction in motion but the cost is distortion in the color and lines. The green woman example is image adapter training, and the rezero emilia example is with distill guidance training.
An update to my long form video learnings. I took the rough output from claude from my original video, and hand adjusted each prompt. And then removed the turbo lora and ran it on 20 steps euler beta57 with my gurren lagann style lora. Now there are a lot fewer errors/inconsistencies. It still is rough around the edges though. This is all in one shot with no retakes though, so it ran through 10 prompts connected via context loop node workflow. I think for a local #h3 video there is a lot of potential in the future.
The news about 5090 discontinuation has made me really nervous. If my 5090 ever breaks and warranty isn't covered I don't think I can continue this hobby. I just need my card to hold out another 2 years, hang in there though guy...
New version of my #rezero season 3 lora. I've now done like 4 loras using @ostrisai's v3 training adapter. And I can say this is currently the best way to train H3. I owe a lot to his work on this. Now I need to either do more work on sound training or back to video training. I think a lot of the work I did with distill guidance now has been made obsolete.
Anyway check out the lora below. Much better! More characters can be made this time around. Still ref images are king. Example below is v2 lora + ref image.
https://t.co/nnfuNENd9H
Overall it took around 6 hours per session, we did 2 sessions. Once for a full video but it started to lose cohesiveness as it went on. In the second session I had claude send each video over to gemini and had gemini give feedback on mistakes. It worked around 80% of the way. A final round of feedback by me done in a few mins fixed the rest. And then 1 last small adjustment. I think overall the result will be better doing it by hand, but I think you could get 80% of the word done and then hand tweak the prompts. The biggest issue is that claude cant hear and gemini tends to miss audio queues. I also used this node to make the long video itself:
https://t.co/whIixWNeMa
I had claude make this 2 minute long video, gave it access to a folder with some concept images for the characters, example workflows, and a paragraph describing the story. It then generated in comfyui using #h3 minimax and edited together in blender. More info on the cool things claude did below:
Here are the character references (some old wan video screenshots from over a year ago). Claude then proceeded to make character reference sheets using h3 itself. It generated 360 videos of each character and background then took photos and spliced them together for the reference workflow
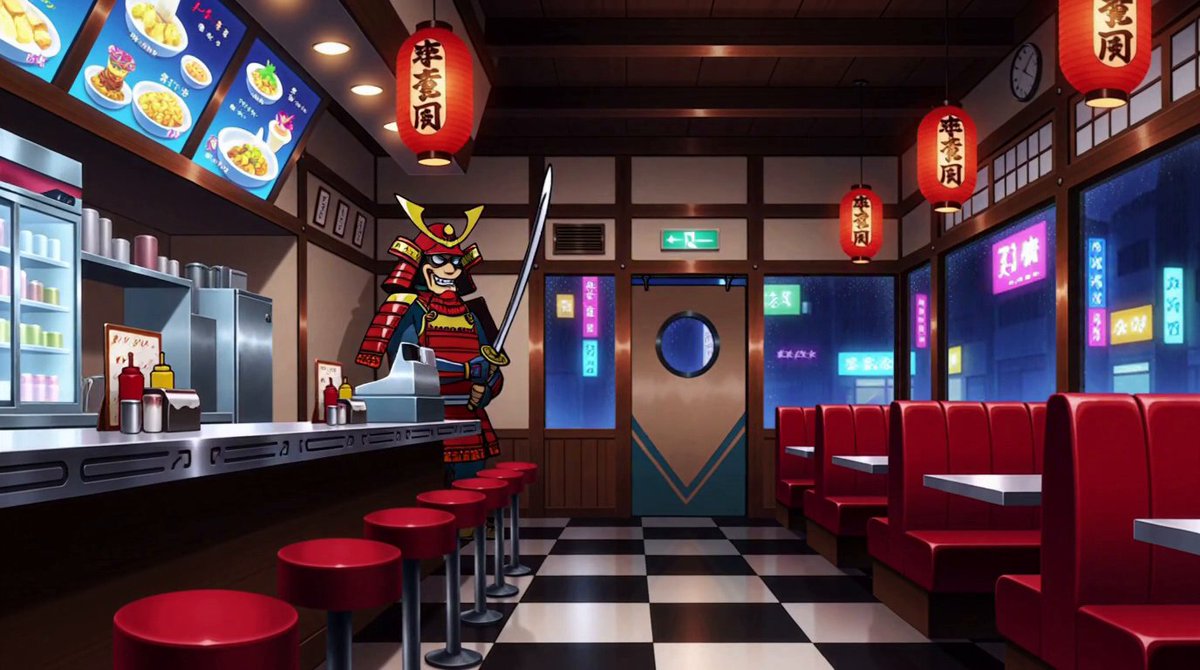
I revisited my gurren lagann style h3 minimax lora but used Ostris v3 adapter from @ostrisai . And I quite liked the results. It's very possible, the old version of this lora was just trained with bad settings or an overtrained checkpoint but overall the lines are less distorted and the style is closer in v2 now. Training with images seems pretty much 100% solved in my opinion, training with video and sound in h3 still has more to be discovered.
Lora here if you want to try it
https://t.co/rX3C0IcB6a
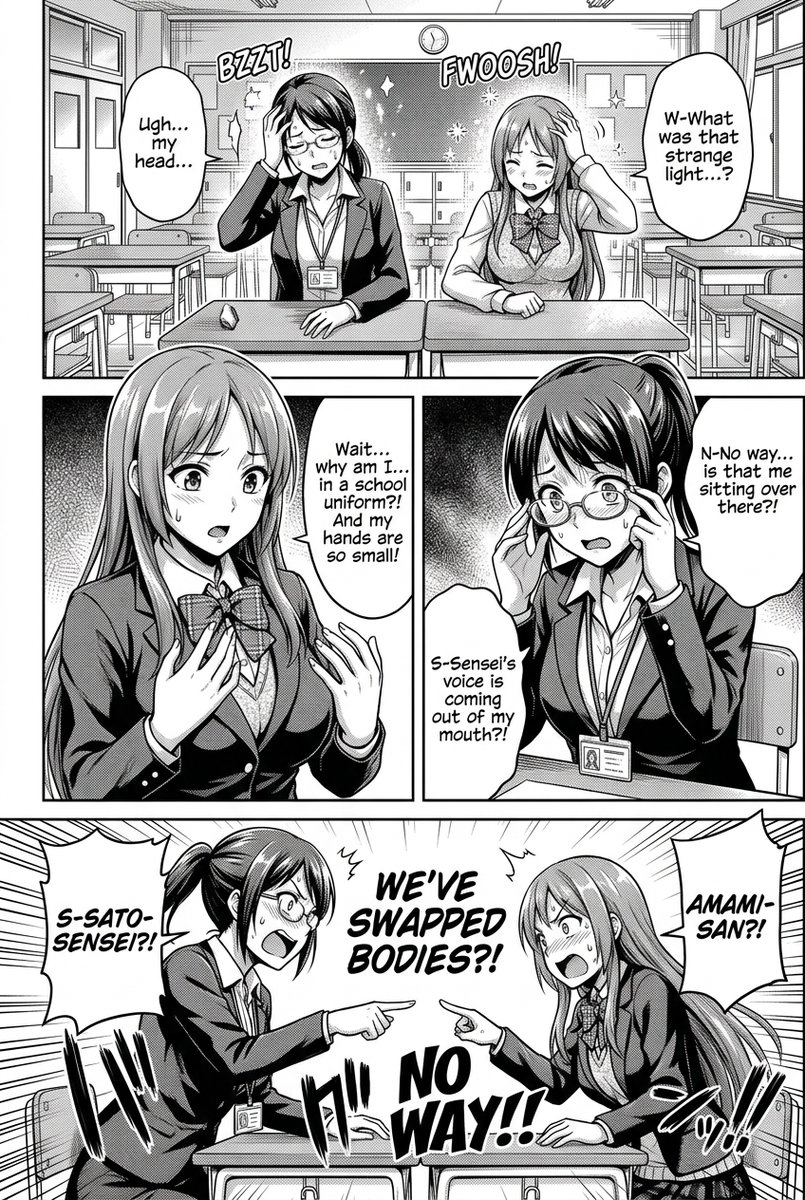
Now, that' said nano banana 2.1 is incredible at making manga pages. Some details wrong but the overall result is very much usable. Blown away by this quality. I just prompted with reference for style "Make a manga 1 page about a female teacher and student body swap".
I tested GPT 2.5 sunburst versus Nano Banana 2.1 for making character reference sheets from screen captures. And GPT is still king by a lot. That said the result of nano banana wasn't terrible, I think with some additional guidance it could be same level. But GPT for the most part can one shot this task. It's king.