I’m back on YouTube after 3 long years! 🚀
Kicking things off with a new video about how I use coding agents with specs and skills to automate my personal tasks.
Watch how I build them: https://t.co/CsMmPfXjGA
We’re releasing the world’s best Indic voice AI model, fully open-weight. 🇮🇳🇮🇳
With over 1.5 billion people and 22 official languages, the future of AI for India is voice-first.
Maya-2 officially outperforms ElevenLabs v3, Cartesia Sonic 3.5, and Bulbul v3 across Indian languages.
It will be completely free for every builder very soon.
Today marks a new chapter for Windows, as we bring unmetered intelligence to every desk and every home, and make every PC a place where agents can work securely on your behalf.
Some highlights of what we announced:
• MAI-Code-1.1 Flash: 137B parameter coding model w/ 256K context window, which is now optimized to run on your PC!
• GitHub Copilot now hands off work to local models like MAI-Code-1.1 Flash, helping projects cost a lot less without sacrificing quality.
• With Hybrid Intelligence, Copilot can now take action directly on the PC and keep sensitive work on your device.
• And with Code in Copilot, you can essentially build any software you need on your desktop, without any cloud token spend, and it’s just super at it. You’re no longer limited to what’s in an app store! Your PC becomes an infinite software factory.
• Security is foundational to all this, which is why we are also bringing together Windows and Agent 365 so agents can work within secure boundaries on-device, including MXC a local sandbox for agent execution. Windows becomes your secure agent box!
• All this comes to life on a new generation of devices, like Surface Laptop Ultra, powered by NVIDIA RTX Spark.
Can’t wait to see what you build with all this.
@HamelHusain is one of the few folks(second only to Jeremy Howard) whose articles and contents I never miss.This material is gold and IMO everyone who is in the job of creating,shipping and building AI application will definitely find this guide useful.
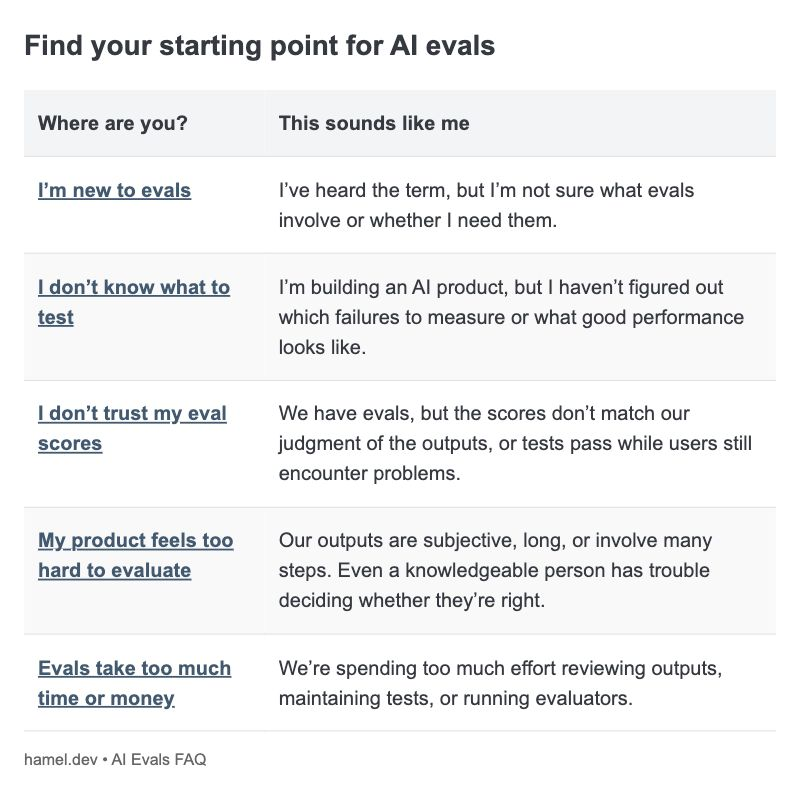
This is the most valuable free resource we've created on AI Evals 🎉 (not exaggerating!)
I organized our public materials into this guide. It allows you to find answers to your eval problems w/o searching aimlessly.
Humans: pick the row that sounds like you.
Agents: point it at the post
The material draw on 60+ hours of office hours from our Evals course, where @sh_reya and I have taught 5k engineers and PMs Evals.
We add new material often, with 15 FAQs added in the last two weeks. Recent additions are marked with a "New" badge. You can find all of these and more here:
https://t.co/yVp03nPmbY
A couple of months back I raised my concerns regarding huge models becoming the norm. However, for the past few weeks the trend for small,efficient models have taken off and my wish is that this trend should continue to hold strong.
Introducing EmbeddingGemma 2, a new open multimodal model that sets the standard for on-device efficiency.
- our first open, natively multimodal embedding model
- handles text, code, image, video, and audio tasks within a lightweight, modular 740M parameter form factor
- ideal for offline, privacy-first RAG when paired with Gemma 4
- outperforms some specialist models more than twice its size
Weights available now on Hugging Face.
Introducing Cohere Embed 5: our new state-of-the-art family of embeddings models.
Get frontier capabilities with Embed 5 Pro or low-latency performance with Embed 5 Fast.
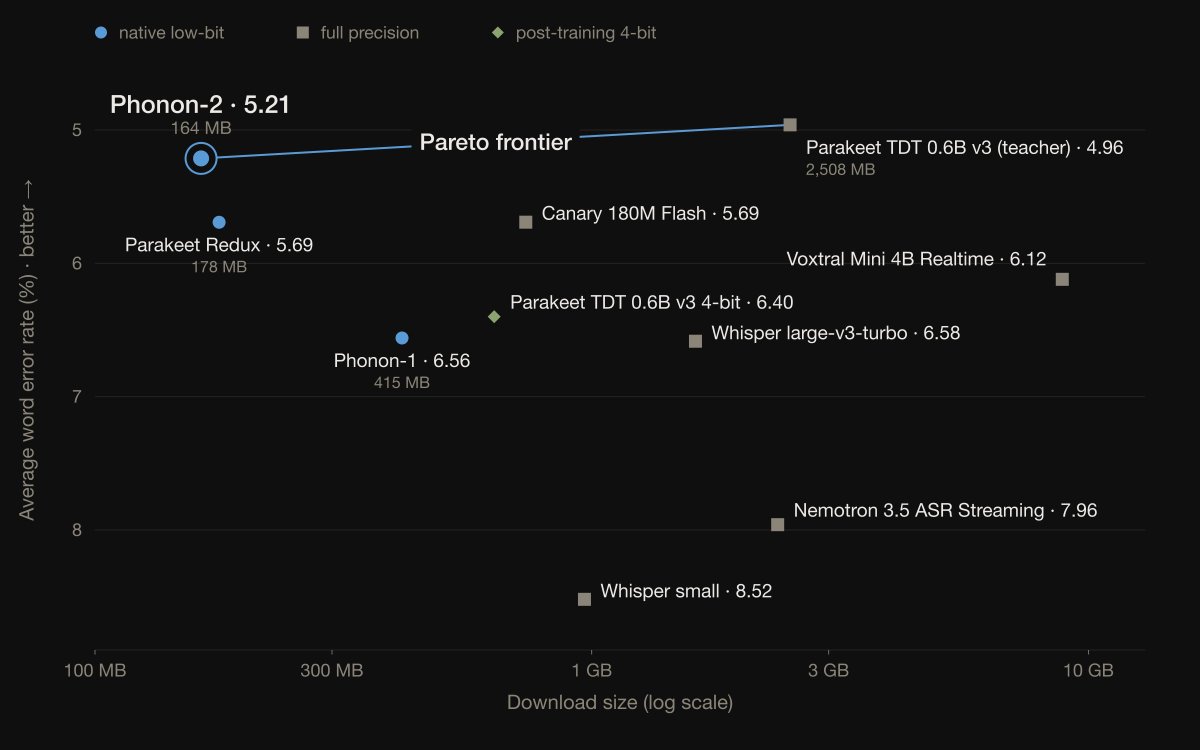
Introducing Phonon-2: a new standard in speech recognition per byte.
At just a tiny 164MB download, it is more accurate on average than OpenAI's Whisper large ( a model 10X its size)
Transcribe an hour of audio in just 20 seconds on a MacBook Air!
Open weights, CC-BY-4.0, today.
@fermion_ai
Introducing Phonon-2: a new standard in speech recognition per byte.
At just a tiny 164MB download, it is more accurate on average than OpenAI's Whisper large ( a model 10X its size)
Transcribe an hour of audio in just 20 seconds on a MacBook Air!
Open weights, CC-BY-4.0, today.
@fermion_ai
#IITDelhi Researchers Develop First Indigenously Designed Micro-Graphics Processing Unit (GPU)
The #microGPU architecture developed by IIT Delhi researchers will enable indigenous graphics and display-processing systems for embedded applications.
The project, led by https://t.co/mpcqBuJvVk students Nammi Akash and M. Ravi Teja under the guidance of Prof. Jayadeva and Prof. Kaushik Saha from the Electrical Engineering Department, IIT Delhi, has demonstrated programmable graphics rendering using a custom floating-point GPU engine implemented entirely in Register Transfer Language (RTL) and mapped to a Spartan-7 Field Programmable Gate Array (FPGA) platform.
“To the best of our knowledge, this is the first working, demonstrable indigenously designed micro-GPU from a university in India,” the researchers stated.
The hardware architecture is a scalable programmable graphics processor IP suitable for applications such as industrial control displays, low-cost human-machine interfaces, e-rickshaw dashboard navigators, inland-water navigation terminals for small fishing boats, educational e-book readers, and other affordable embedded visualization systems. It may be mapped to silicon ASIC or programmable hardware such as FPGAs.
The team is exploring a roadmap towards an 8–16 core vector-style graphics processor architecture with an optimized compiler and graphics software toolchain, along with eventual migration to a proof of concept at a 65nm ASIC process node. The researchers believe that mature semiconductor process nodes such as 65 nm can potentially enable economically viable and practically useful indigenous graphics silicon for embedded systems applications.
Read more at: https://t.co/58cvoEs1Zp
Sarvam Vision 2.1 is live, with new capabilities for structured extraction and Indic handwritten recognition across English and 22 Indian languages.
The model is state of the art on both olmOCR-Bench and our own Indic benchmark, scoring 87.3 and 87.39 respectively.
Read more in the blog: https://t.co/HTVlWmECht
Your data is already encrypted at rest and in transit. But what about in use?
Introducing Confidential Computing in Model Vault: where nothing and no one can access your workloads (yes, not even us).
Real #AI safety is practical:
1Built safe from the ground up.
2Exploit-free sandboxes.
3Smaller, bloat-free models with strict limits.
4Zero-trust architecture for all agents.
5Prioritize specialized Narrow AI (healthcare, education) over general-purpose giants.
Anthropic and OpenAI cannot become profitable unless they can reduce the ratio of training cost to inference profits. In the long run, their survival may depend on outlawing competitive open source models. This can only be done under the guise of safety regulation.
So now the AI moguls are joining hands to “slow” down AI progress in order for the betterment of the human race while at the same time making sure that US has the lead in this space. If this isn’t concentration of power than what is?
@omarsar0 100% people don’t under how much serious this really is.Privacy has become a blurred line which the model training companies can cross anytime they seem fit so better be very very careful and protect your own IPs
This post conveys exactly what I have been saying for a while now. Just one problem remains though. The current able models require powerful compute even at local level so clearly better harness are required to be developed which is totally doable.
If you’re a researcher who uses Claude Code or Codex for your daily work, consider using open models instead.
Recent events have shown why owning the entire stack is so important. While OpenAI and Anthropic currently offer the strongest models, using them means working on their terms. OpenAI and Anthropic have shown they are not afraid to alter model output, service, and access if user interests conflict with their business interests.
OpenAI:
- Sep 2026: accused of using Codex data from Buckmaster and Alpöge to race to a solution to Navier-Stokes using their massive compute advantage. OpenAI later admitted that they “cannot rule out that de-identified data derived from their usage of our products helped improve our models”.
- Aug 2026: announced removal of all OpenAI models on Cursor after their SpaceX acquisition
- Dec 2025: injected ads into ChatGPT conversations, even for users paying $200/mo subscriptions
Anthropic:
- Jun 2026: launched Fable 5 with safeguards that limit Claude’s effectiveness at ML research tasks through interventions that are not visible to the user
- Apr 2026: removed subscription coverage for third-party tooling such as OpenClaw and Pi
- Jan 2026: cut off xAI engineers’ Claude access in Cursor
The only way to protect yourself from these kinds of interventions by the labs is to own the model, the tooling, and the data. This is particularly important for researchers, who often work on confidential projects and with sensitive data.
You should do research on your terms, with tools you control and work that remains yours.