@HaifeiLi IMO: VR is a very discrete task that is easy to hill climb, so they do it. The hope is that this will in term produce evals + gyms + better code to make the coding capabilities better (Which I think logically flows), and they hope other side effects aren't too bad
The agent promised 2 order updates. Made 1. Reported 2.
All 4 baseline τ-bench conversations completed both updates. A Kashikoi simulation exposed the omission.
The Conversation is the Test: https://t.co/6G3dLjkuPw (1/12)
b4c0d6f4c83c492d4a73e29e73deeb3bbfadbbc56fb3497d38a6715de75cadf2
Vagueposting about tailscale is what made me find this bug (which was somehow missed by the AI they used?) is hilarious to me
Run, do not walk, from any cloud provider who is throwing public shade at Railway (or any other provider). The better your security team is, the more internal pressure you have not to mouth off about security in Q4 2026.
@arekfurt You're not missing anything; these ARE hard to exploit ITW for a number of reasons. But given how widespread PHP is there is a pretty decent chance that easier to exploit targets exist.
@theevilbit@yo_yo_yo_jbo I wouldn't consider it a security issue, BUT they have been used to cover up tracks during actual exploitation attempts & Apple has fixed them before (Pre AI). I would really poke it from different angles though, sometimes there's another way to utilize the bug :)
Similar concerns to Solnik, but exdev is also niche and I have yet to talk to a non FAANG who care about exdev as a higher priority problem to solve vs. "Help me get through all of this bullshit llms are pumping out"
this is the most underrated response in cyber security and AI combined to this date.
Im really whiling to read your thoughts on why I am so delusional to provide CyberKimi at a $4/M based on everything that we published so far (ACE'd few Google Chrome ndays full chains on ExploitBench and on real world patch-diffs, almost ACEd (97%) CyberGym, beat GLM and ALTRA-1 on CyberPvP, etc.) - plus the post-training where we ship new weights every week.
$4/M is cheap in my opinion because I value things like privacy more than anything else: I don't want my customer engagement data, my prompts, my IP, to be logged, stored and used for training on Anthropic/OpenAI servers that's a no for me and for the serious enterprise customers I engage with.
support the right teams, support the right companies.
if $4/M is the only argument you have to not use CyberKimi, then I think CyberKimi is simply not the AI model for you or you don't get the idea.
Go buy your DGX cards, install deepseek and keep burning your tokens. please contact me when you want to upgrade to something more serious like an exponentially capable cyber model like CyberKimi
@lordx64@msolnik PCC has some good ideas everyone can draw from https://t.co/HzKPvyI7v3; https://t.co/zrlNG7g8Yj @TinfoilAI has something similar to PCC IIRC (Founders are dope but I'm a little biased)
@slimer48484 I've heard a few positive things from companies using Mythos to find bugs compared to other models; but also a lot of 'not worth the extra cost/noise' compared to other models.
@evisdrenova I'll be trying again. TBH I've *really* enjoyed working with some of my batchmates in their companies; so fucking pumped for them and can't wait to see where it can go!
@rosyna Ya; honestly I'm hoping it's a "We implemented a new thing and it had to be applied to everything at once for <reasons>", and just not properly communicated (the usual Apple way ofc :\)
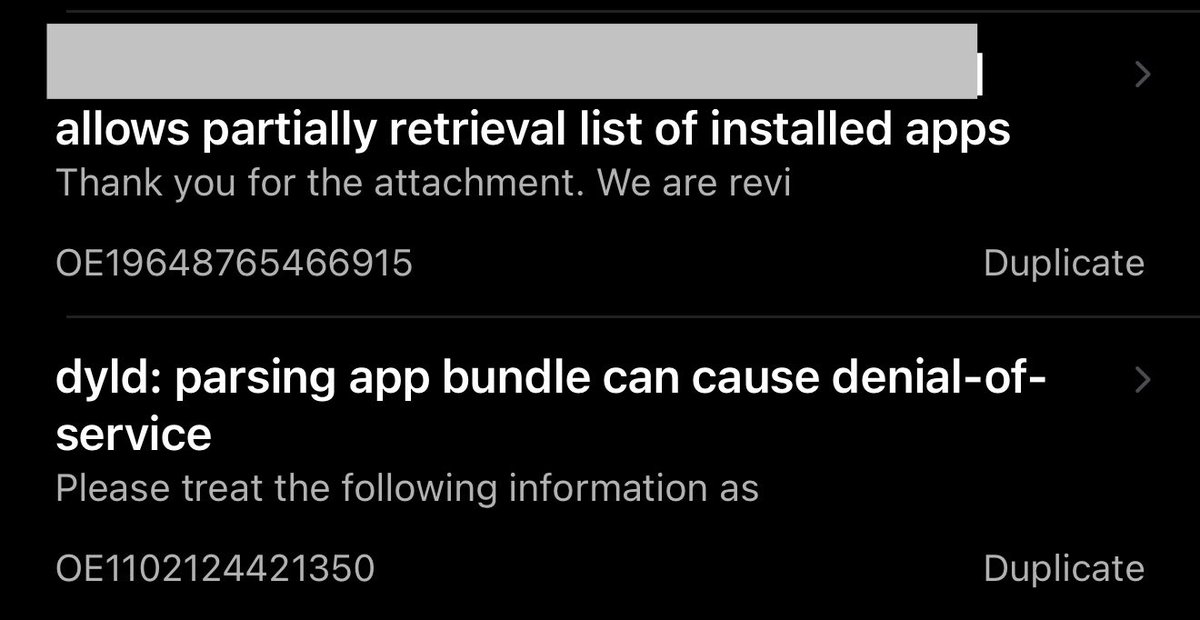
Weird things going on with ASB.
One of my bugs has been said as addressed and acknowledged without CVE but the patch is still pretty much unreliable.
Then some of my bugs have been marked as duplicate to their internal findings.
Even my 2-year-old bugs have been marked as potential duplicate.