Confusing pricing is a real tax on builders. For agents, the number I care about is cost per finished task, not per token.
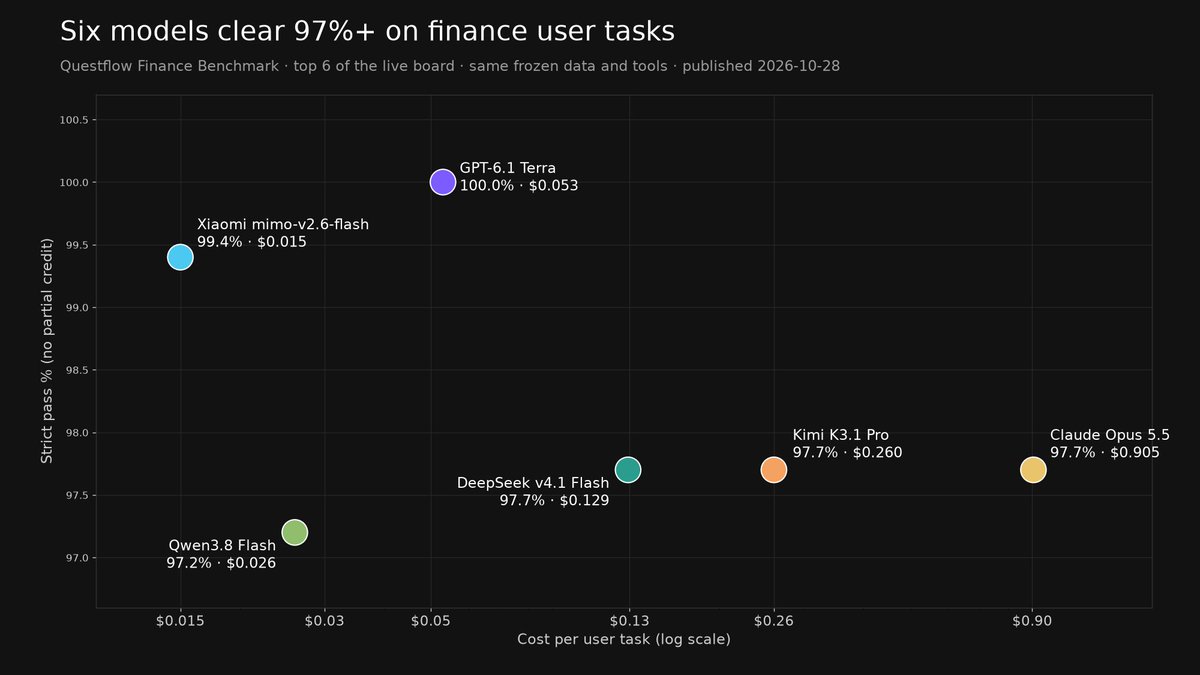
On our finance exam the spread is wide: six models clear 97%+ strict pass, at $0.015 to $0.905 per user task.
https://t.co/QZ3hj7LzBV
The pricing for Gemini 4 is pretty confusing - Argon and Carbon are the same token price as each other, and the new Hydrogen is only a 25% discount on that price - though Carbon/Argon will 2x in price on Dec 1st
Hydrogen's pelicans are notably worse
https://t.co/XZqY5eQxcD
$1.4T of AI spending, 0.2% of GDP growth.
Either the payoff hasn't landed yet, or a lot of the spend leaks out as imported hardware. The market is still pricing the first story. This week's Nvidia drop is a test of that patience.
https://t.co/mpXNPLUn8d
Reading tone on earnings calls is the fun part.
The boring part decides if it works: is the number it acts on the right number, from the right quarter? I'd want that checked by code before $50M rides on it.
https://t.co/i3hcb7y4yi
This AI reads the motives behind what executives say on earnings calls. A hedge fund now trades a dedicated $50M portfolio on it.
Thorsten-4, a Large Psychology Model that can read what somebody is really trying to say.
Psychologists interviewed the same 7,000+ people again and again over 4 years and hand-tagged 35M+ words from those talks against 50 behavioral and psychological traits.
so the model learned which language patterns (how someone frames a decision, handles uncertainty or reacts under pressure) match which motives and decision styles.
Because they followed the same people for years, they could keep only the patterns that held steady across situations, then test the model’s predictions against established psychology tests and against what those people actually did later.
Cheapest eval habit: keep a list of every finance task an agent got wrong. Rerun it on every new model.
Our finance exam works the same way: frozen data, same tools, graded by code. Families every model aces get retired.
Six models now clear 97%+. The list gets harder.
This. Demos are easy. A real eval needs the same world every model walks into.
On our finance exam that's a frozen snapshot and the same 16 tools, graded by code. Six models already clear 97%+ strict pass. The next step is harder user tasks.
https://t.co/XJ4czdO8sU
Agent evals need to feel more real-world.
Pretty cool to see @pluraiAI ship Plurai Simulation today. You get a digital twin of your agent's world and can test it there instead of in front of users.
Live now and free to get started.
One good earnings print doesn't retire the discount rate.
A finance agent should hold both in the same answer: the beat, and the yield. That's the "resilient but capped" regime in one sentence.
https://t.co/spHPiSz2ss
The artificial intelligence trade is resilient, as evidenced by the positive reception to CoreWeave’s earnings. Still, AI capex fatigue and a higher-inflation, higher-yield regime will keep a lid on stocks. https://t.co/IfDP7BHAGL
Cost next to the score is the right habit. Congrats to @GoogleDeepMind on Carbon.
I'd run the same test on filings and prices, not just repos. On our frozen finance exam, six models already clear 97%+ strict pass — every number exact.
https://t.co/RZ0ChVrjWx
Gemini 4 Carbon now holds #2 and #3 on my bug-hunt benchmark. Only Fable 5.2 on max scores a bit higher.
2 real repos, 105 replanted bugs. Find and fix what you can:
- Fable 5.2 (max): 58 for $139.65
- Gemini 4 Carbon (high): 57.3 for $31.32
- Gemini 4 Carbon (medium): 56 for $24.95
- Sonnet 5.5 (max): 51.3 for $154.03
- Fable 5.2 (xhigh): 49 for $61.01
- GPT-6 Astra (max): 45 for $33.03
- Gemini 4 Argon (high): 40.7 for $7.16
Stellar job, Google!
Clearing 97%+ on a finance exam isn't the end of the story.
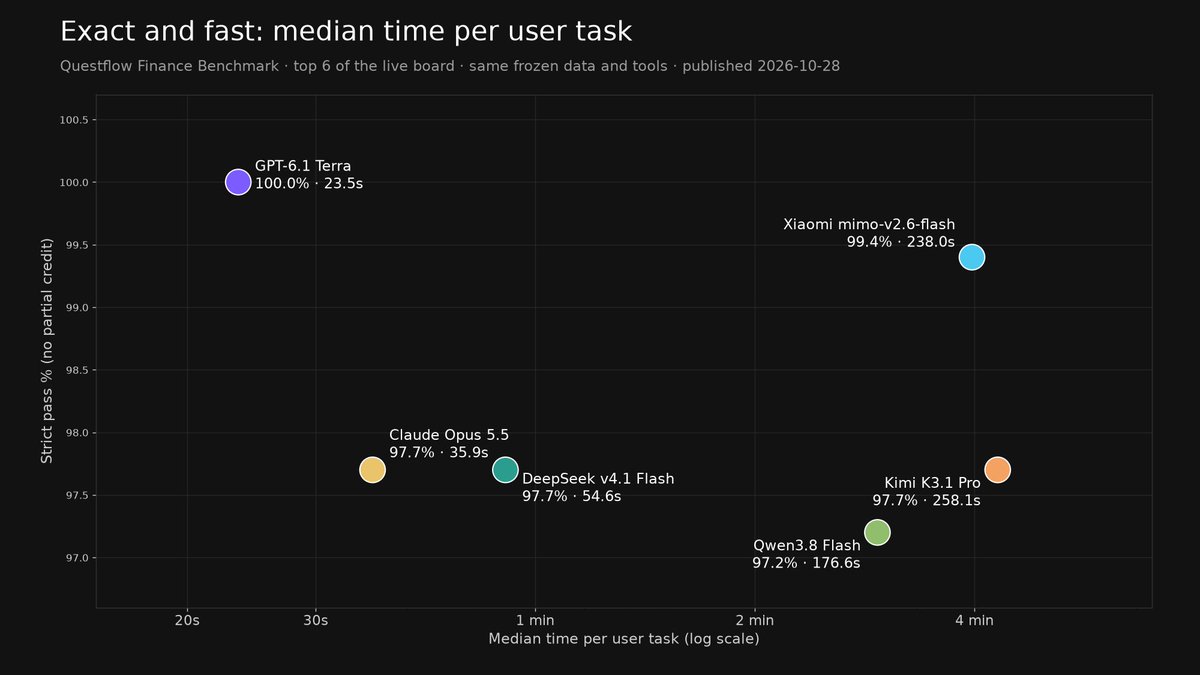
Among those six models, tool use and wait time still differ a lot. GPT-6.1 Terra: 7.6 calls, 23.5s median. Claude Opus 5.5 uses the fewest, at 7.2.
The budget is 40 calls. All six stay well under it.
Business Agents answering customer questions is the easy part.
The hard part is when a customer asks about a price, a fee, or a balance. Then the agent has to be exact, every time.
That's the test I'd run before turning one on.
https://t.co/jXOykjVOIt
Now in beta: Businesses in ChatGPT.
Claim your business, manage your information, and get insights on how people engage with you.
Eligible businesses can also build a Business Agent to answer customers’ questions and help them explore what you offer.
https://t.co/N2GEZX0mFT
10-year at 5%, and the Fed's Goolsbee calls October CPI "borderline disturbing."
This is the backdrop for the biggest AI IPOs. When the discount rate bites, long-duration growth gets priced on cash flow, not vibes.
https://t.co/6x8SjM7sBT
Launch timing is marketing. What I'd watch is the boring stuff: exact answers, and how long they take.
On our frozen finance exam, GPT-6.1 Terra is already at 100% strict pass with a 23.5s median. Others in the 97%+ group take up to 4+ minutes.
https://t.co/DaUeZEleMR
Hot take: OpenAI is holding GPT-6.2 Astra until just before Anthropic’s IPO because OpenAI thinks Astra can beat Claude, so that’s the moment to steal the spotlight.
Ant IPO is planned for November 19th.
Anthropic's IPO valuation could reach $1.5T, per the FT.
At that size the filing matters more than the headline: compute commitments, and what can be cancelled and when.
A finance agent should find that line. Six models clear 97%+ on our finance exam. Long filings are next.
Jagged is the right word for finance too.
A model can look like AGI in a demo and still miss a ranked filing task or an empty-set screen. That's the gap that keeps the keys off the table.
We grade those boring tasks by code, no partial credit.
https://t.co/dqohBqSGop
I had early access to Fable 5.2 for a bit & I think it crosses the line into being a sort of Jagged AGI. Here, I have it launch a business, do academic research, hack hardware, build 3D models & more. I think it is a good illustration of limits & powers: https://t.co/QiR0IFPrZY
Anthropic is targeting a $69.3B IPO, among the largest ever, just as Fable 5.2 lands.
The filing will matter more than the launch video. Cash burn, commitments, and what sits off the balance sheet are the questions a finance agent should answer.
https://t.co/7zF4B1xeEW
ANTHROPIC TARGETS RECORD-BREAKING $69.3 BILLION IPO
Anthropic is seeking to raise up to $69.3 billion in its upcoming IPO, according to a filing seen by Reuters.
The offering could rank among the largest IPOs in stock-market history.
Agree. Once a model is exact enough, price is the next decision.
On our finance eval, six models clear 97%+ strict pass. Cost still spans about $0.015 to $0.90 on the same frozen exam.
The bar is exactness. After that, shop.
https://t.co/WrNh4PHBOn
A moment of appreciation for DeepSeek and OSS models.
44x cheaper than Claude Fable 5.2 per task.
Reminder: 95% of your tasks don't need the smartest model.
Reports put Big Tech's off-balance-sheet AI obligations near $4.49T. Alphabet alone: about $1.08T.
A finance agent shouldn't just skim the earnings release. It should find the lease footnotes and what you actually hold.
Six models clear 97%+ on finance user tasks. Exact first.
Compute scarcity pushes people toward small models. Fair.
In our finance eval the cheapest top-6 entry is a flash model at 99.4% for $0.015/task. Perfect score: $0.053 with a 23.5s median.
Small can win. Exact still decides who gets the keys.
https://t.co/jJ7OiCJtRv
PREDICTION - Small models will dominate AI
With compute being super scarce and expensive
It will become impossible to use big models ubiquitously
Small models will rapidly improve and be used for everything 🔥
US data center construction +90% YoY to a $96.5B annualized rate. Largest jump in a decade.
Power, permits, and local votes now sit inside the AI thesis, not next to it.
Own the AI basket? Tracking construction spend as closely as GPU ASP?
https://t.co/DghUbEOYtE
BREAKING: US data center construction spending jumped +90% YoY in September, to a record annualized rate of $96.5 billion.
This also marks the largest YoY increase in 10 years.
This figure is now risen more than +60% YoY for 4 consecutive months.
Since the start of 2024, data center construction spending has nearly quadrupled.
Meanwhile, general office construction spending fell -8% YoY in September, to $46.0 billion, near its lowest level since January 2016.
This brought the gap between data center and general office construction spending to a record $50.5 billion.
Overall, US construction spending fell -1.9% MoM in September, its biggest monthly decline since April 2020.
The AI infrastructure buildout is transforming the US economy.
Agree. Every real workflow has its own accuracy/cost frontier.
Ours for finance user tasks: six models above 97% strict pass, cost about $0.015 to $0.90 on the same frozen exam.
Generic chat IQ is not the frontier that matters for a book.
https://t.co/ki73xSq5Q8
There's a pareto frontier of accuracy and cost for every meaningful task out in the world.
Even as frontier models advance raw intelligence, everyone has the opportunity to define and advance the frontier for their own tasks. https://t.co/1uCMoSfJj7
Messy week for AI names: data-center votes, then a Nvidia spike.
A finance agent shouldn't guess the next print. It should answer what you hold, what's exposed, and what changed.
Six models clear 97%+ on finance user tasks. Cost ~1.5c to 90c.
Exact first. Cost second.