FSD drove us from Austin to Michigan without intervention. 19~ hours across states only stopping for charging & food.
I take cybercabs daily to the office and back to the house, 0 issues and have done it almost daily since the cybercab became public.
It’s fair to say it’s come later than originally promised, not equal across hardware generations, and still not available unsupervised for purchased vehicles.
Calling it a lie is a lie.
Harness adapters training is now live!
We are training LoRA adapters on LFM2.5 / LFM3 from @liquidai and the recent Twil-9B model from @thewebAI using RL to make them more efficient and accurate on agentic tasks!
You can follow the training going live here: https://t.co/Li65iOX9Kr
https://t.co/tJ2hJuWtws
A necessary reminder that bigger is not always better... relevancy and accuracy improve in any situation when one has the right context and alignment on what success looks like. Promising broad sweeping outcomes of anything and everything under the sun would sound suspicious if a person claimed it -- so why not when a tech company claims it? Shouldn't intelligence be tailored to the problem at hand? Wouldn't you want the world's expert in cancer research solving your toughest cancer problems? Or just a really really smart person will do?
@Davidstout and the team at @thewebAI have pioneered the mission of delivering personal, customizable, relevant models that everyone and every company should have access to, on their own devices. Private, secure, cost effective, and most importantly, accurate.
The future of intelligence -- is yours.
@thewebAI app is officially live for everyone.
Expert AI running on your laptop. The more powerful your device, the more it can do.
Download the app: https://t.co/B6H97CT9gJ
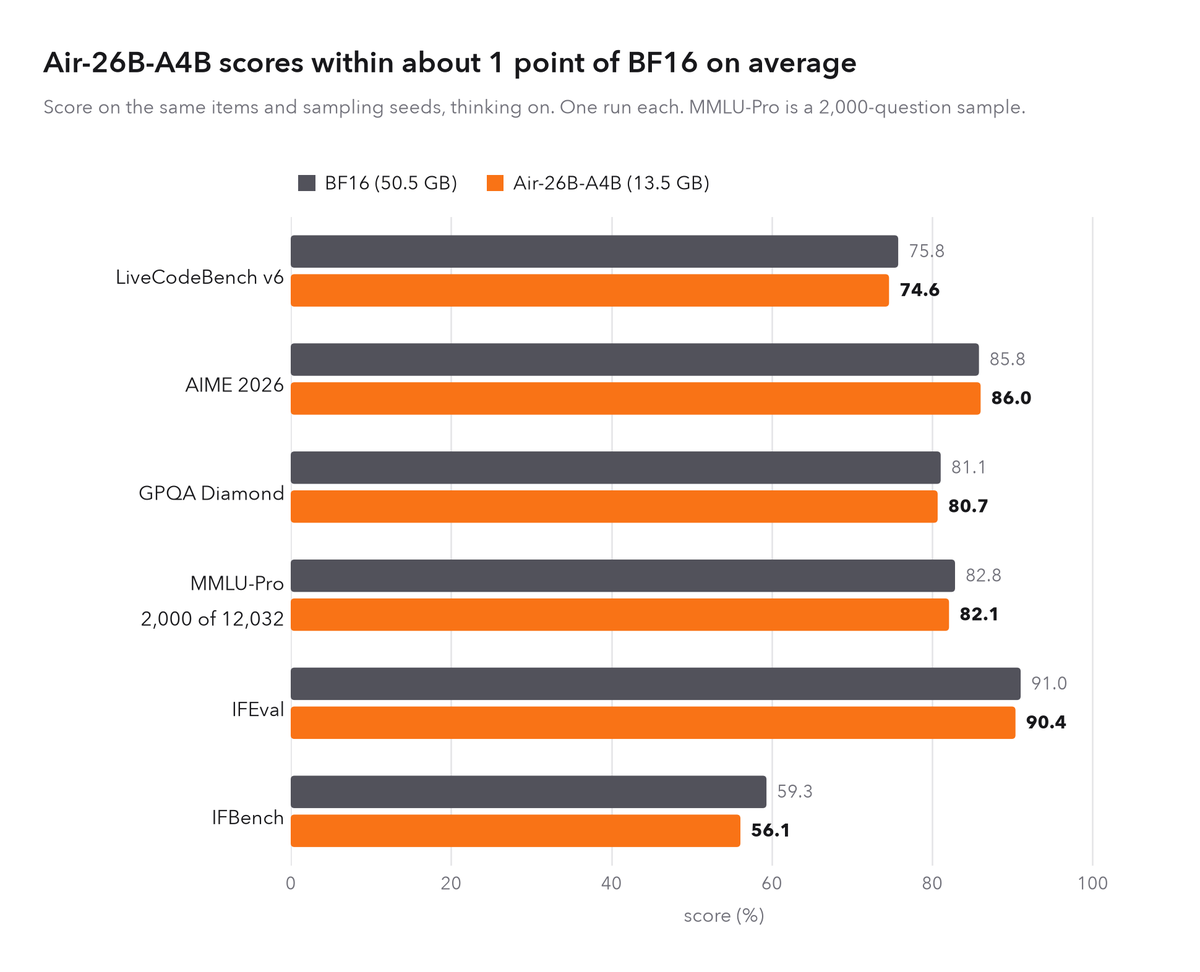
@thewebAI's Intelligence Lab is open sourcing Gemma 26b 4a Air
2.6× closer to full precision
Significantly more faithful to the original model than Google's official 4-bit release (KL divergence: 0.068 vs. 0.176).
Nearly 4× smaller
Just 13.5 GB vs. 50.5 GB, with the full 128K context fitting in 16 GB of memory.
Almost no loss in intelligence
Scores 78.3 vs. 79.3 across 6 benchmarks, retaining 99.4% of original performance on knowledge, math, and coding.
Matches the original on real-world tasks
Nearly identical wIL scores (Track A: 0.502 vs. 0.508; Track B: 0.812 vs. 0.812).
HF: https://t.co/SsQ0AW1Idy
@TylerMauer4@themahmud5@Davidstout@thewebAI Benched Air-26B-A4B on the same 210 tasks:
- Standard 26B Q4_K_M (17.4G): 14.2 tok/s | 180 prefill | 2,400ms TTFT
-❗️26B-A4B (12.55G): 131.9 tok/s (161 pk) | 1,596 prefill | 74ms TTFT | AND top score of all models on the 210 tasks
@EltonJohn184988@Davidstout@thewebAI We released a 3B pro version last month. It performs very well for its size, and uses the same training methodology.
https://t.co/w7jxCdTbnk
@bleed811@thewebAI That’s a great question.
@DevinWhiteAI
what’s the oldest M chip we’ve benchmarked this on?
I am using my M3 MacBook Air and the tp/s provided a good user experience.
Awesome benchmarks, thanks for sharing. I’d be curious to hear your feedback on the Gemma Air quantization we released today as well.
The team uses the feedback to know where to focus on improving the next generation.
The more you find areas it excels, shows promise, or falls short let us know so we can improve the next one!