We just launched our new Integrations page! 🧩
It’s a centralized resource for connecting UltiHash to AI tools via our robust S3-compatible API.
https://t.co/HodjrOtfEK
Which integrations should be next?
#ai#data#mlops#storage#integration#S3#infrastructure
🔐 Encryption shouldn’t be an afterthought. From moving ML checkpoints to storing raw training datasets, UltiHash places encryption at the core of our Kubernetes architecture.
https://t.co/MpMDEwuYFU
UltiHash is on @CRN's prestigious annual Storage 100 list! 🎉
The list spotlights best-in-class storage solutions: innovative companies delivering cutting-edge technology with high-impact strategic partnerships.
Thanks for the recognition! ❤️
https://t.co/u2geCRSuJI
We’re speaking at Global AI Bootcamp Berlin tomorrow! At 18:25, we’ll be sharing how high-throughput object storage can massively speed up AI workloads. Plus, you’ll get an exclusive first look at the brand-new UltiHash serverless offering ✨
https://t.co/eNXt7qXCDh
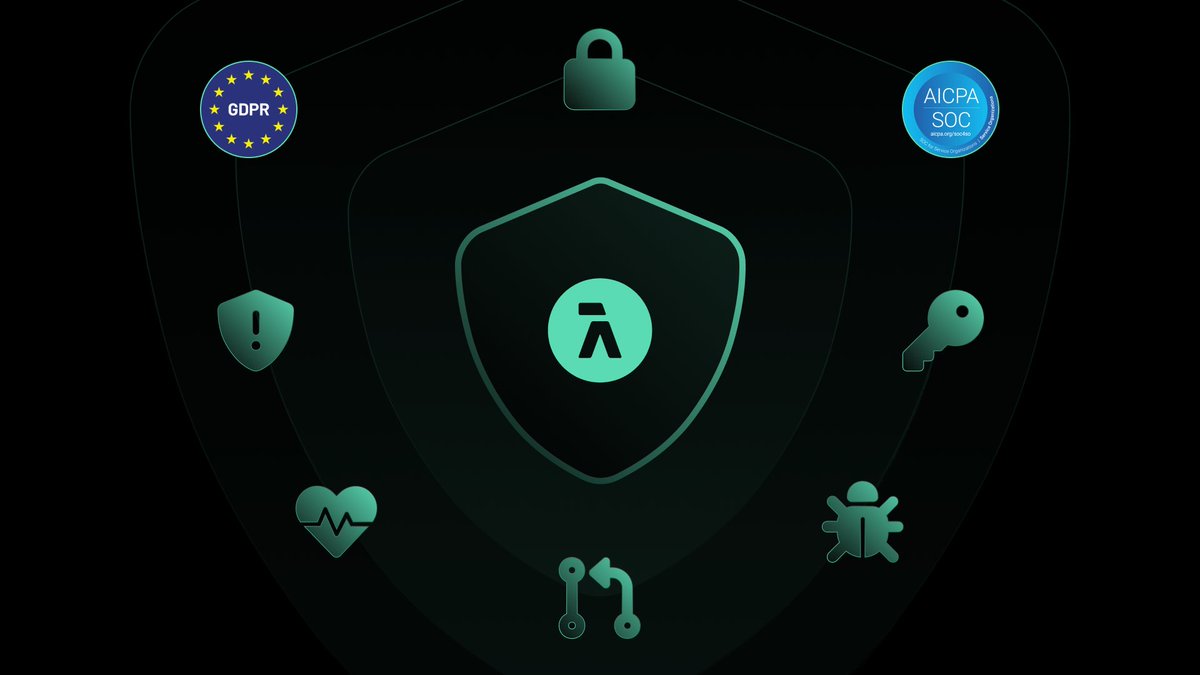
Security is the foundation of UltiHash - head to https://t.co/Ptt1m46t4d to learn more.
✅ SOC Type II Certification, ✅ GDPR compliance
✅ Encryption, ✅ Controlled access
✅ Monitoring, ✅ Incident response + disaster recovery
�� Secure dev lifecycle, ✅ Bug bounty program
Graph DBs like @neo4j are amazing - but what about retrieving raw files like videos, PDFs, or images? UltiHash can help:
✅ Run Cypher queries to return linked files
✅ Retrieve data directly from UltiHash
✅ Slash costs with built-in deduplication
https://t.co/1AAbq22p5j
Managing petabyte-scale datasets just got a lot easier with our new integration with Apache Iceberg! 🎉
✅ Write Iceberg tables to UltiHash
✅ Run queries on large-scale data
✅ Slash storage costs with deduplication
https://t.co/bulSYpZRDw
We just launched our new Integrations page! 🧩
It’s a centralized resource for connecting UltiHash to AI tools via our robust S3-compatible API.
https://t.co/HodjrOtfEK
Which integrations should be next?
#ai#data#mlops#storage#integration#S3#infrastructure
UltiHash is now SOC 2 Type II certified, after a rigorous 3-month audit! 🔒
✅ Robust access controls
✅ Strong encryption for internal data
✅ Continuous internal risk monitoring
✅ Incident response plans, plus tested backups.
✅ Secure dev lifecycle
https://t.co/hQaPPmaejd
🎉 Excited to announce our integration with @superannotate - the one-stop platform for building annotation workflows for AI.
Combined with UltiHash's high-performance object storage, AI teams can now work faster, more efficiently, and at a lower cost.
https://t.co/ZFIw65ZZMz
Don’t pay for more AI storage than you need! UltiHash now offers pay-as-you-go.
Decide what's best for you: PAYG for scaling, experiments or flexibility, or subscription for the best price per GB.
https://t.co/Gwlac7SNBB
#ai#objectstorage#payasyougo#data#machinelearning
Excited to announce UltiHash 1.3.0, packed with new features and enhancements! 🚀
We added pay-as-you-go, improved S3 compatibility, and an option to bypass deduplication to unlock even more speed.
Check the thread for more details 👇
#ai#objectstorage#data#machinelearning
Life’s too short for a slow AI stack. How about trying an object storage that makes your data smaller while keeping your data pipelines fast?
You can get started with 10TB completely for free by signing up at https://t.co/r09s8em0Kk
#AI#ObjectStorage#UltiHash
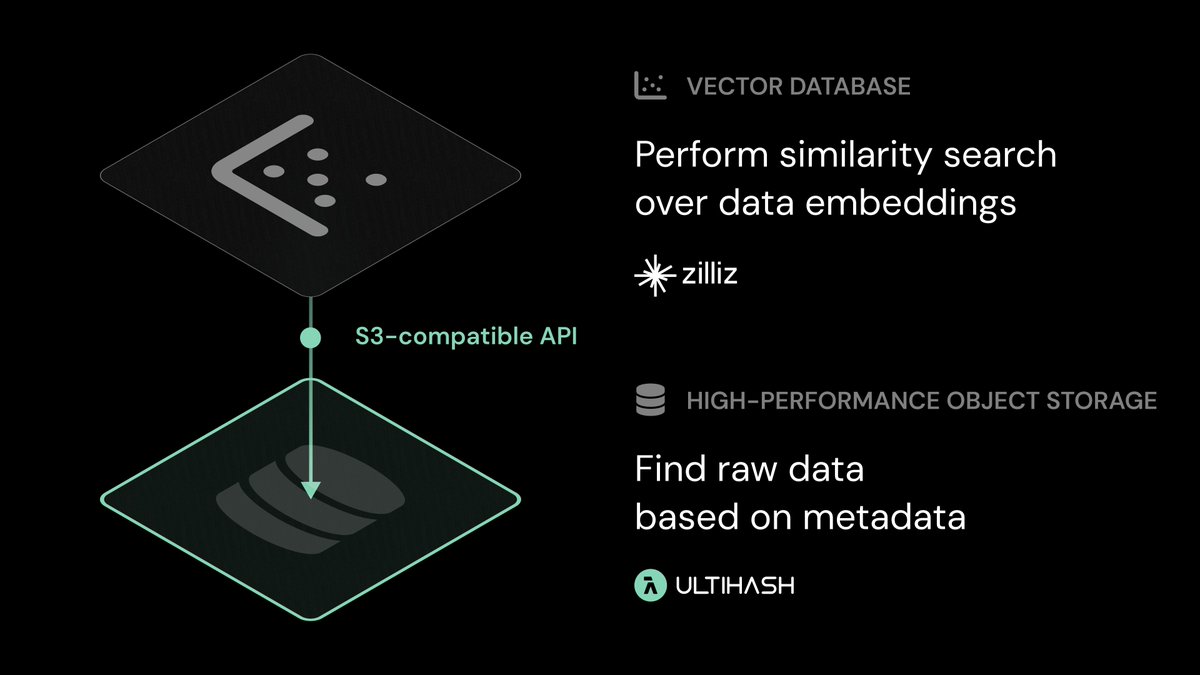
Vector search rocks AI retrieval—think “sunset at the beach” 🌅 images from text. Needs fast storage tho.
We've built a pipeline w/ UltiHash + Zilliz: fast retrieval, scales easy, cuts costs. Full code (CLIP, Flask) here: https://t.co/iYjUbHwKb1
#AI#VectorSearch#UltiHash
Founding Engineer Max Plauth + Dev. Advocate Simon Camp will walk through real-world experience building and using deduplication in UltiHash high-performance storage. Helping you go from bloated AI datasets to resource-optimized AI storage, without sacrificing on performance.
Join UltiHash for an exclusive Deduplication-focused webinar where we'll cut through the complexity of storing AI datasets cost-efficiently and show you how to shrink storage without sacrificing performance.
📅 Date: Thursday, March 6th
⏰ Time: 17:00 CET
📍Link in thread
WHY ATTEND? ✅ How unstructured datasets drive up costs—and how to fight back ✅ When compression fails vs. when deduplication wins ✅ Boost throughput – Keep read/write speeds fast with built-in optimization✅ Live demo + Q&A session – Get your questions answered directly