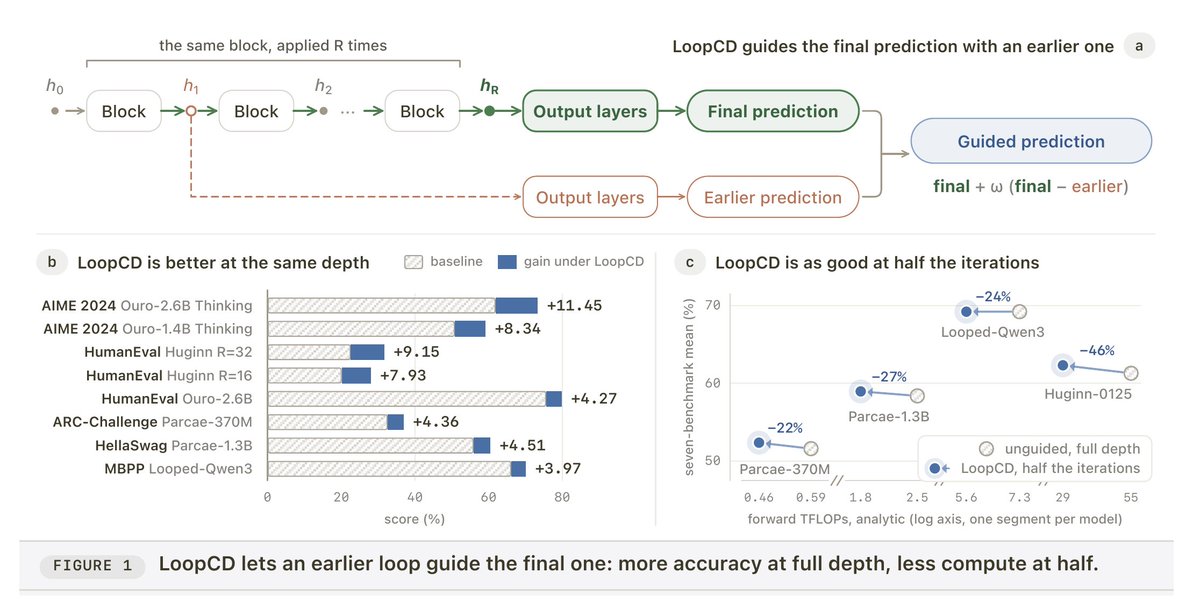
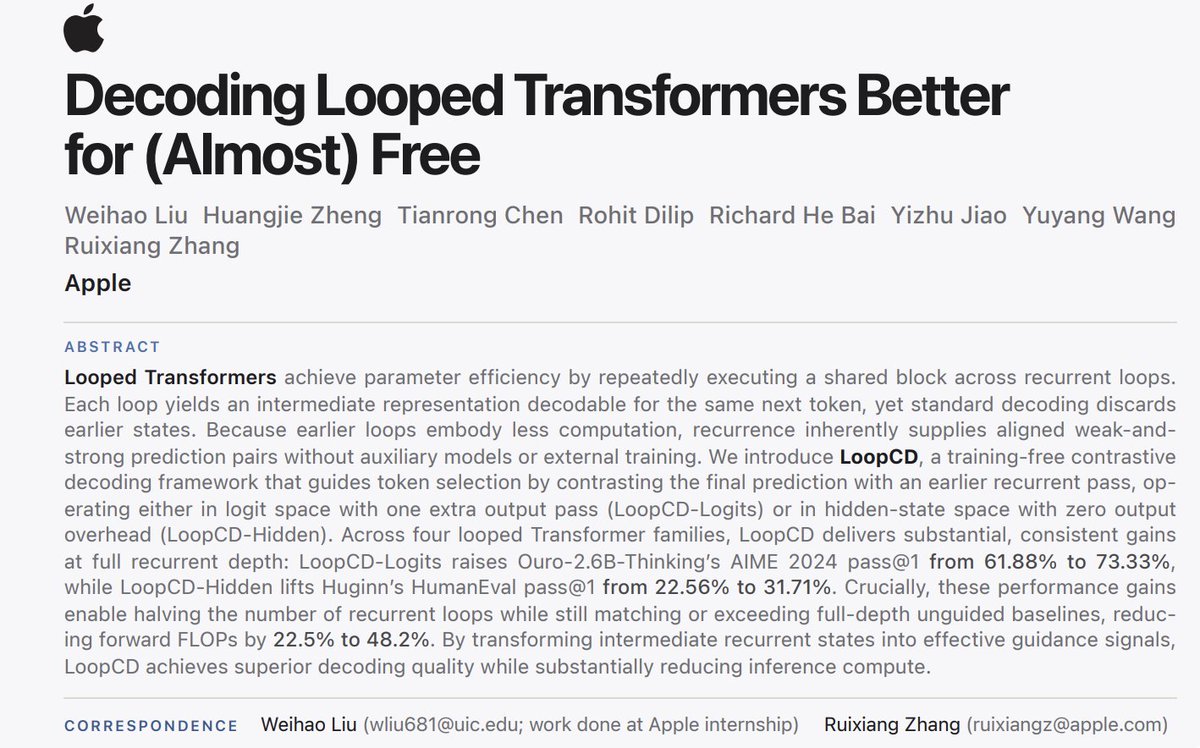
Looped Transformers' earlier states already hold a guidance signal. But standard decoding ignores it.
We use it via LoopCD.
🎯 Full depth: AIME24 pass@1 61.88% → 73.33% (Ouro-2.6B-Thinking)
⚡ Half the loop depth: 7-task mean matches full depth, up to 48.2% fewer forward FLOPs
📄 Paper: https://t.co/mK6rbSgN8y
1/4
Thanks, Rohit @rohit_dilip_ ! I also really enjoyed our insightful discussions and learned a lot from you about diffusion models and autoguidance. Exploring these connections with looped Transformers together was a highlight of the collaboration. Excited to see where this cross-pollination leads next!
Check out Weihao’s very cool work on looped transformers!
some meta commentary: there are very rich connections between diffusion models and looped transformers, and I think we’ll continue to see cross pollination. From my side, learning from weihao about looped transformers was a high point of my time at apple :)
Apple presents LoopCD:
- Enables halving the number of recurrent loops while still matching or exceeding full-depth baselines
- AIME 2024 pass@1 from 61.88% to 73.33%
https://t.co/rUc748WtYj
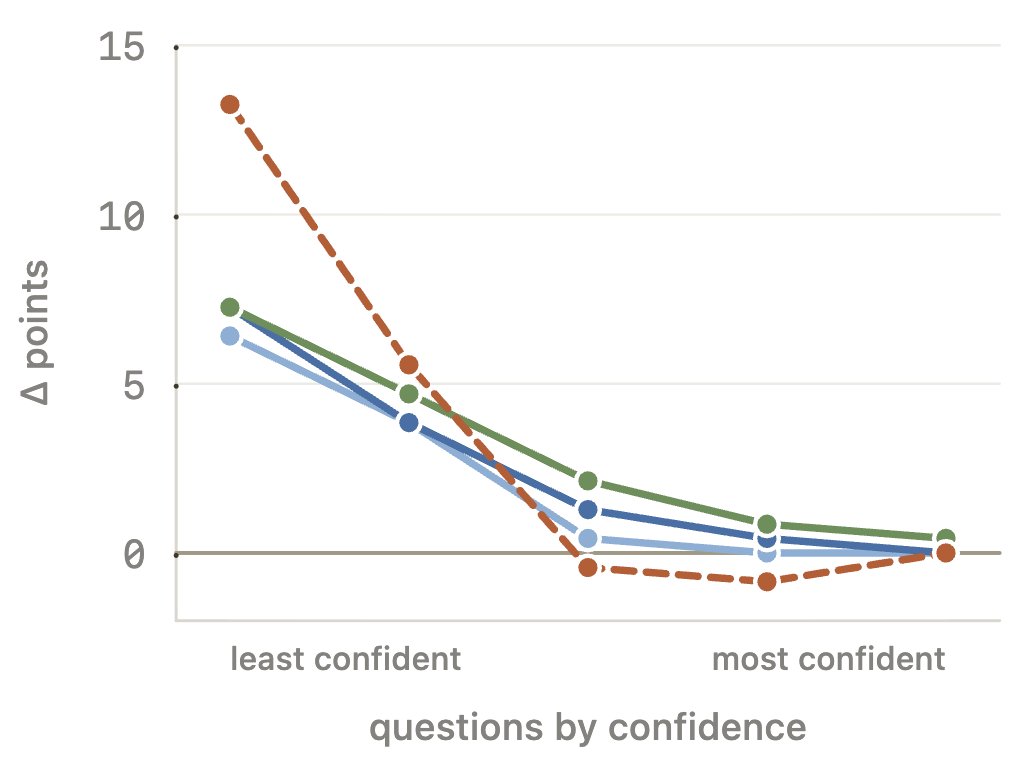
🤔 Why does it work?
Recurrence settles most decisions early and leaves a few close ones. The earlier state shows which way the model was moving.
👉 LoopCD keeps going that way: it helps on close, uncertain choices, and confident answers mostly stay put.
4/4
Looped Transformers' earlier states already hold a guidance signal. But standard decoding ignores it.
We use it via LoopCD.
🎯 Full depth: AIME24 pass@1 61.88% → 73.33% (Ouro-2.6B-Thinking)
⚡ Half the loop depth: 7-task mean matches full depth, up to 48.2% fewer forward FLOPs
📄 Paper: https://t.co/mK6rbSgN8y
1/4
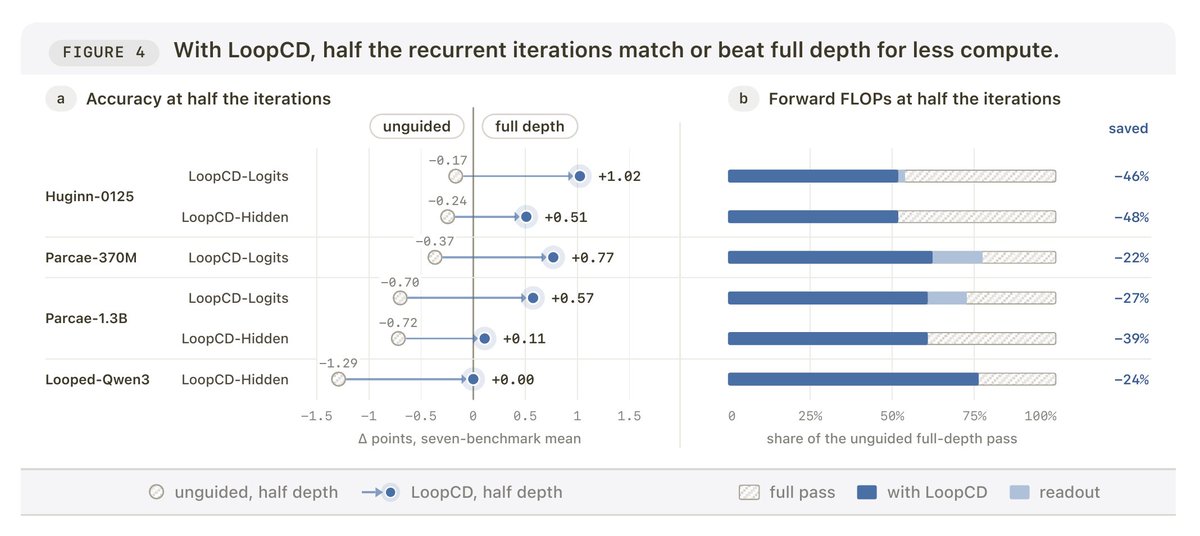
⚡ The part we find most useful: you can loop less.
Halve the recurrent iterations and add LoopCD. On the 7-benchmark multiple-choice mean, it matches or beats the full-depth unguided model in all 6 settings we ran.
📉 22.5–48.2% fewer forward FLOPs, guidance overhead included.
3/4