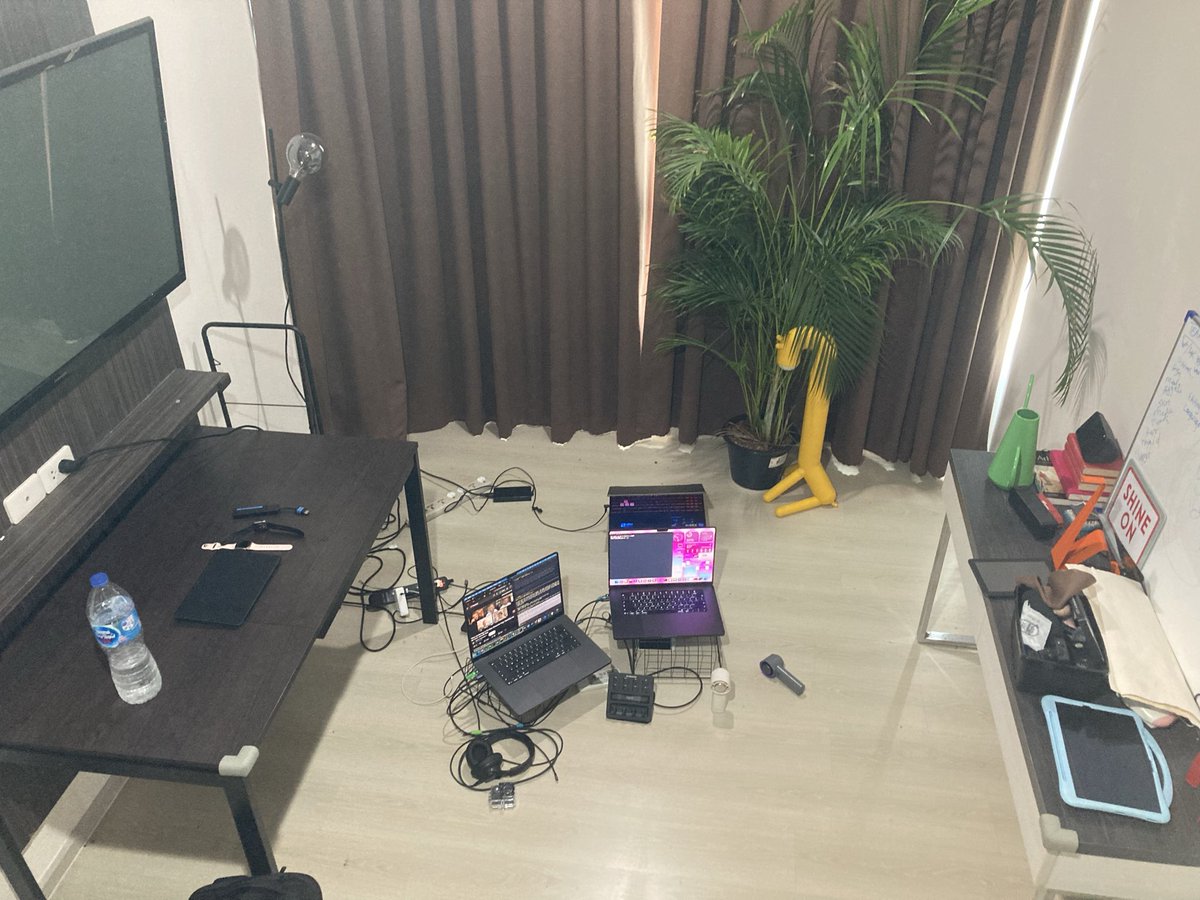
SUCCESS ! I got a 753B-parameter model running fully local.
It runs across two M5 Max laptops wired together with one Thunderbolt cable. About 16 tokens a second. thanks @UnslothAI@Zai_org@Hikari_07_jp@antirez watching them past day or so got me hype! guess @jun_song may have to re-update local list ranking
HOT TAKE :
This is a great start for using a Mac but
I'd argue it's a waste on M5 Max you can get 80 tok/s on same machine but with qwenflash next 4-8 mixed.
So while it is great, still not enough to be used for real work where your output is what the client pays for imo.
Qwen3.8-27B at 144 tok/s on an M5 Max MacBook Pro ⚡
Meet Inco Splash: our open-source inference engine, built around the model and around Apple silicon.
Up to 3× the decode speed of Ollama, 2× oMLX, and almost 4× when an agent fans out into sub-agents.
@TTrimoreau People who passed on you will circle back.
They will have wasted your time, kicked the ball down
the road, promised you false hope, and then you'll
make it.
You have to be the bigger person.
Contract completed!!
I bargained with the wife no more broom closet! building the home lab in the spare bedroom upgrading from the sun room!!!! Real testing/exploring can begin!! @OmarchyLinux is about to breathe life into a lot of decommissioned tech I have!