@CVPR scheduling can be chaotic, so we made … a PLAN. 😄🗺️
✨𝗣𝗟𝗔𝗡 𝗟𝗮𝗯 is heading to Denver with 7 papers at CVPR 2026, and we put everything in one place so you can browse the work, watch the videos, find the posters, and add sessions to your calendar.📌
Explore our #CVPR2026 hub and come meet us in person 😊
Click on the banner https://t.co/xAFAe248Op
Direct link https://t.co/T9FAGeCagY
See you in Denver!🏔️
#CVPR2026 #CVPR26 #ComputerVision #MultimodalAI #GenerativeAI #EmbodiedAI
Can fast generative models still be likelihood-based?
Excited to share our new work @Apple MLR --Normalizing Trajectory Models
a step toward high-quality few-step generation with exact trajectory likelihood, powered by normalizing flows.
Paper: https://t.co/4VjJZpW4pC
[1/9]
🚀 Excited to share my internship work at Apple MLR :
STARFlow2: Bridging Language Models and Normalizing Flows for Unified Multimodal Generation
STARFlow2 uses autoregressive normalizing flows to bridge LLM-style causal decoding and continuous image generation. Built on the 🥨 Pretzel architecture, it vertically interleaves a pretrained VLM with a TARFlow stream, preserving pretrained VLM understanding while enabling rich cross-modal interaction within a single causal sequence model. It supports exact likelihood training and cache-friendly interleaved text-image generation — without image tokenization, diffusion loops, or visual re-encoding.
Huge thanks to Jiatao @thoma_gu for the guidance and support throughout the process, and to all the wonderful collaborators who made this possible! 🙏
Arxiv: https://t.co/Rb4QnZsa3D
Excited to share STARFlow2 from Apple MLR :
🥨Bridging Language Models and Normalizing Flows for Unified Multimodal Generation.
One model to understand, reason, and generate continuous images with a single unified autoregressive mechanism?
Paper: https://t.co/IA1pJ5AtOX
1/9
Huge thanks to my amazing collaborators Jerry Xiong, @yu_tianjiao, my advisor @Ismini_L, and to the PLAN Lab (https://t.co/eM60jEH5VW) for all the support! 🙏
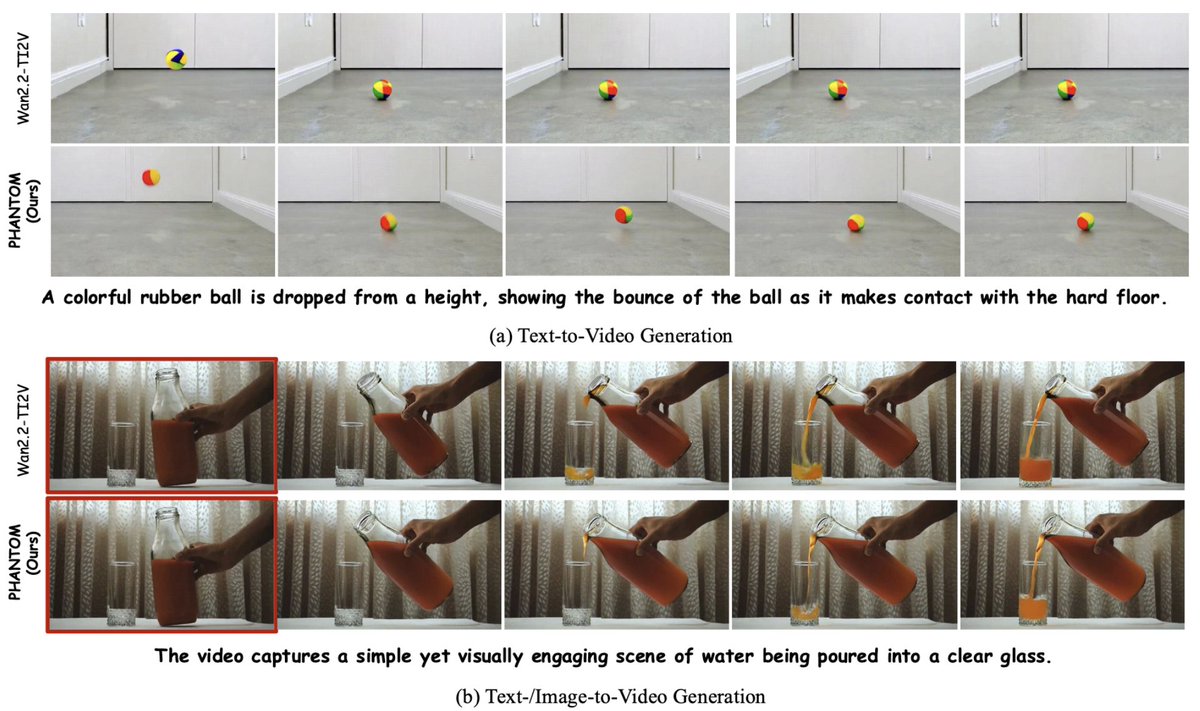
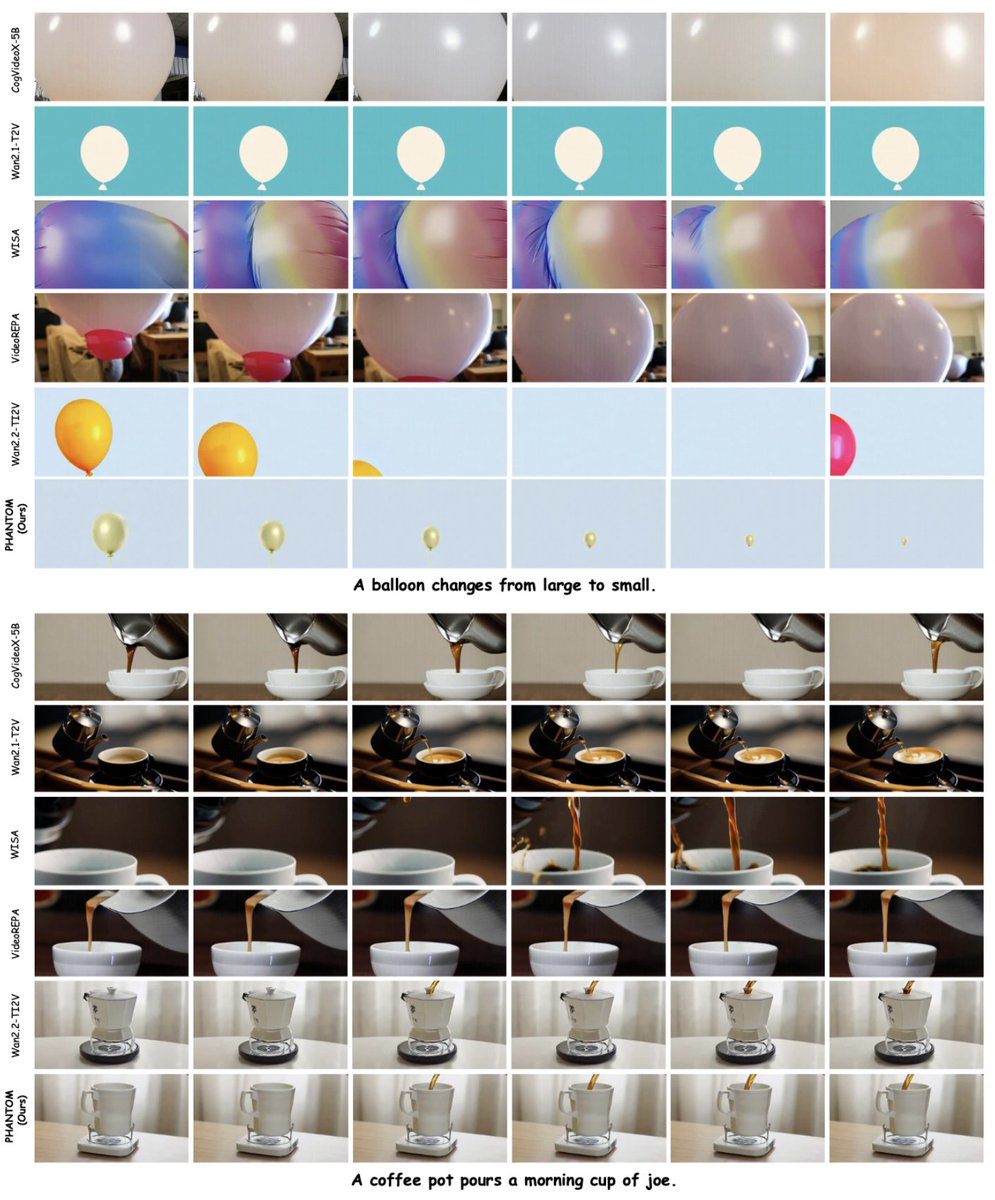
Introducing Phantom 👻 — a Physics-Infused Video Generation model that jointly models visual content and latent physical dynamics without requiring explicit specification of complex physical properties. 👇🧵[1/3]
🌐 https://t.co/pXHeWv9AjL
📰 https://t.co/I8PJAXZXJE
Quantitative and qualitative results on both standard video generation and physics-aware benchmarks demonstrate that Phantom not only outperforms existing methods in terms of adherence to physical dynamics but also delivers competitive perceptual fidelity. 🧵 [3/3]
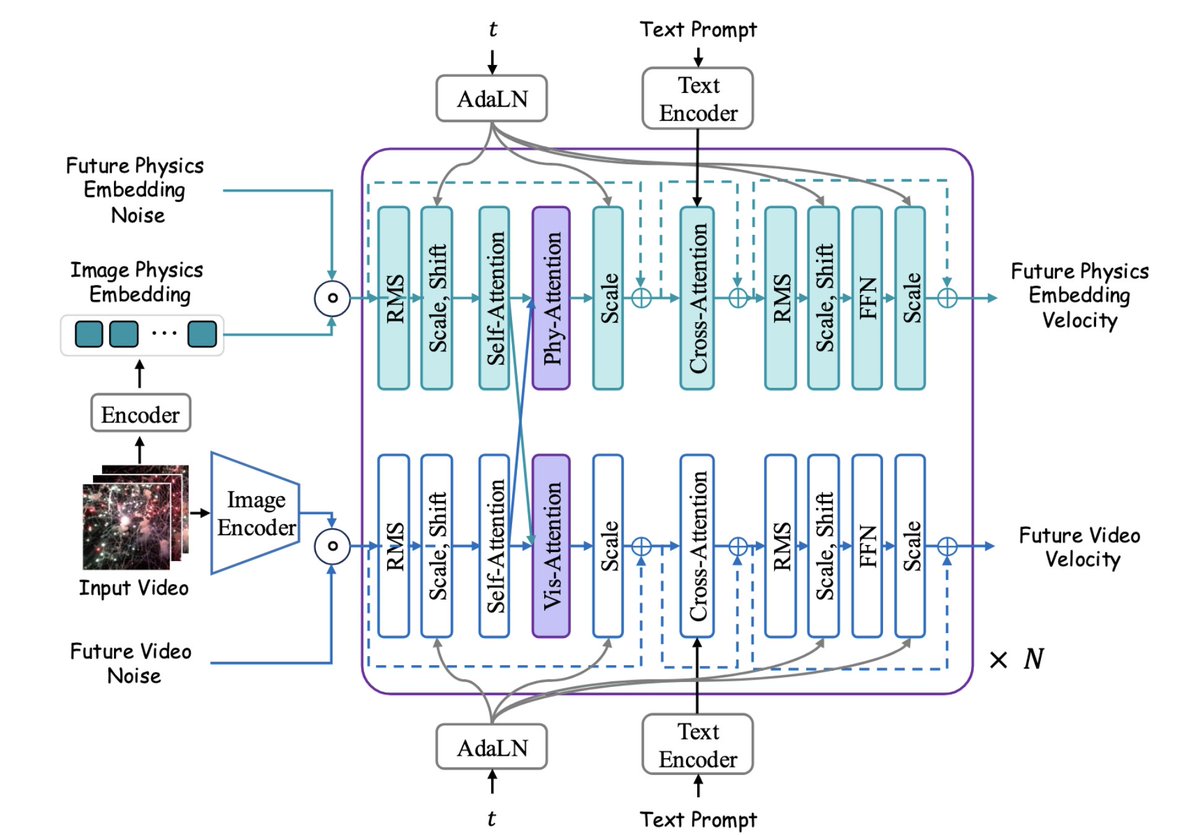
Phantom uses a dual-branch architecture: a video branch for visual trajectories + a physics branch for latent physical dynamics. The physics branch learns a physics-aware video representation that serves as an abstract yet informative embedding of the underlying physics. 🧵[2/3]
It is a huge pleasure working with @thoma_gu and the entire team. Huge thanks to everyone involved!
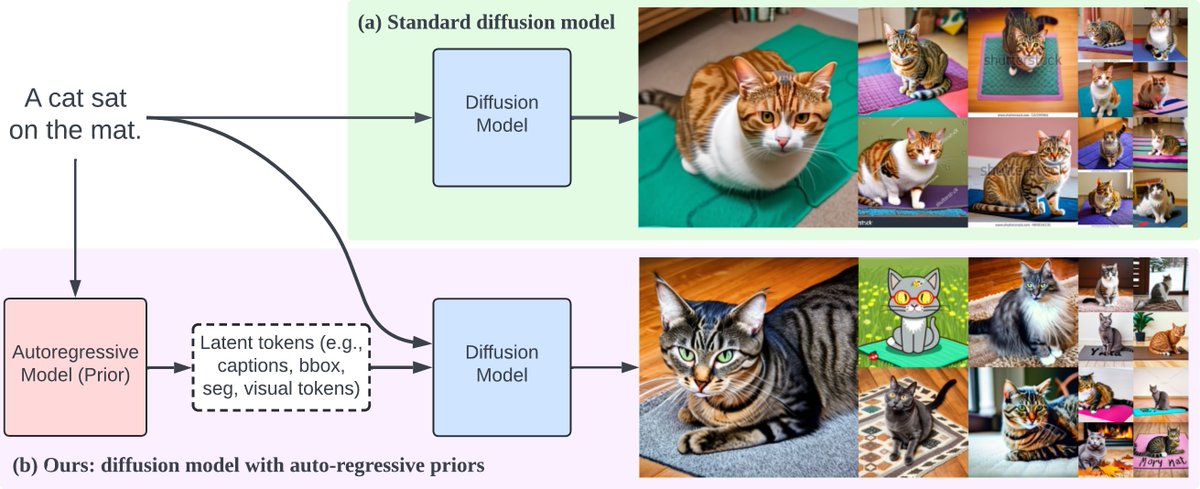
We introduce KaleidoDiffusion—a novel method that enhances conditional diffusion model generation by integrating autoregressive latent priors. This technique allows us to produce significantly more diverse outputs, even with high CFG, just like a kaleidoscope🔭!
Please check out our paper for more details: 📃 Paper: https://t.co/JT1FfUBolg
🚀Excited to introduce KaleidoDiffusion --
a new method that improves conditional diffusion model generation by incorporating autoregressive latent priors! This allows us generate much more diverse outputs even with high CFG just like a kaleidoscope🔭!
(1/n)
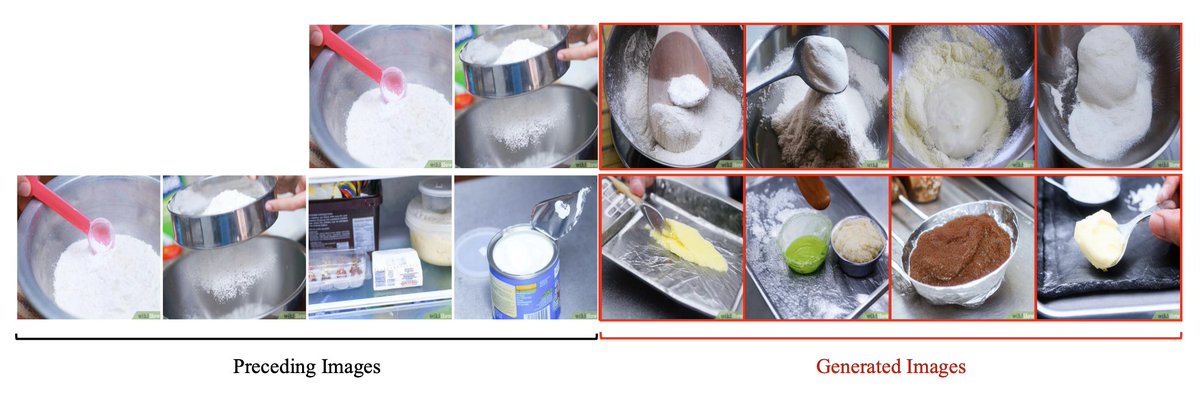
🚀 Excited to introduce my internship work at @Apple MLR : Many-to-many Image Generation with Auto-regressive Diffusion Models (https://t.co/YKTexvRdLM). Exploring the paradigm for domain-general multi-image to multi-image generation.
A heartfelt thank you to my amazing collaborators @YizheZhangNLP@zhaisf@lifu_huang @jsusskin, and to my internship manager @thoma_gu for their guidance and support!
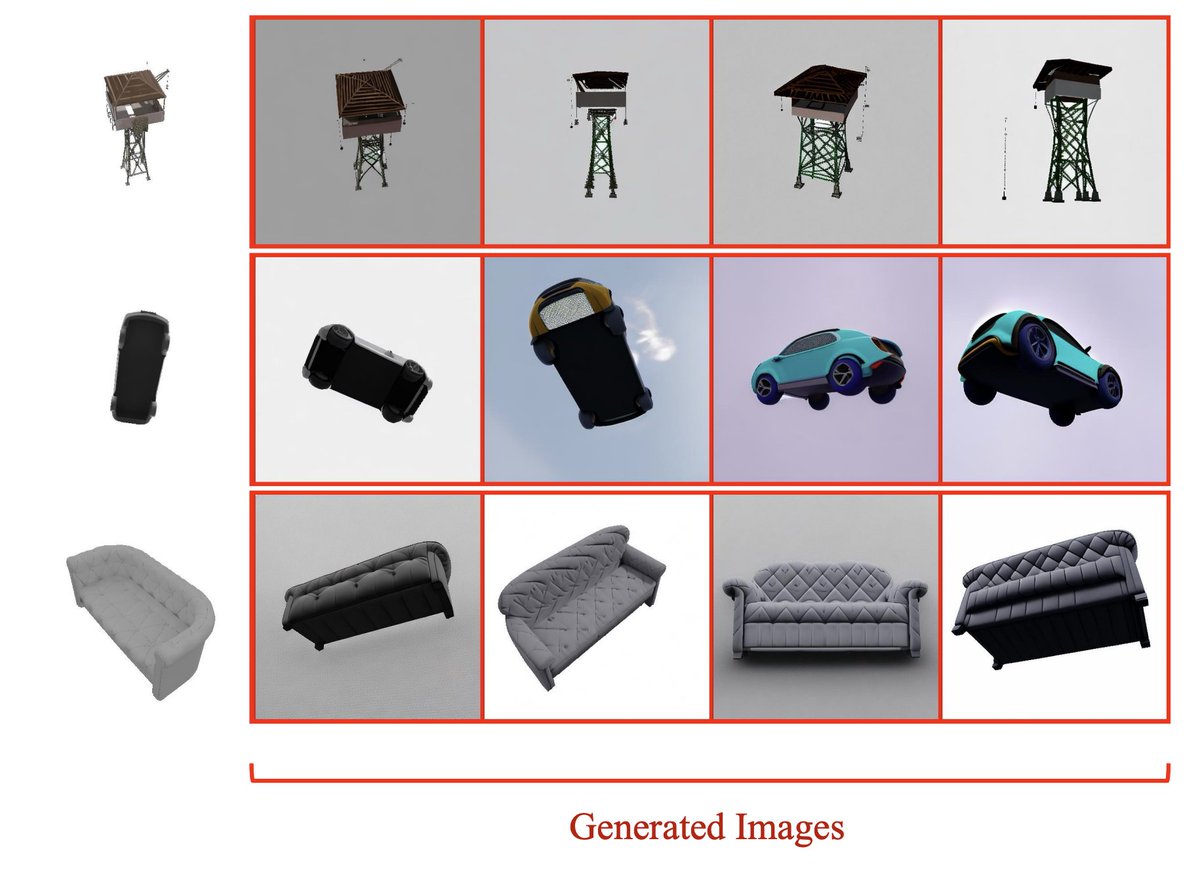
Through simple task-specific fine-tuning, M2M demonstrates its adaptability to various multi-image generation tasks, including Novel View Synthesis and Visual Procedure Generation, suggesting its potential for customization to specific multi-image generation tasks.
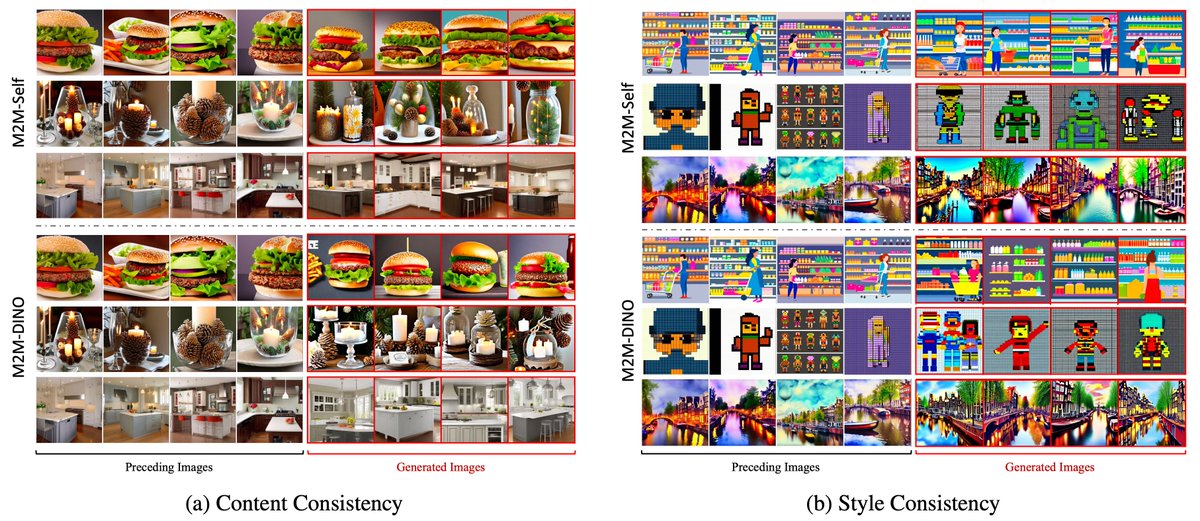
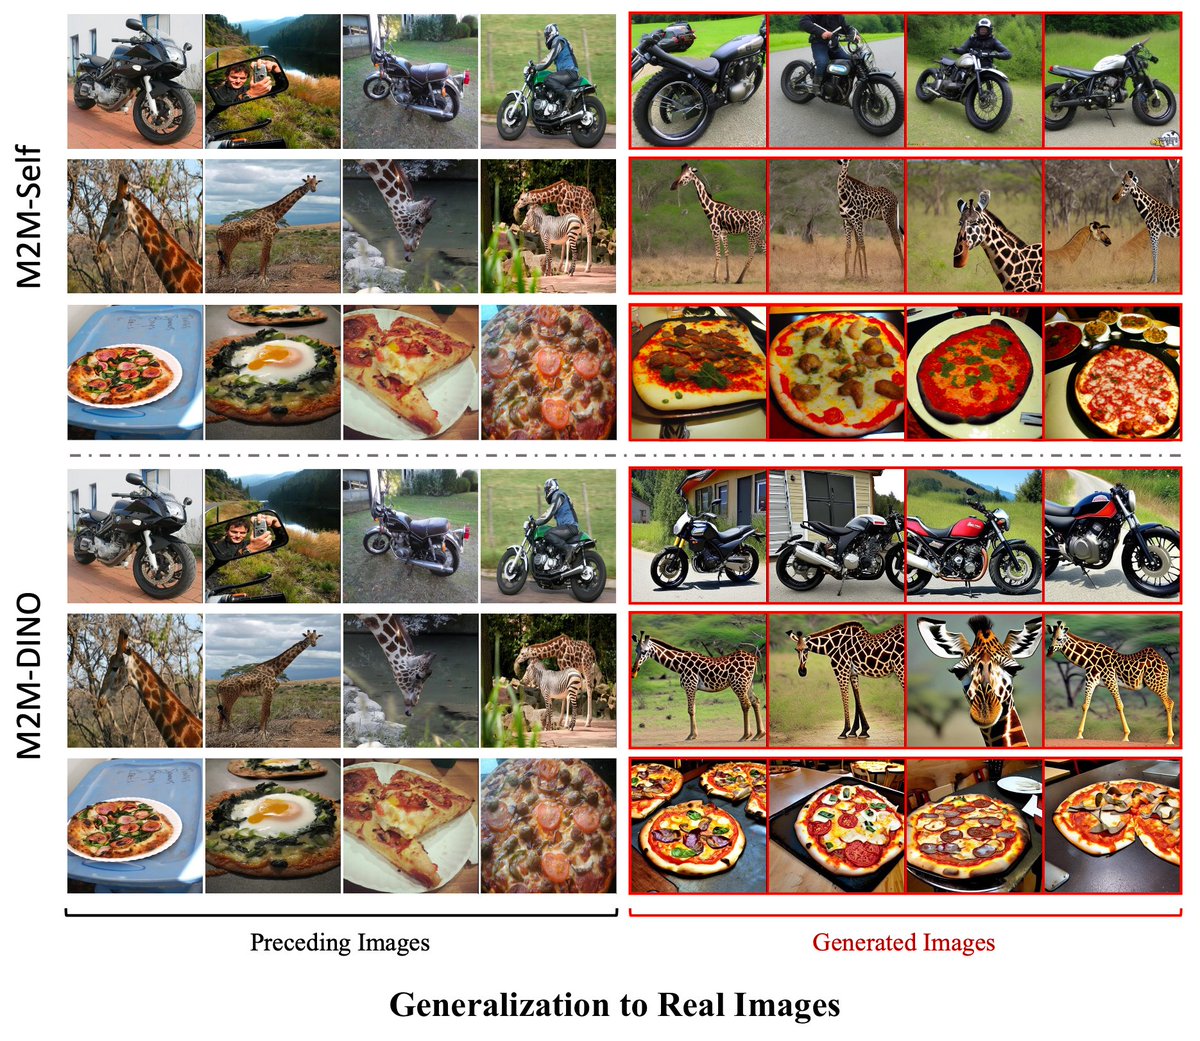
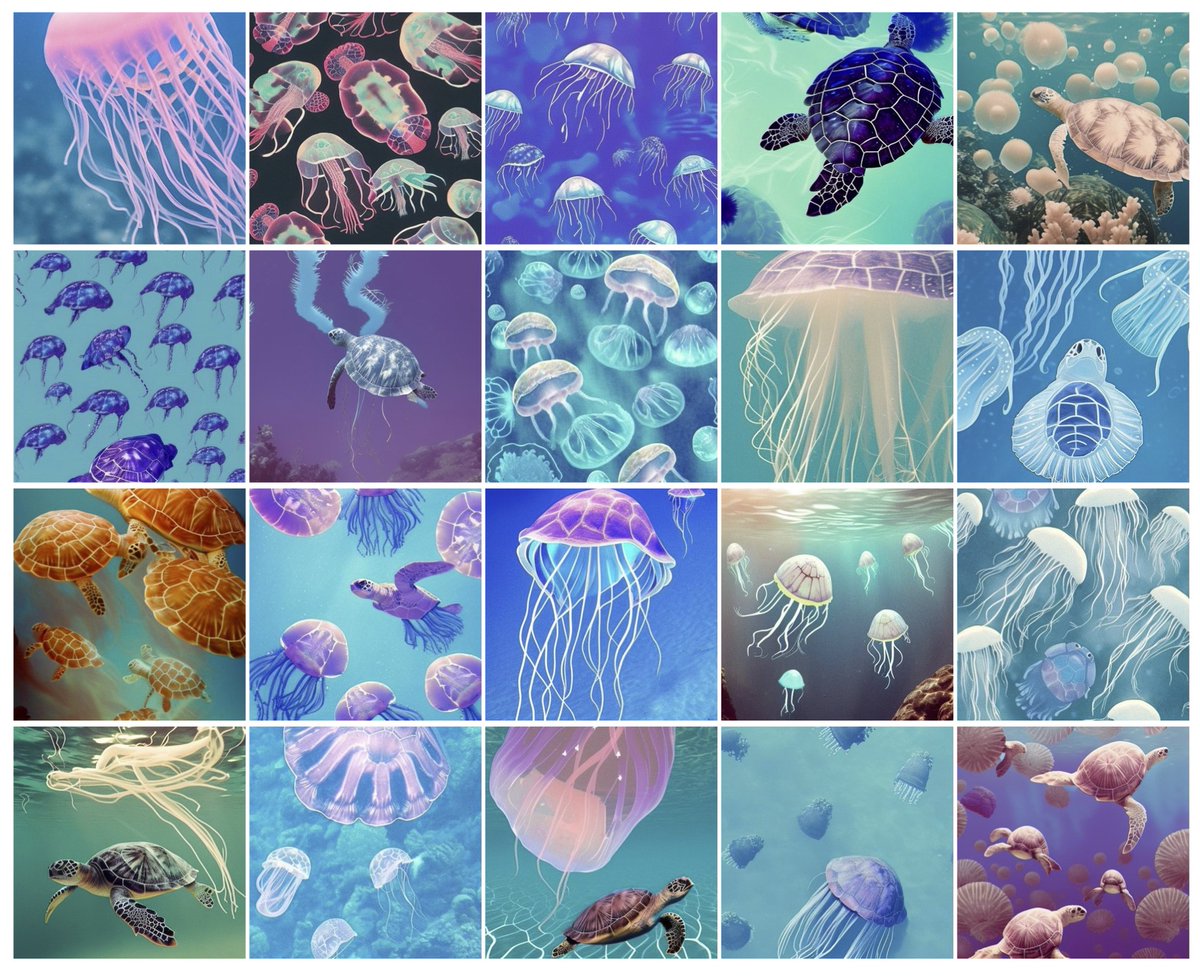
M2M captures style and content from preceding images and generates novel images in alignment with the observed patterns. Impressively, despite being trained solely on synthetic data, M2M exhibits zero-shot generalization to real images.
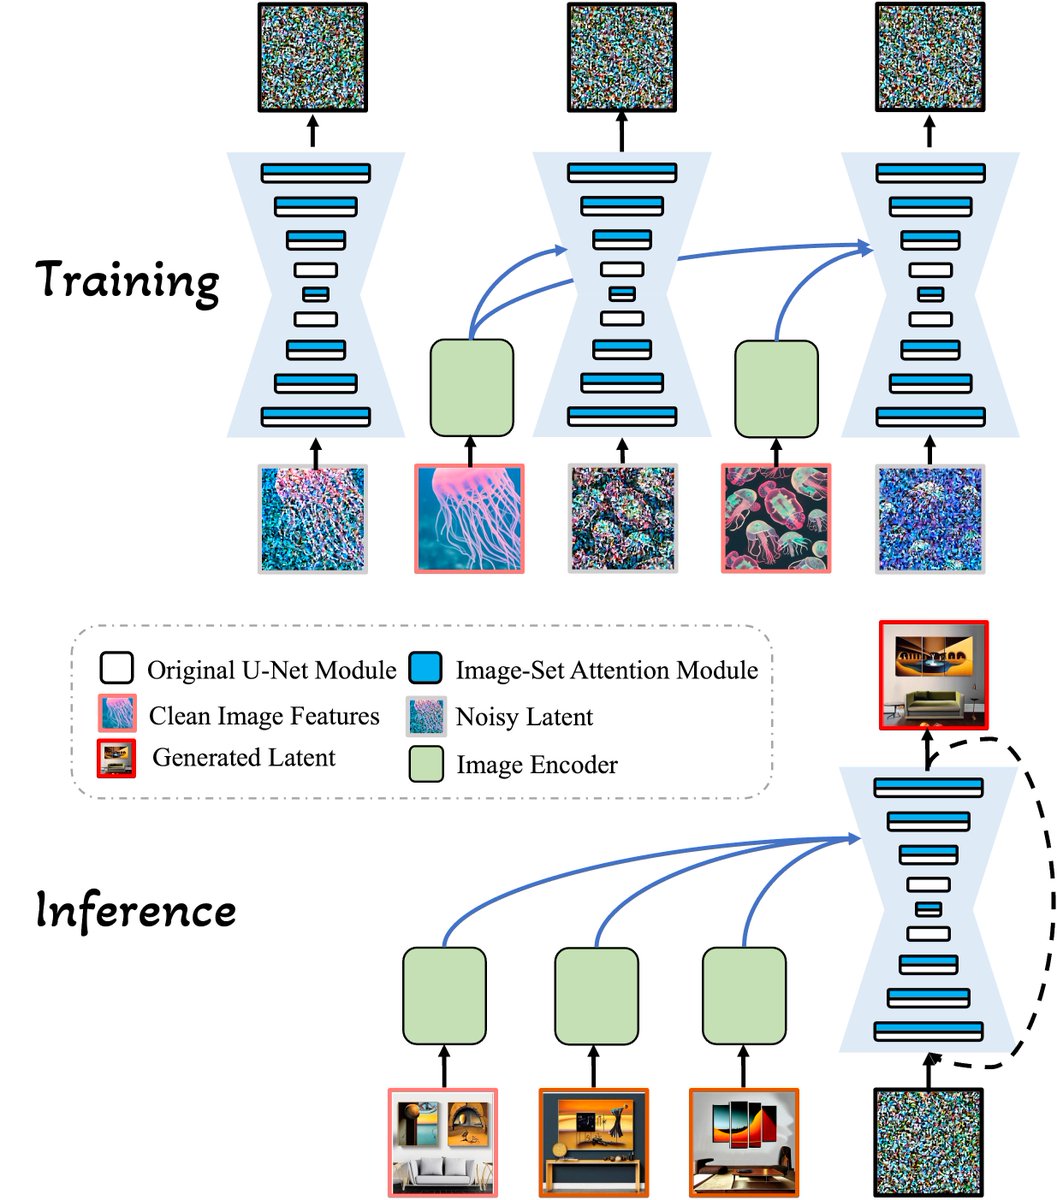
With MIS, we present a domain-general Many-to-many Diffusion (M2M) model, a conditional diffusion model that can perceive and generate an arbitrary number of interrelated images in an auto-regressive manner, thus offering the flexibility and adaptability needed to meet a broad range of multi-image generation tasks.
🌟 Introducing MIS: the first-ever large-scale multi-image dataset comprising sets of images interconnected by general semantic relationships. MIS consists of a total of 12M synthetic multi-image set samples, each with 25 interconnected images. Designed for broad, domain-general multi-image generation.
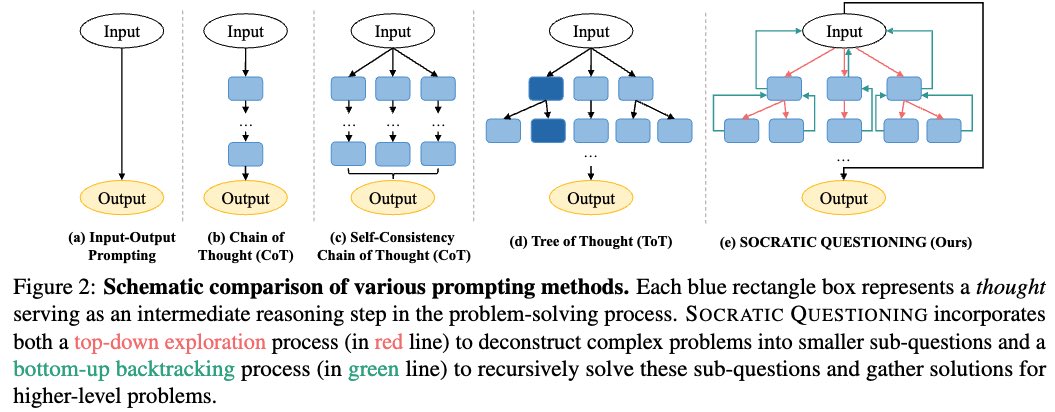
Our new work ✨The Art of SOCRATIC QUESTIONING: Recursive Thinking with Large Language Models✨ is accepted to #EMNLP2023. Inspired by the human cognitive process, we propose SOCRATIC QUESTIONING, a divide-and-conquer style algorithm that mimics the 🤔recursive thinking process.
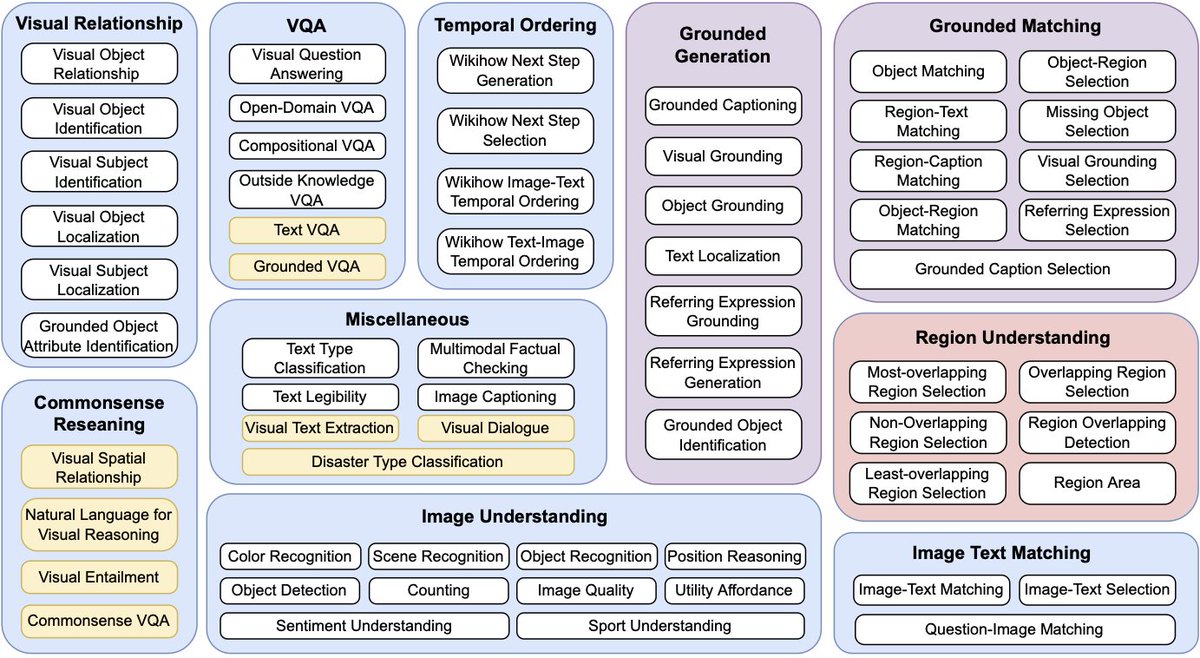
Today we officially release ✨Vision-Flan✨, the largest human-annotated visual-instruction tuning dataset with 💥200+💥 diverse tasks.
🚩Our dataset is available on Huggingface https://t.co/XqFrpudysl
🚀 For more details, please refer to our blog https://t.co/HY1D6xrCPm
Struggling with catastrophic forgetting when updating your model? 🤯 Check out our latest work to appear at Findings of 🌟#ACL2023NLP🌟!
We extensively study the *classifier drift* issue in continual learning and introduce an effective framework for this problem.
📌paper at https://t.co/i4FLviHACx 🧵 (1/n)
📢 Delighted to announce the release of MultiInstruct, our first multimodal instruction tuning dataset! 🎉 Explore the dataset here: https://t.co/ZCq5lYp8wy
We introduce the first multimodal instruction tuning dataset: 🌟MultiInstruct🌟 in our 🚀#ACL2023NLP🚀 paper. MultiInstruct consists of 62 diverse multimodal tasks and each task is equipped with 5 expert-written instructions.
🚩https://t.co/i0Q28z9c0q🧵[1/3]