(1) is not correct, it is not due to 2X charging after 272k context, we don't charge for longer context on the subscription for GPT 5.6 Sol as we control all the settings. It is due to something else, which I will attempt to explain below.
The overall trajectory length, which is the total some of all context windows across compactions, changes little based on the reasoning effort. Similarly the quality of the overall output is similar across context lengths above 272k. The benefits of higher context lengths are mostly overall speed (as you don't wait for compaction), ability to deal with humongously large input and potentially cost if the system is well tuned and you hit your cache perfectly.
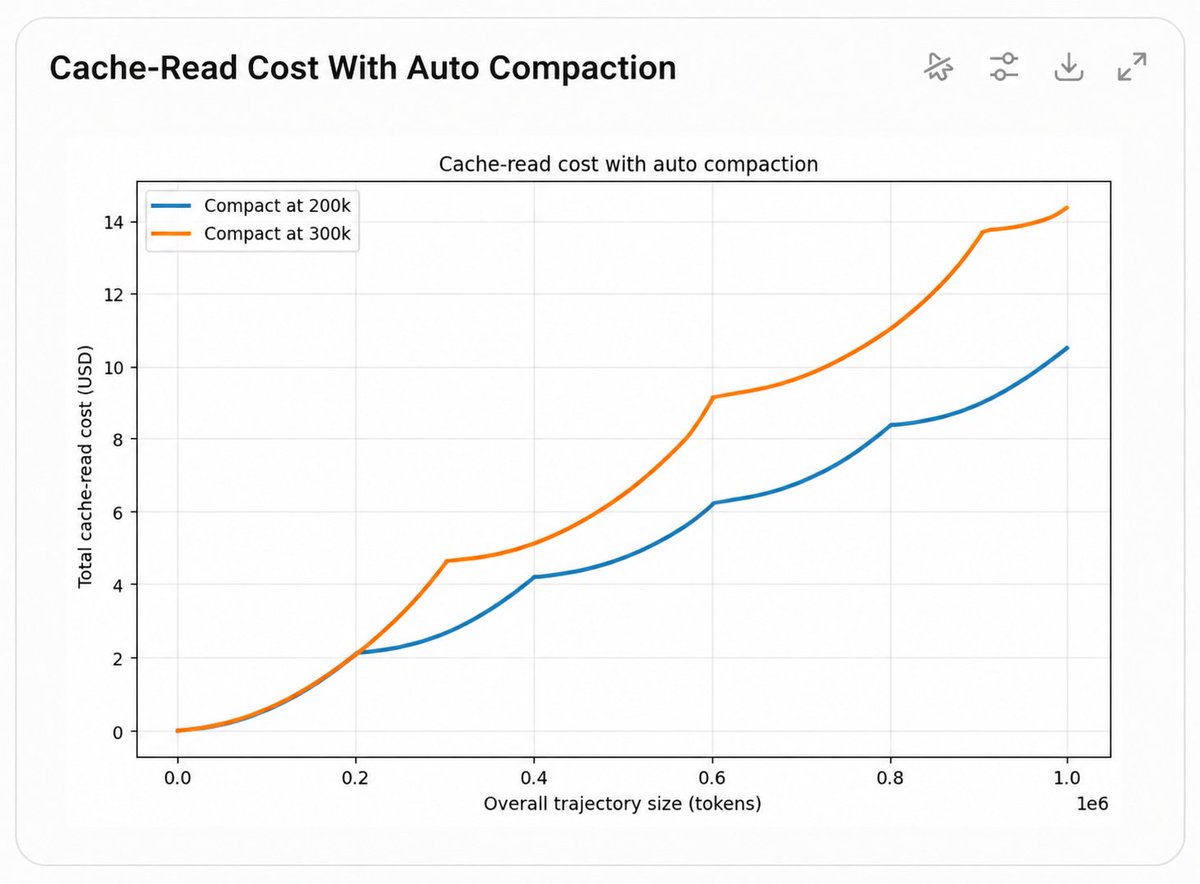
The actual reason is the what you can see depicted in the chart below, which is the difference in the orange line and the blue line. It is caused by overall cost of cache reads going up with the size of the context being shuffled back and forth between toolcalls. The sweet spot in terms of cost is therefore not necessarily to use the maximum possible context length.
What we're working on is tuning the system differently so that we can go back higher without it resulting in higher usage being charged. Hope this clarifies a bit.