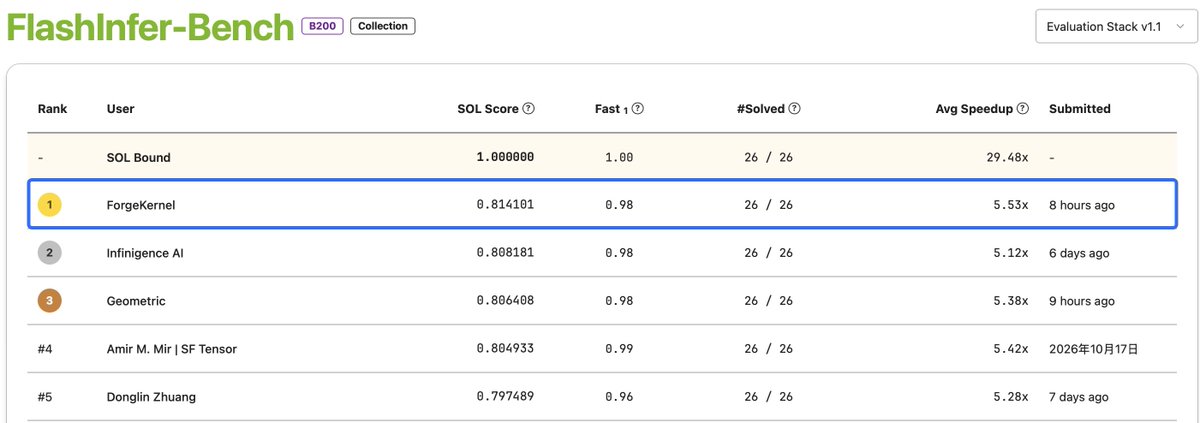
The ForgeKernel paper is now released. Last week, we boosted DeepSeek V4.1 FlashMLA real-time by 9.8% using ForgeKernel.
Paper: https://t.co/EEAkpTZl4E
Check out what the paper includes:
1. Architectural decision-making: We propose an agent architecture that separates architectural design from code implementation, guides implementation through explicit architectural decisions, and revises these decisions based on performance feedback. When optimisation encounters a structural bottleneck, the method revisits work partitioning, dataflow, or pipeline organisation rather than only tuning locally within a fixed architecture. Across runs, it also re-assesses an existing implementation's architecture rather than directly carrying it forward.
2. Measurement-validated mechanism for cross-run self-evolution: Hardware mechanisms discovered during our kernel optimisation are validated through independent probes on the target hardware before being stored in a knowledge base shared across operators and input shapes. The knowledge base guides architectural design and implementation planning in subsequent runs, converting findings from individual runs into reusable knowledge.
3. Introducing ForgeKernel: It is a self-evolving operator optimisation system that integrates architectural revision, reference updates, and knowledge reuse. Evaluation on NVIDIA Hopper and Blackwell GPUs and Huawei Ascend 910C accelerator demonstrates performance gains over expert and generated references, including a 1.10× geometric-mean speedup on NVIDIA GPUs. As of 2026-10-30, submissions generated by ForgeKernel rank first on all four leaderboards: the three CANN-Bench 2.0 solution leaderboards (Ascend 910C, 950DT, and 950PR) and the SOL-ExecBench FlashInfer-Bench track.
There isn't a fixed number, and that's the point. Within each iteration, the agent decides on its own which optimisation directions to drop and which to push. We don't impose a candidate budget or a pruning schedule; the four-line instruction and the correctness gate are the only constraints.
Do we still need specialized agents for GPU kernel optimization?
We asked the question, and ran the experiment to answer it.
New paper with @THU_NLP: Agents under Goal mode are now able to beat systems deliberately built for kernel optimization. We named it JustGoal.
On FlashAttention, Gated DeltaNet, and DeepSeek Sparse Attention, a general frontier model (in our case, using Fable 5.1) delivers 1.08× to 1.58× speedup over expert-written references. Against the specialized KDA-0.5 (1.45× and 1.28×), Fable 5.1 hits 1.58× on both.
Frontier models are really burying the talent of kernel optimization experts in the past.
Paper: https://t.co/uWKf69B196
Good question. The correctness gate is inside the loop, not after it: every candidate is checked before it counts, so the 1.08×–1.58× numbers are already passed.
Regarding shapes outside the benchmark: a kernel tuned for one shape is not meant to be reused on another. When a new shape or a longer sequence shows up, we run the agent again, and it writes a new kernel for that target. What can be accumulated is the agent's ability to optimise, not any single kernel.
This is what we call Forge Engineering: generate purpose-built artefacts on demand for each platform and workload by a self-evolving agent.
Fair question, and the honest answer is yes: each kernel we produce is specialised deeply for one GPU and specific shapes, and we think that's the right call rather than a flaw.
The key distinction: the kernels are specialised, but the self-evolving system that writes them is general. Point it at a different GPU or a different shape and it forges a new kernel for that target. Nothing in it is tied to H100 or to one input size.
AI writes code fast enough that this is feasible for every hardware target and every frequently used shape. People already do a smaller version of this by hand: tuning for H100's TMA and WGMMA, GEMM libraries dispatching to dozens of implementations. AI just lets specialisation go far past what hand-written code can sustain, so we stop paying the generality-and-abstraction tax.
That's the idea we call Forge Engineering: generate purpose-built artefacts on demand for each platform and workload. ForgeKernel is one instance; ForgeTrain, ForgeStencil and ForgeMegaKernel apply the same idea elsewhere.
ForgeKernel Live ended with a 9.8% increase in the efficiency of DeepSeek V4.1-FlashMLA Prefill. We decided to share our excitement with everyone by open-sourcing ForgeKernel.
ForgeKernel Live page:
https://t.co/y907WrhUWZ
Open-source link: https://t.co/YFL8J9esFI
Quick catch-up on ForgeKernel Live:
⌛️The RSI kernel optimisation had been running for nearly a WHOLE day;
✅31 versions of DeepSeek V4.1-FlashMLA Prefill are listed on the page, written from scratch in an RSI CLI black box without seeing official code;
���It first beat the FlashMLA baseline in Version 13 within 10 hours, and reached 109.8% efficiency in the 23rd hour.
After all these end, we are excited to open-source:
1. DeepSeek V4.1 FlashMLA Prefill optimised version: What we have improved in ForgeKernel Live, representing the frontier of human expert performance in kernel optimisation.
2. All kernels from experiments in the ForgeKernel paper (coming soon): Covering the strongest human expert implementations — DeepSeek V3/V4, Flash Attention 4, Qwen GDN, Kimi Delta Attention — as well as the best kernels released by Kernel Agents such as CAKE and KDA. The kernels generated in our ForgeKernel experiments surpass all of the above.
3. The complete ForgeKernel Harness: You may use it to optimise any kernel.
Based on our previous discovery on JustGoal, we redesigned how we do kernel optimisation and launched a self-evolving kernel optimisation harness called ForgeKernel, a part of our Forge series.
We tried ForgeKernel on SOL-ExecBench(FlashInfer-Bench) from NVIDIA and CANN-Bench from HUAWEI. It performed well and easily reached #1 in every list we tested.
Here are the ranks:
https://t.co/IoM3k9UY19
https://t.co/mHD2RF3qkZ
We'll release another paper on ForgeKernel soon.
At the frontier, the model capacity has caught up in optimising kernels.
The full paper and code will be available very soon. And huge props to the team — a creative collaboration between @THU_NLP and ModelBest's AI for AI Lab.
Sometimes the simplest questions lead to the most interesting answers.
Honestly, the results surprised us too.
Fable 5.1 performs the mission at or above on all three — 1.08× to 1.58× over the expert references. KDA-0.5, which is built specifically for this job, scores 1.45× and 1.28× on the same operators, while Fable 5.1, carrying zero kernel-specific machinery, hits 1.58× on both.
This means the general agents easily passed the best implementation within hours.
The default answer of kernel optimisation has been "specialised": each complex system wraps an LLM in elaborate domain machinery like curated knowledge bases, profiler integrations, and prescriptive workflows.
Now we have deleted the whole framework that may limit models.
A goal-mode agent, a correctness gate, and a four-line instruction telling the model to surpass the best implementation. That's all about Justgoal.
Testbed: FlashAttention, Gated DeltaNet, and DeepSeek Sparse Attention.
China’s drone control system has gone insanely next-level. 33,615 drones completed high-precision flight simultaneously, looking like they were building a parallel world in the sky.
This has also refreshed the Guinness World Record that China set before.
China's Unitree just dropped H2-X Kung Fu Legend Guardian.
Dents car doors. 4 meter drops. Spinning kicks + flips. Even lifts front of a car.
We are cooked 💀