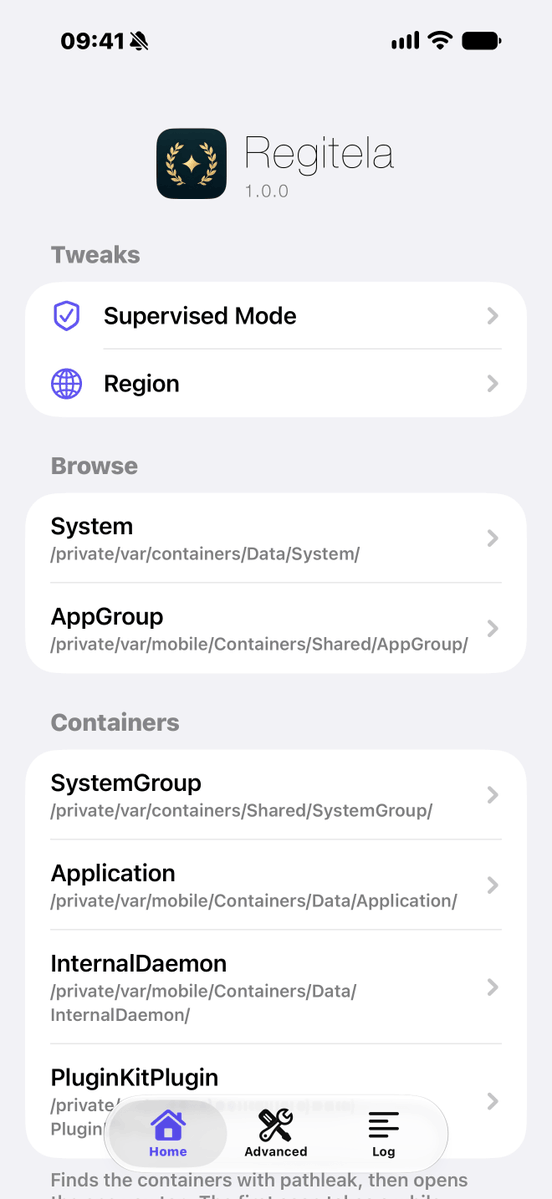
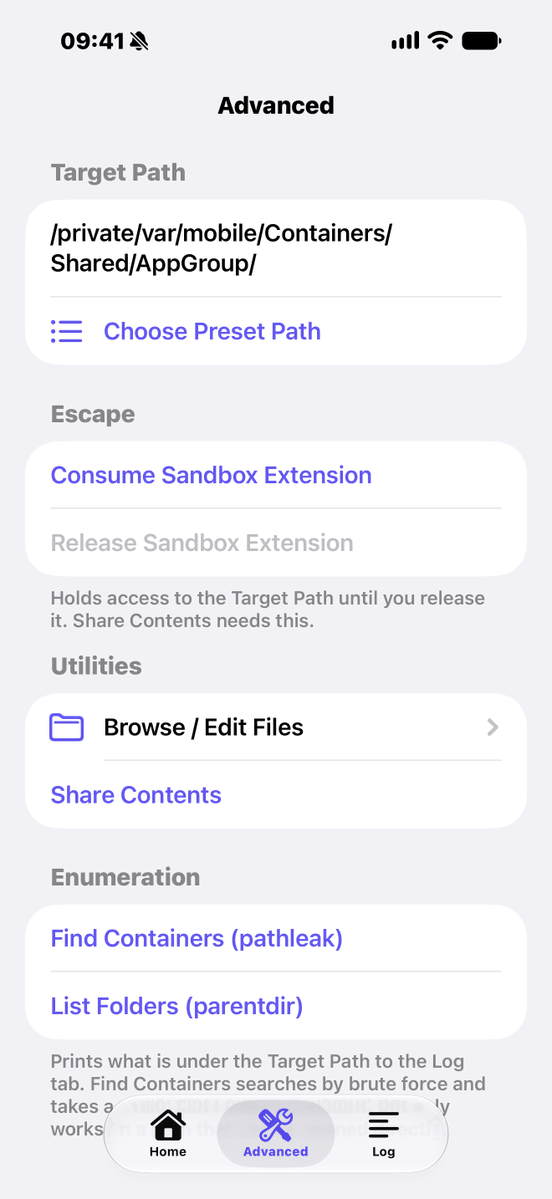
[Release] Regitela v1.0.0 is out 🎉
No jailbreak needed on iOS 27:
- Toggle Supervised Mode, no erase
- Switch Japanese/Korean models to the US region (LL/A)
Built on worse_query.
⚠️ Install with Impactor. Sideloadly doesn't work.
https://t.co/rUcpBpW8Hp
Erosion v0.3 is out now, replacing bad_query with worse_query and massively expanding the version support.
https://t.co/ahrDqBaEiH
Thx to @forcequitOS and @0xjohnny for the new sandbox escape!!
so this is what I've been doing.
after a bit longer, and some more PRs, I'll be back to PureDarwin!
this is @reactos arm32 on a Lumia 1520 bare-metal.
HD2 should be next, hopefully.
I bought a cooler for my 11700K & 8700, so hopefully i915 fixes.
Here's 4 steps to run an uncensored AI on your own GPU for $0:
I run a local abliterated Gemma 4 for anything I don't want leaving my machine
By the end, you'll know how to:
- run a model which has no refuses
- plug it into Claude Code
- do it all for $0, no API key, no account
So, let's go step by step:
1. Install Ollama
curl -fsSL https://t.co/Xqcu5R7xOu | sh
you want a recent version, older builds don't speak the Anthropic API and don't support Gemma 4
2. Pull the model
ollama pull igorls/gemma-4-12B-it-heretic-GGUF
the biggest mistake people make here is grabbing a random "uncensored" tag with no quality numbers
this one is abliterated with Heretic. refusals went 99/100 → 0/100 at a KL divergence of 0.028 from the original, so you keep almost all of the base model's capability
one thing: it's still Google's Gemma license underneath, fine for personal use, but read the terms before you build a product on it
3. Turn off thinking (the part every other guide skips)
Gemma 4 is a hybrid thinking model and the abliteration targets non-thinking mode
leave thinking on and the reasoning block eats your token budget and the answer gets cut off
ollama run igorls/gemma-4-12B-it-heretic-GGUF
/set nothink
if you're calling the API instead, add "think": false to the request
4. Plug it into Claude Code (OPTIONAL)
ollama launch claude --model igorls/gemma-4-12B-it-heretic-GGUF
or manually:
export ANTHROPIC_BASE_URL=http://localhost:11434
export ANTHROPIC_AUTH_TOKEN=ollama
claude --model igorls/gemma-4-12B-it-heretic-GGUF
two gotchas:
- bump the context first. Ollama defaults to 4k and Claude Code's system prompt alone is bigger than that, so the model never sees its tool instructions. restart the server with OLLAMA_CONTEXT_LENGTH=32768 ollama serve (setting it in your shell does nothing if Ollama is already running as a service). this needs more VRAM than the 8GB below
- Gemma 4 tool calling is still rough, you should expect some failed edits, imo for serious agentic work use qwen3.5 or glm-4.7-flash instead
What you need:
- 8-12GB VRAM for Q4 (12B)
- ~8GB of disk for Q4, ~13GB for Q8
- more of both if you want a big context
honest take:
- "abliterated" means refusals removed, not quality added. it's still a 12B
- fewer refusals ≠ smarter. for real coding work I still use cloud models
- you own the weights, your prompts never leave the box. that's the actual win
*IMPORTANT: don't use it for anything illegal or harmful. that's on you, not the model
now i'm collecting a list of every uncensored model i'm adding to my local stack and which tasks each one replaces for me
also planning a big "Uncensored 101" article, still figuring out all the angles
save it so you don't lose it