Automating workflows is probably an overused term right now. It’s still the best one for what most companies want.
In a company with a lot of employees, some work is bound to be inefficient (even in mine). The technology is usually the easier part. The harder and messier part is adoption - giving the person living in a spreadsheet all day the time, training and reason to change their processes.
That’s the gap leadership tends to underestimate. It’s never as easy as the people at the top want to assume.
Everyone wants AI right now. The first thing it needs is permissioned access to the right data.
If your data is spread across systems and the only way to see it is to pull a report and work through it by hand, there isn’t much an agent can do with it. You can’t automate decisions on data AI can’t reach.
That’s why we put an MCP server in front of DataConsole and built agents on top of it. They automate workflows and run decision intelligence on your own data.
It’s also why data marts matter more than they used to. Getting your data organized and reachable is where most of these projects actually start.
We’ll be demoing DataConsole, along with our new customer portal, at ELFA in Palm Desert October 25 to 27. If you’re going, let’s talk.
Think about this: The worst AI you will ever use is the AI you use today.
Every couple of months something new comes out in my world - today it’s mostly with AI but whether it’s a new frontier model, new framework, language, or a new cloud system - it’s always evolving. We adapt - learn it, build it into how we work, makes us less efficient for a minute while we learn it before we gain expert competency to get more efficient with it and capable of deploying it to our clients. Then two months later it happens again, rinse and repeat.
That’s why I’m focused on the next few months, not an entire 2027 wish list. We have our longer term goals and plans, but today 1-year is what 5-years used to be.
Finding the shiny new thing is easy. Having the discipline to ask whether you actually need it and whether it is important right now is the hard part.
Our team is spread out across the country (and world), so getting everyone in one room takes some planning.
We used to do our big in-person event at the end of the year, but too many people travel then. So we moved it to the summer. Plus a summer in Chicago, unbeatable in my opinion.
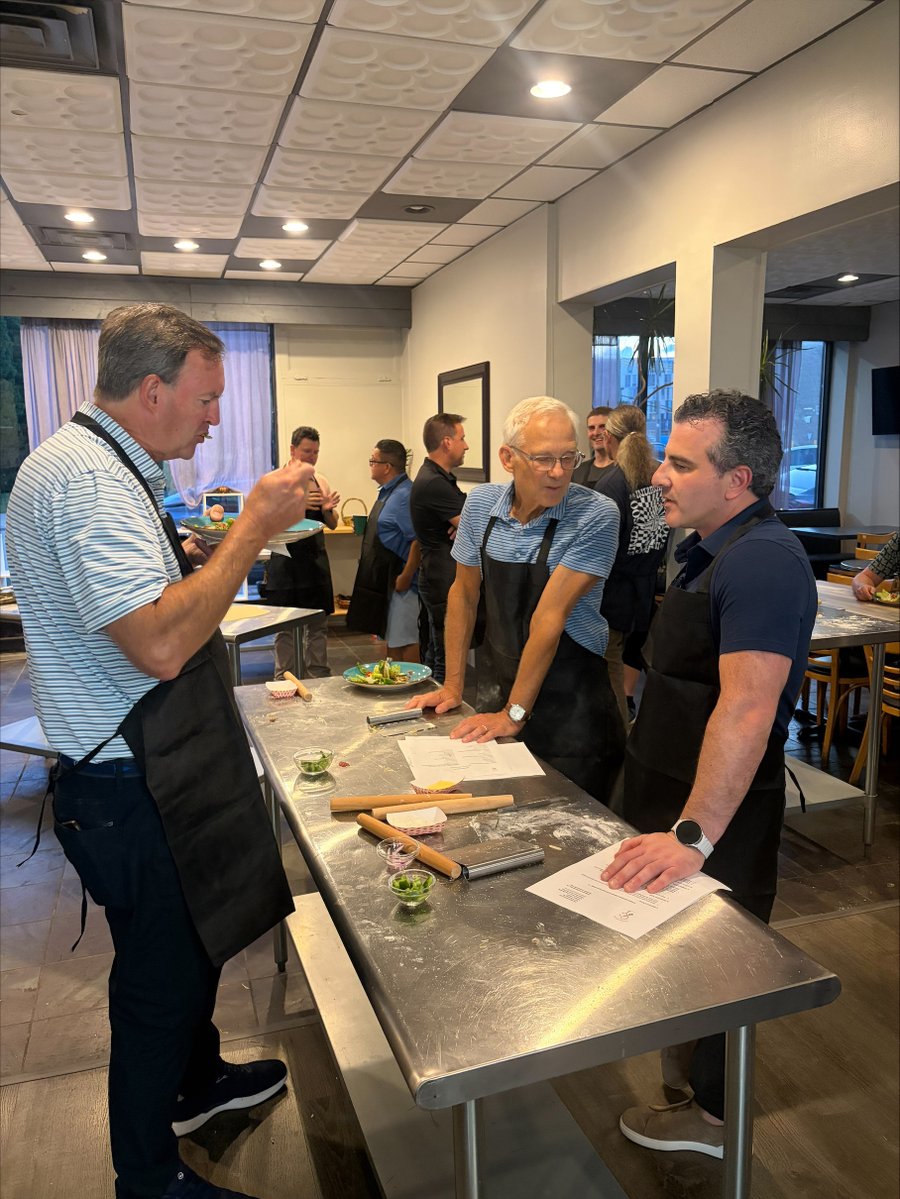
This year we had people come in from about ten different states for a pizza making class in Chicago with Cooking with Cass. She just opened her business and we were her very first event. She was wonderful.
Her place is right by Wrigley, so afterward I walked everyone a block over to Murphy's Bleachers. The Cubs were on the road, unfortunately, but as a Cubs fan I wasn't going to pass up a little after party at Murphy’s.
Thanks to everyone who traveled in, and to Cass and team for a great night.
A year-old system in software development is a hundred releases behind.
And oftentimes, companies don't realize how close they are to that line until something new comes out and they can't use it.
The gap between a system that can adopt new technology and one that can't doesn't happen overnight.
There's a specific point where that becomes a real problem, and by the time it shows up, the options for fixing it have already narrowed considerably.
If you give an AI the same credit application twice, should you have to wonder whether it will reach the same decision?
That question shapes how we’re building CreditMind.
It’s tempting to put an applicant’s financials, credit history, and supporting documents into Claude or another LLM, with appropriate security and privacy controls in place, provide a skill file outlining your underwriting policy, and ask it to reach a conclusion.
But written instructions leave room for interpretation, even when you explicitly tell the model to follow them exactly. Tighter instructions help, but they don’t turn an LLM into a deterministic rules engine. The same policy can still be applied differently from one application to the next. It’s also generally faster and less expensive to execute those rules in code than to have an LLM work through the same policy on every application.
That’s why we still write conditional rules. The familiar “if this, then that” logic of traditional software.
If a required document is missing, request it. If an application falls outside an approved threshold, route it for review. If an exception requires approval, enforce that approval.
With the same inputs and the same version of the rules, the logic produces the same result. We can test it, track changes, and show which conditions drove the outcome.
We use AI to help build those rules. It can help translate underwriting policies into proposed logic, which engineers and credit leaders then validate and approve. Once approved, the rules run the decisioning.
AI can also help interpret documents, organize information, and flag concerns. But those inputs need validation too. A consistently applied rule is still wrong if it’s working from an incorrectly extracted number.
Some applications will require judgment. Those should go to someone with the authority to make the call and document why.
Three years later, when someone asks why an application received a particular outcome, we want to be able to show the inputs, the rules in effect, and any approved exception.
For me, that’s a big part of building AI into lending responsibly. Use it where it helps, and be deliberate about which decisions you allow it to make.
How are you deciding where to use AI judgment and where to keep fixed rules?
Reports were supposed to make my job easier. They can.
But honestly, a hundred reports just means a thousand things I (or someone) now has to go deal with.
As a business leader, I've got hundreds of reports - both dashboards and emailed reports, just like many of you.
But they require me taking action - I have to analyze them, work out what they're telling me, then go do something about it. In a way, reporting is still very necessary because it means you’ve got data organized and have a lot of thought to what is important. However, reports alone are now table stakes.
The actions you need to take is what you should be thinking about automating with AI. Imagine if your agents are reading the reports, doing the analysis, taking the necessary actions, and then only notifying you when escalation is required.
We've built that and embedded it into Sparkflow and DataConsole and can do the same for you - time to get your AI agents doing the work and start being proactive with your data instead of reactive.
We can get you there and faster.
When I started doing interviews 20+ years ago, I remember having a mindset that I had to sell candidates on why they should work here, instead of the opposite - them selling me.
Jon Morris changed that for me 10+ years ago.
He told me that when he did interviews, he was purposefully telling them how it is, including the ugly truth - even if it could scare them. The job is going to be very demanding. There are going to be long hours, weekends sometimes, and some days you're really going to hate it.
Some days you're really going to love it, and you're going to learn a lot along the way.
I thought that was great advice and adopted a lot of it.
A few people have passed after hearing it, and I'd rather that happen in the interview than in month three. The demanding part isn't a figure of speech - mission critical systems we build for clients require mission critical responses, which sometimes means somebody gets called on a Saturday.
The ones who say yes anyway tend to stick.
To me those long hours are part of the fun - it means the systems we're working on are widely used and actually matter. Beats the alternative of working on things that don't.
Traditional reports look useful on the surface, and that's exactly the problem.
You still have to read them, interpret them, and decide what matters before anything really happens.
The better model puts an agentic workflow on top of the data instead. Agents are continuously reviewing the information, running the analysis, and taking action on it.
What you get back might just be an exception report for the ten percent it couldn't handle on its own. This is what we've built into both Sparkflow and DataConsole.