@AliciaCurth Love this! Great paper+post and awesome work. Heads up, I think the link in this tweet is down. I'm assuming the link is to "Random Forests and Adaptive Nearest Neighbors" by Lin and Jeon in JASA 2006?
@stephenpfohl 100% this is an absolute game changer. I’ve also just taken a figure I liked from the internet and asked ChatGPT to write the code needed to reproduce the figure and it’s not *perfect* but it’s pretty darn good.
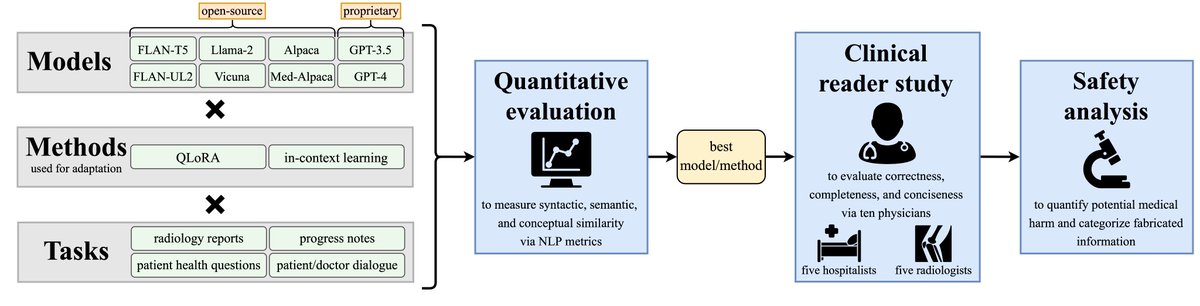
Our clinical #NLP work just published in @NatureMedicine! We present a framework to adapt & evaluate #LLMs for summarization. Physicians 🩺 prefer #LLM summaries to those of #medical experts❗
Big step to reduce documentation 📚 and focus more on personalized care 🙌
A 🧵
Are #LLMs ready for deployment into the clinic? How can we tell if they are vs. are not? @jasonafries does a great job laying out the current state of affairs for evaluating medical LLMs and how our recent work, MedAlign (https://t.co/c1Xc8hbl3s), fits into the bigger picture.
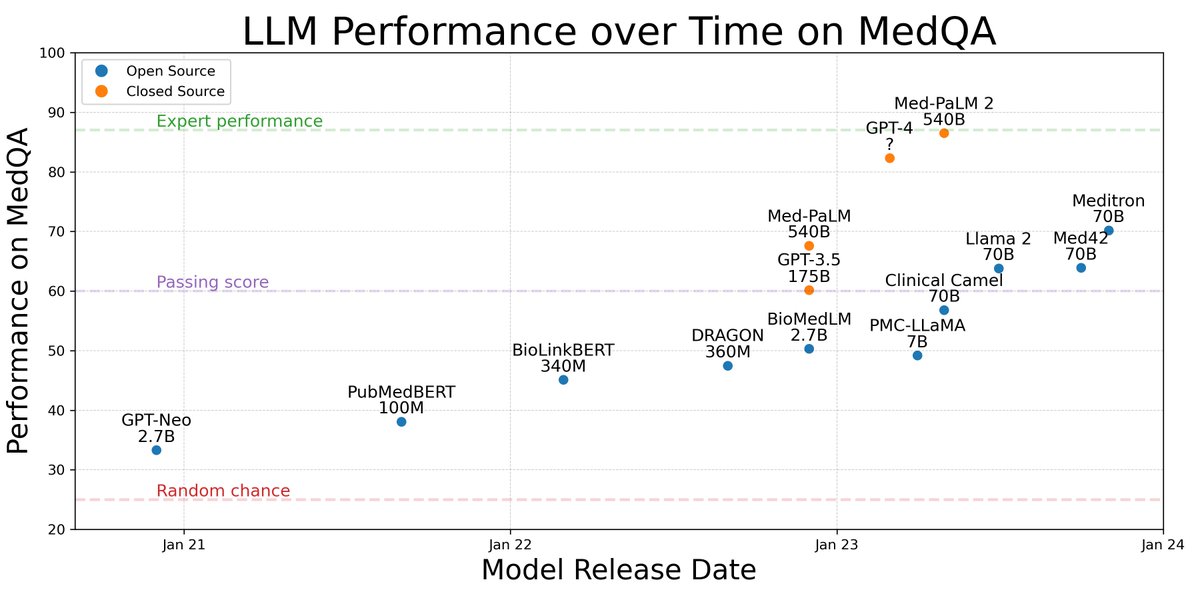
LLMs have made impressive progress on medical benchmarks like MedQA since 2021. Both open and closed medical LLMs have focused a lot on MedQA performance, but this has a number of problems when we think about deploying LLMs in hospitals. /1
Super excited to present our work on MedAlign @RealAAAI#AAAI24 in the AI for Social Impact Track. Happening now in Room 217, come check out our work and the other great projects being presented if you're attending
Excited to be in Vancouver 🇨🇦 for #AAAI24 with @_scott_fleming_ to present:
"MedAlign: A Clinician-Generated Benchmark Dataset for Instruction Following with Electronic Medical Records"
If you are interested in healthcare LLMs and preference alignment, checkout our talk and poster today (2/22)
🎤 Oral (presented by @_scott_fleming_): Thursday 3:45PM Room 217
🖼️ Poster Session: Thursday 7-9PM West Exhibit Hall
Website: https://t.co/AUUfLxxpwK
Paper: https://t.co/czKwuNsHoG
Lots of hype around #LLMs in healthcare. What do clinicians really want from an #LLM? We asked them! Introducing #MedAlign, the first dataset of clinician-generated instructions + responses for EHRs 🏥🤖
📄Paper: https://t.co/Wp1z5AvWll
🌐Website: https://t.co/IvepkoIoLZ
Evaluating few-shot learning is standard w/ LLMs but not EHR foundation models... yet! We're excited to release #EHRSHOT a dataset of ~7k patients + a foundation model pretrained on 2.57M de-identified EHRs #NeurIPS2023
📄 https://t.co/CmkAGwPh99
🌐 https://t.co/UqTK88R9wj
Super excited to have led this work with my awesome collaborators!
Check out our poster #440 at #NeurIPS2023🗓️ on Thursday from 5-7pm CST to learn more.
📽️ Slides/Talk: https://t.co/egnpAGufZ6
🌐Website: https://t.co/BykqpbODdc
Michael is not only incredibly smart, talented, and hard working, but also just a genuinely good person who cares deeply about science, rigor, and other people’s wellbeing. Couldn’t recommend this opportunity highly enough!
I'm recruiting PhD students for my lab at Johns Hopkins!
Please apply if you're interested in reliable ML / causal inference for decision-making in healthcare. See my website (https://t.co/vg0mn6gY5r) for more info.
Deadline 12/15. Retweets welcome :)
https://t.co/COLkwSjPNg
Huge thanks to @SehjKashyap for highlighting our MedAlign work in this concise &!informative video: https://t.co/4akIj8BzDT Come find us at #ML4H@SymposiumML4H in New Orleans today (Dec 10) where we’ll be giving a ⚡️talk at 15:35 CT! (And Follow/Subscribe @SehjKashyap!)
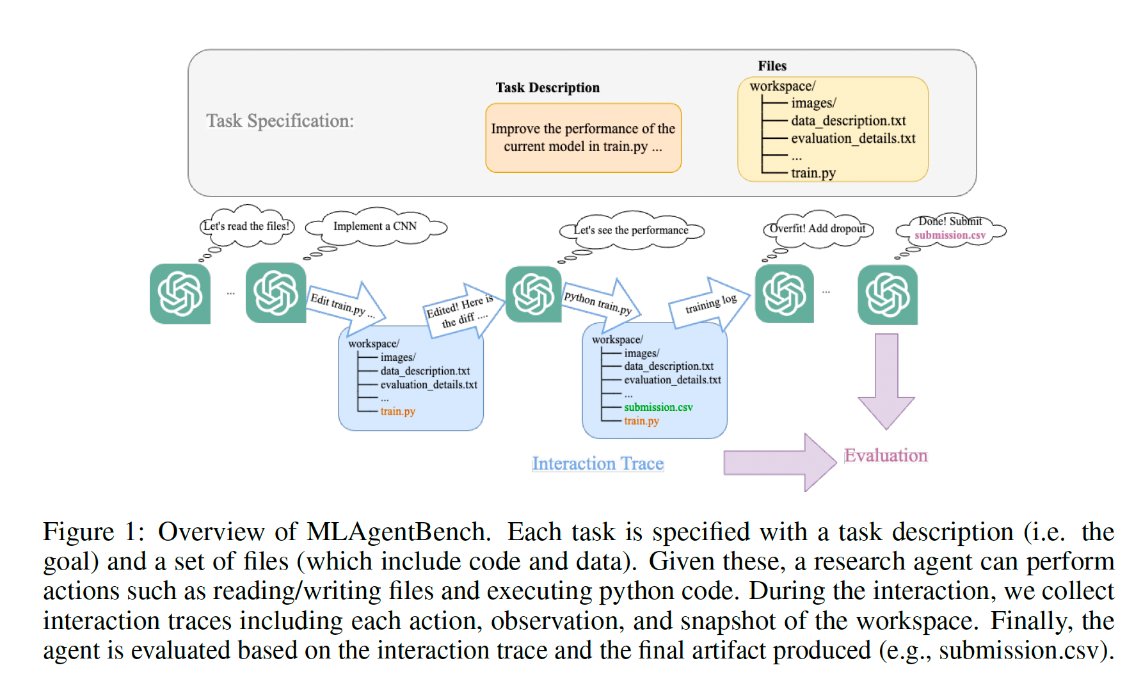
Can we build AI research agents to perform long-horizon tasks like ML engineering tasks e.g.Kaggle?
Introducing our new work MLAgentBench: Benchmarking Large Language Models as AI Research Agents!
On leaderboard Stable LM 3b matches LLaMA v2 7b performance on 42% of the size (beats on SciQ, MMLU), similar architecture, runs much faster.
Beats Falcon 7b, MPT-7b etc.
It beats all 3b models, including fine-tuned ones.
Smol, open LMs ftw 😍
https://t.co/UWHsd6JgCn
To kick off #OpenScienceWeek 🚀 and promote accessible, transparent, and reproducible medical ML, here are a few of my favorite #OpenAccess clinical language models: https://t.co/tFSnCGkFnW
@TodosInvestor Agreed, this is a cool idea! By “group data” do you mean eg using DRG’s? (Full disclosure: I work for https://t.co/QXCRZy9aKZ where we’re working hard to solve problems like this + we’re hiring!)
@TodosInvestor Re:recommendations for the best biomedical LLMs, check out this awesome HuggingFace space by the inimitable @katieelink! https://t.co/P1YI1fdFyg
To kick off #OpenScienceWeek 🚀 and promote accessible, transparent, and reproducible medical ML, here are a few of my favorite #OpenAccess clinical language models: https://t.co/tFSnCGkFnW
@TodosInvestor Thanks @TodosInvestor! Re:testing LLMs, common benchmark in the clinical space right now is the USMLE (see https://t.co/0n0N7pSep0 by Kung, @morgancheatham, et al). Also look at datasets in https://t.co/4x2oUj0rKs and https://t.co/bfwP0iQ4bt. And MedAlign! (once released)
So you've created an ✨awesome✨ biomedical ML model, and now you want to (responsibly) share it with the world
Here are some best practices for sharing medical models and demos ⤵️
@TodosInvestor @jasonafries Great question! If there are two drugs in the EHR but the interaction isn't recorded, I suspect GPT-4 could do a reasonable job of detecting a potential drug-drug interaction (assuming that this interaction is well-documented on the internet). But we didn't test that explicitly!
More meaningful evaluation of medical LLMs is a key challenge currently, so it's really exciting to see work like this 🤩
You can even contribute your ideas for tasks involving electronic health records (link on their website)