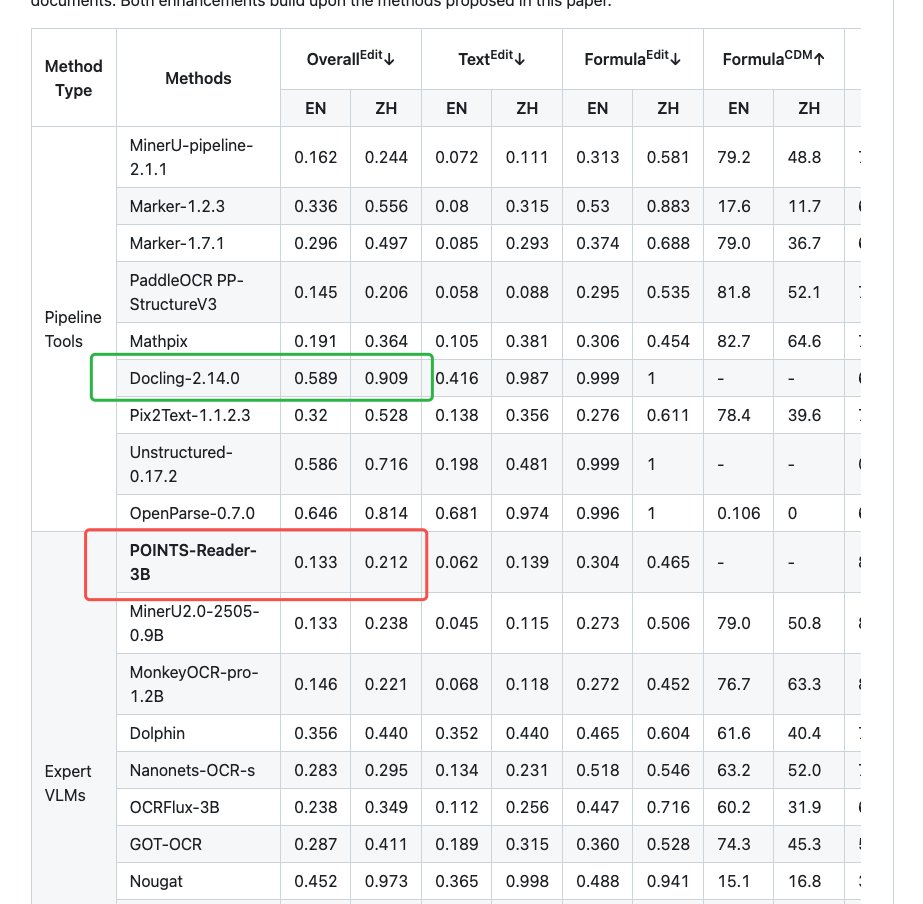
Many thanks for sharing! 👏👏 POINTS-Reader is a powerful end-to-end document OCR model with high throughput, making it well-suited for large-scale document extraction. The live demo is online, supported by @prithiv_003 , — please give it a try!
https://t.co/nbe57EPXC1
4B OCR with Apache-2.0 license outperforming Mistral OCR 🔥
Tencent released Points-Reader, it's a new model firstly trained on Qwen2.5VL annotations and then self-trained on real data
in many benchmarks, it performs better than Qwen2.5VL and MistralOCR!
@NigelHiggs7@mervenoyann We have not specifically compared POINTS-Reader with it, but we have achieved state-of-the-art performance among existing document OCR models. For more details, please visit our GitHub page.
https://t.co/5d9FFtxtgv
@mervenoyann Thank you for sharing, Merve! The performance metrics for POINTS-Reader in the paper are not the latest. We have continued to enhance its performance after our submission to EMNLP, and the latest results, which are significantly higher, are presented in the table below.👇
@casper_hansen_@mervenoyann The performance is comparable, but the throughput is significantly higher, making it suitable for large-scale extraction scenarios.
Introducing our new vision-language model for end-to-end document conversion! 🔥🔥🔥
It delivers state-of-the-art performance on OmniDocBench with blazing-fast throughput.
🚀🚀🚀
Read the paper: https://t.co/zFqHDQLpIZ
@WenhuChen@jbohnslav What do you think is the key to achieving o1-like performance in the vision-language domain? At this stage, do we need to introduce RL?
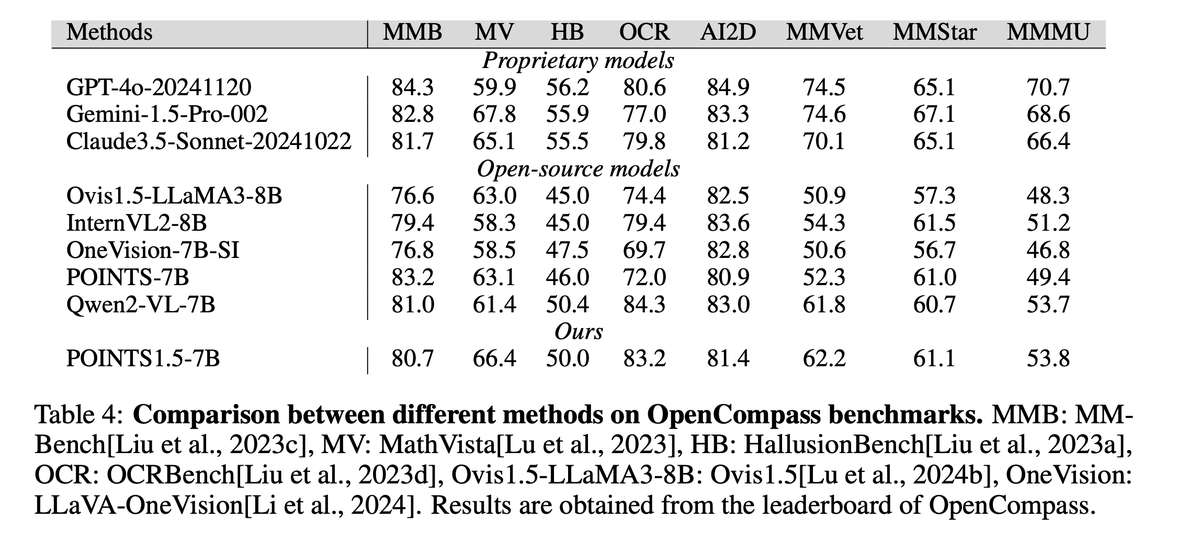
Happy to see that POINTS1.5 ranks first on this leaderboard among models with fewer than 10 billion parameters🚀🚀🚀
Paper: https://t.co/1IziahPLTR
Github: https://t.co/k7qE3rgkUi
Model: https://t.co/0xOxdx6xFS
OpenCompass has established a leaderboard to evaluate complex reasoning capability of LMMs, consisting of four advanced multi-modal math reasoning benchmarks. Currently, Gemini-2.0-Flash took the 1st place. DM me to suggest more benchmarks and models to this LB.
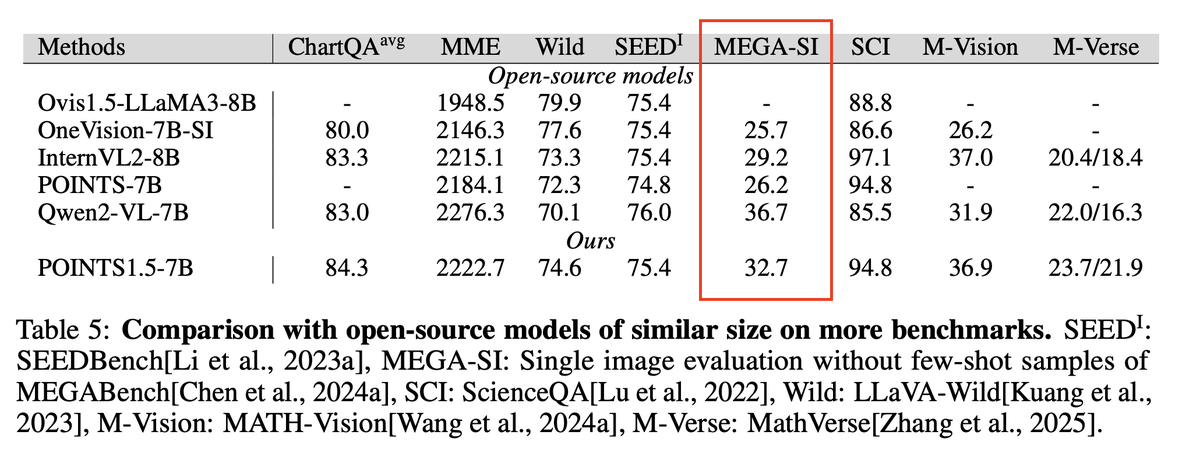
Great work to build VLMs that are more geared towards real-world application. Also glad to see that they evaluated on our MEGA-Bench.
https://t.co/NFh0RHboCn
Thanks for sharing. We will continue to develop our WePOINTS series of large multimodal models, bringing more high-quality work to the community.
Paper: https://t.co/VSXQEPrvs2
Github: https://t.co/k7qE3rgkUi
POINTS1.5🔥 new vision language model released by Wechat AI @Weixin_WeChat
Model: https://t.co/iZ7INhngME
Paper: https://t.co/asrGPdIurB
✨ Dynamic resolution with NaViT encoder, no tiling required
✨ English & Chinese
✨ Smarter visual tuning with rigorous dataset filtering
✨ Trained on <4B tokens, yet POINTS1.5-7B leads OpenCompass (<10B params)
A new model from @Weixin_WeChat The largest all-in-one messenger app from @TencentGlobal
- VL, ranking top on OpenCompass Vision multimodal leaderboard for <10B models
- 8B, fine-tuned on @Alibaba_Qwen 2.5 7B chat model
- Dynamic high resolution with naViT-style vision encoder