Had a great term working on this project. I remember the first model trying and failing over and over, and now this new model makes it look so easy. It's time to bring this success to hardware next!
Update on our robot learning project with @aboraatakan at @uwwatai.
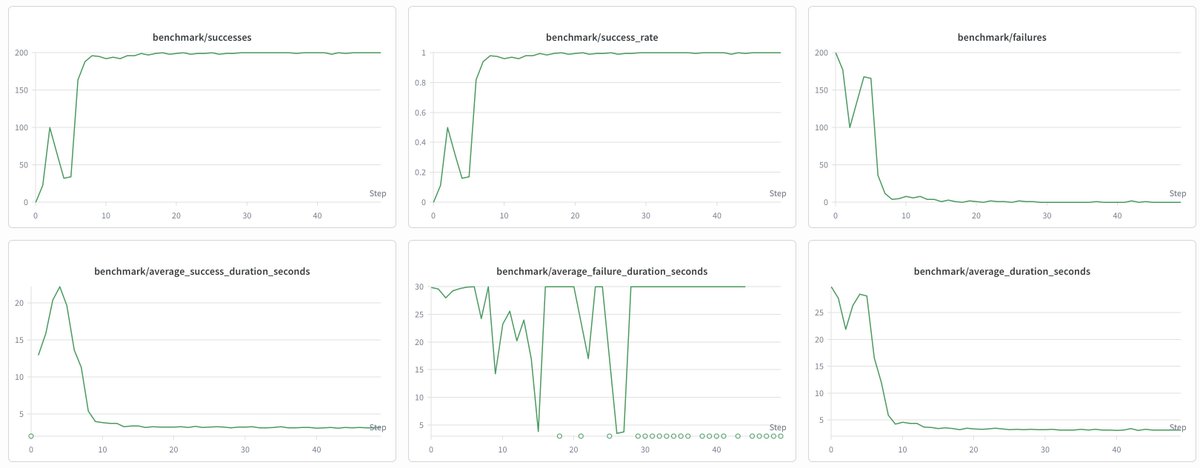
We went from ~30% to 99.8% success on our pick-and-place task by updating our policy from a DINO ViT + transformer policy to a CNN + MLP. Our old model was memorizing the training data and transferring poorly to closed-loop rollouts, so we went the other way and made the model smaller.
The attached video is the CNN + MLP policy running in sim on our async inference stack. We demoed it live for a few hours: 4 failures over 2000+ randomized scenes. This experience has been useful to confirm our stack's correctness. We are now ready to move to hardware!
Next: real hardware, diffusion policy, open-weight fine-tunes, and RL.
Reach out if you're interested in collaborating, and stay tuned.
Imagine teaching robots new tasks just by showing them videos.
@aboraatakan and I started this as a research idea, then built it into a @uwwatai research group with an amazing @UWaterloo team.
We now have our first MuJoCo sim stack for data collection, rollouts, debugging, training, async real-time inference, and a policy at ~30% success.
Next: bigger models, RL, and post-training recipes.
Huge thanks to @BerkayAntmen and @coolboi95 for the mentorship.
Reach out if you’re interested in collaborating, and stay tuned!