The most dangerous lie in business right now:
“AI can’t replace real expertise.”
It already has. Quietly. Everywhere.
A solo founder with Claude and Cursor is outshipping 15-person agencies. A kid with no degree is building what MBAs couldn’t conceptualize. Context windows now hold more institutional knowledge than most employees accumulate in a decade.
But here’s what people miss, this isn’t the Age of AI. It’s the Age of Production.
The bottleneck was never ideas. It was execution.
AI just removed that bottleneck permanently.
The new hierarchy:
Old world - what you know
Current world - what you can prompt
Next world - what you choose to build and for whom
Credentials got you access. Now taste, speed, and conviction get you everything.
The people panicking are the ones who sold knowledge.
The people thriving are the ones who always had vision but lacked the army to execute it.
Now every builder has an army.
The difference between those who have everything and those with nothing in this world is heartbreaking 💔
Source: ferdychildrenfoundation1 on IG / Writer: Ian
A listener asks where to find funding for an AI education project with no clear business model. Dr. Alex Wissner-Gross says funding isn't the bottleneck anymore.
Elon Musk explains why charging your EV to 100% on a road trip is a mistake:
On a road trip, your instinct is to fill the battery all the way up.
That's how you'd treat a gas tank.
But a battery doesn't work like a gas tank.
Charge to about 80%. Drive it down to 10% or less. Repeat.
This is just for long trips, when you want to spend as little time at the charger as possible.
Elon: "Getting from 80 to 100, it takes about as much time as getting from 0 to 80."
The reason is what's happening inside the battery.
Lithium ions travel from one side to the other, looking for a place to settle.
Think of them as cars hunting for a parking spot.
When the lot is empty, they zip right in.
As it fills up, they have to circle around, like at a packed mall.
So the closer the battery gets to full, the slower it charges.
The last few spots take the longest to find.
Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
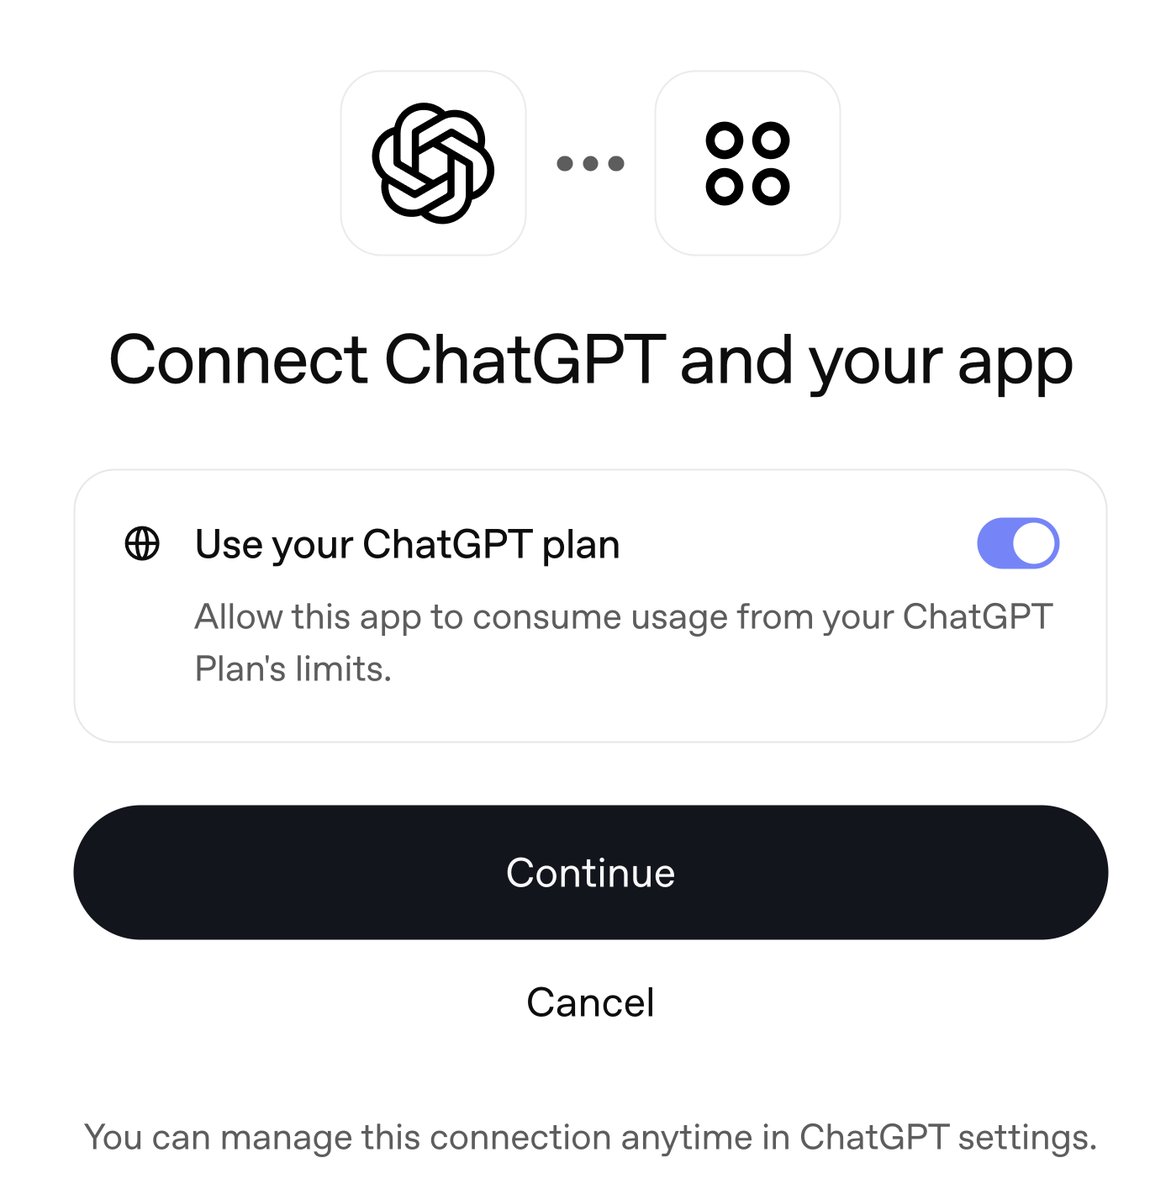
Apart from the launches where OpenAI is catching up to other companies, the most valuable DevDay news is actually this: the ChatGPT Plus / Pro plan you already pay for can now 𝗽𝗼𝘄𝗲𝗿 𝘁𝗵𝗲 𝗔𝗜 𝗶𝗻𝘀𝗶𝗱𝗲 𝗗𝗲𝘃𝗶𝗻, 𝗪𝗮𝗿𝗽, 𝗔𝗺𝗽 𝗮𝗻𝗱 𝗡𝗼𝘁𝗶𝗼𝗻.
The way in is the new "Sign in with ChatGPT" button in these apps. It looks a lot like "Sign in with Google," except you get 𝗼𝗻𝗲 𝗲𝘅𝘁𝗿𝗮 𝘀𝘄𝗶𝘁𝗰𝗵 when you sign in. Turn it on and the AI in that app runs on your ChatGPT usage.
Count them up and that's one subscription you can spend in over a dozen tools. The open-source OpenClaw, OpenCode, Pi and T3 Code all work too. Just sign in with ChatGPT.
Apps that can use your plan today:
Amp Code, Conductor, Dactyl, Devin, Hermes Agent, Hyperagent, Kilo Code, Notion, Vercel, Vorflux, Warp. Lovable is coming soon.
Airtable, Canva, GitLab, HubSpot and Supabase only support sign-in. They can't use your plan.
Before you connect one:
→ It draws from the 𝘀𝗮𝗺𝗲 𝘂𝘀𝗮𝗴𝗲 𝗮𝘀 𝗖𝗼𝗱𝗲𝘅. Connecting more apps doesn't add any, and some apps charge their own fees.
→ In ChatGPT Settings > Usage > App limits, you can give each app a weekly cap as a percentage of your total, so one tool can't burn through your week of Codex.
→ Apps can't access your ChatGPT chats or memories.
My guess is a lot of AI tools will end up running on your ChatGPT subscription, and the people building them won't have to front the model bill.
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.
🎉 Introducing 𝙾𝚙𝚎𝚗𝙼𝚞𝚜𝚎
An open source, self-hostable personal assistant that works with any agent harness.
Includes:
- Computer use: browser, terminal & files
- Connectors for your personal apps
- Ideas, goals & progress tracking
- Built for Mobile and Web
Repo → https://t.co/wfVccqlpru
Powered by @CopilotKit and AG-UI.
Clone this template and customize it however you want.
One more thing: we’re increasing five-hour usage limits on Pro, Max, and Team plans. We’re also providing subscription users a rate limit reset, which you can save and use whenever you choose.
Introducing Claude Opus 5.5, the first model in our new Claude 5.5 family.
It performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.
I already have 3 x 200$ old plans. But I am running out of all for the team. We are almost on the last 10% usage left with no reset usage. Upgraded couple of Code Max accounts instead but looking to buy more 200$/plan once it opens up again. Wanted to know if upgrading old 20$/m plan to 100$/m will help getting to 20x plan availability since have some old accounts with 20$/m plans. Though accounts were not being used much.
Jev might genuinely be an “Internet moment” for AI.
TypeSafe reports up to 193x faster and 444x cheaper performance in tests with Claude Fable 5.1 and GPT-6 Astra.
@0xCodila just wrote a great 10-page article explaining what Jev is, how to use it, and where its 100x advantage comes from.
Here are the 10 steps:
1 → LLMs create. Agents act. Jev decides the next move.
2 → Turn agent forks into three primitives: Choice, Score and probability.
3 → Build with OpenAI, Anthropic or xAI first, then swap Jev in without rebuilding the graph.
4 → Start with shared state, parallel decisions, risk thresholds and an execution queue.
5 → Batch decisions instead of making them sequentially. In one test, 13 questions were 10x faster and 12.2x cheaper.
6 → Put Jev at bounded forks: agent, model, tool, browser action or human escalation.
7 → Benchmark the whole loop, not just individual model calls.
8 → Rank wide, read narrow: shortlist first, then spend compute on what matters.
9 → Reuse the same system: State → Questions → Action → Verify.
10 → Keep Jev out of math, writing and irreversible execution. Code computes, LLMs create, Jev decides.
The result:
A slow, expensive agent loop becomes a much faster decision system that can route, score and escalate in milliseconds.
Full breakdown below ↓