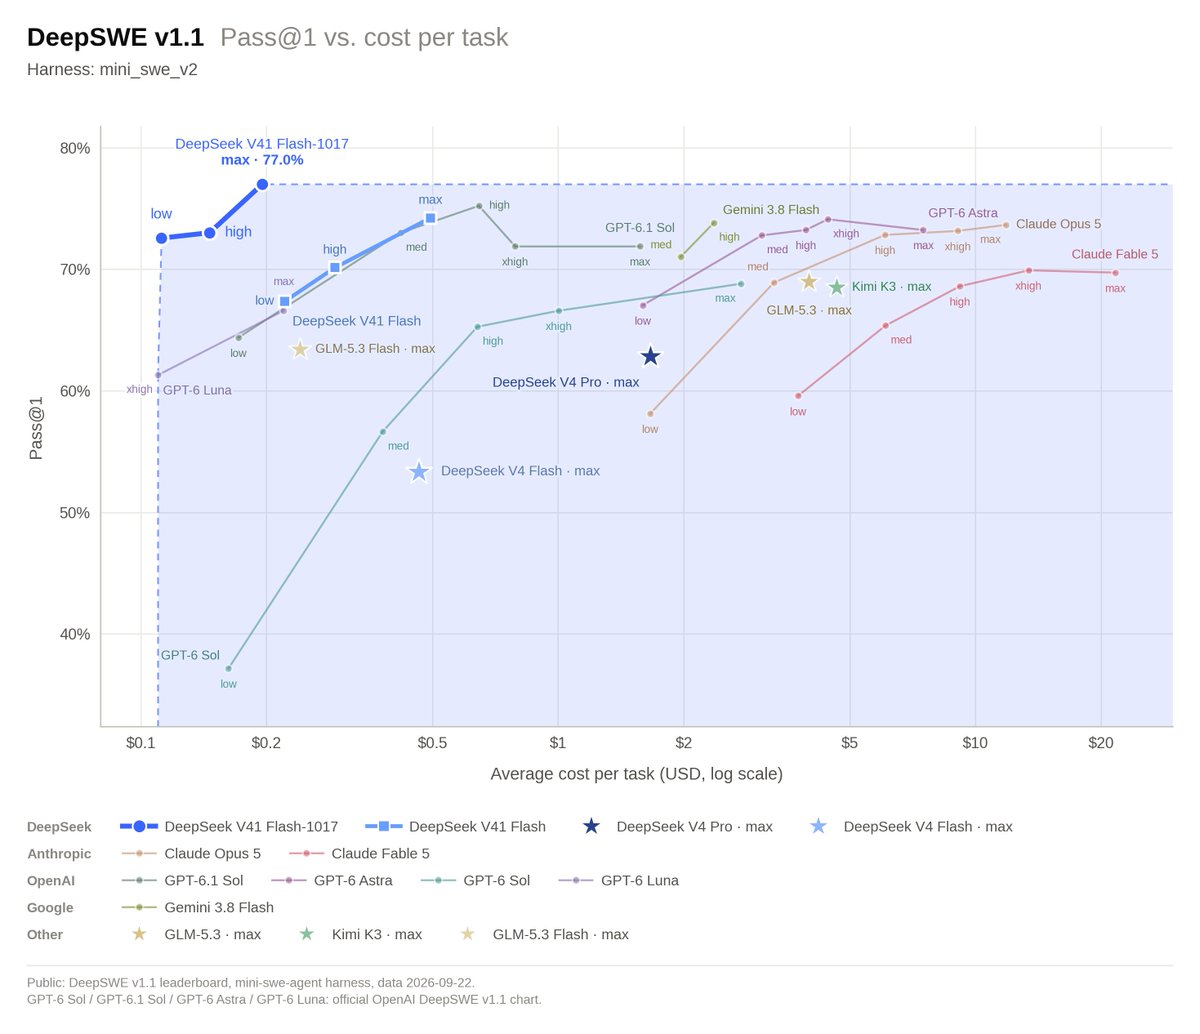
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
NVIDIA RTX Spark is here.
Build AI locally, bring your creative ideas to life, and take your favorite games along.
A new beginning for @Windows PCs starts today.
you don't need a 128GB MacBook for Qwen3.8-Flash-Next anymore
Strata runs the 125B model on a 12GB gaming GPU + 32GB RAM.
RTX 5070: 94 tok/s at Q2, 53 tok/s at IQ3_S
Q2 is a heavy quant, so check quality on your own tasks before you trust it. still wild. 25K stars on GitHub already