Just finished Close to Death by @AnthonyHorowitz. Brilliant mystery! But why didn’t police excavate the magnolia tree to verify Hawthorne’s theory about Wendy? Was leaving this unresolved deliberate? Would love to know!
1/ announcing our smallest, most efficient little model is here: muse ember 🔥
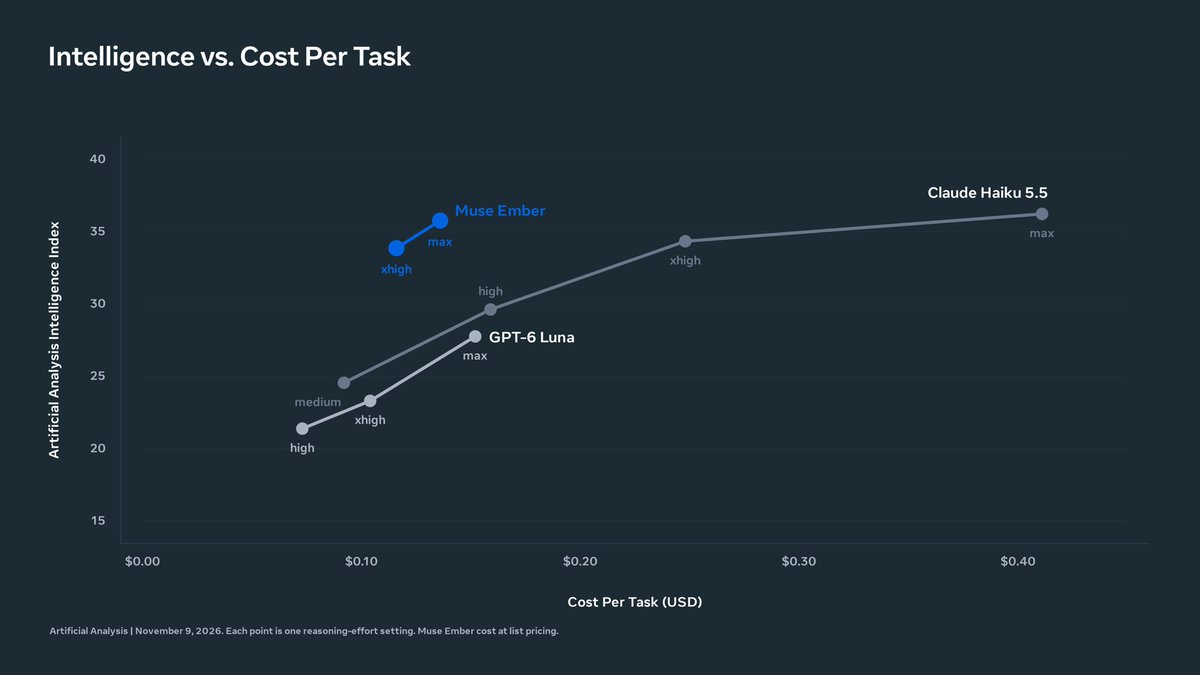
built for work that agents repeat all day, it gets you more intelligence per dollar than Haiku, Luna, and all other flash models at any reasoning setting and does it at a third of the cost or less!
today we released our smallest model yet: Muse Ember 🔥
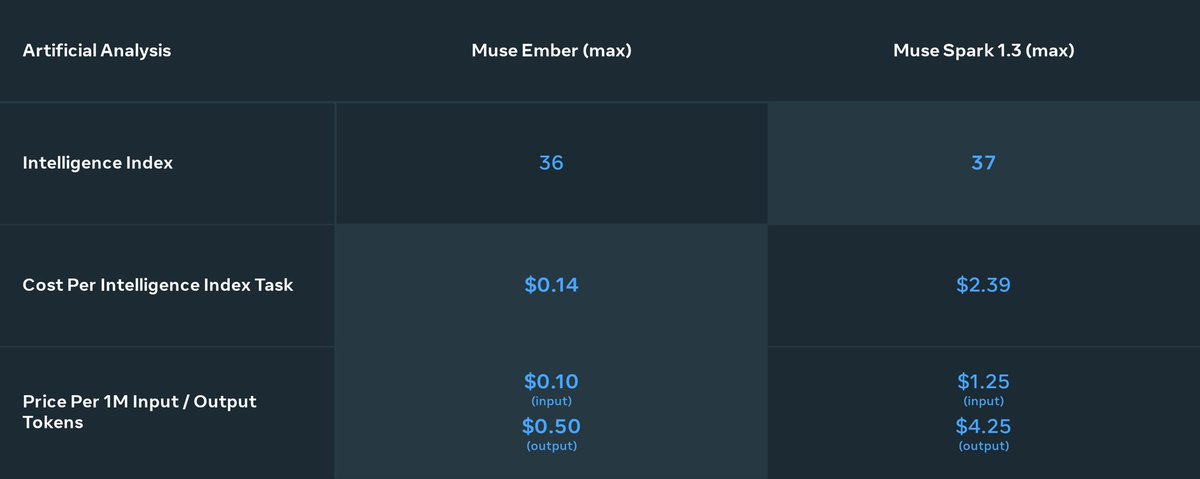
Muse Ember offers nearly Muse Spark 1.3 (max) intelligence at a 17x cheaper price point (per AA)
Muse Ember is the first model we’ve released trained using Muse Wonder Full
excited for y’all to try on API and muse code!
Releasing Muse Ember today -- our smallest model that delivers higher intelligence per dollar than others in its class. Built for token-heavy work that agents repeat all day: tool calls, coding subtasks, routing, extraction, and long document parsing. Available today on the Meta Model API and in Muse Code.
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio
We’re excited to introduce the Muse Wonder series with Muse Wonder and Muse Wonder Full, our most capable models yet. Both are frontier models, built to deliver state-of-the-art performance for personal and professional agentic tasks.
Muse Wonder is available today via the Meta Model API and Muse Code. Muse Wonder Full is available today for Muse Code subscribers. Muse Wonder will also soon power experiences in our personal agent product, Muse, rolling out first to subscribers.
🚨 MUSE ECOSYSTEM ALERT 🚨
today we are announcing Muse Gadgets!
this is an open-source ESP32 firmware and Linux SDK for anyone to make hardware that works with Muse
we are also releasing our own gadget—Muse Home Link—to enable your muse to work with your smart devices (TV, speakers, etc.)
1/ muse for small businesses 📊
we found lots of people using muse to run their small business. plumbing businesses, grocery stores, farms, restaurants, and shops.
today we're launching a bunch of connectors to make that easier!
We believe superintelligence will create significant new opportunities for all people and businesses. Meta already serves billions of people at scale and helps hundreds of millions of businesses reach customers. Today we are starting the next major pillar of our business, Meta Enterprise Platform, to help businesses use AI to grow and transform in new ways as well.
Today, we’re announcing Muse for Small Business. Muse, Meta’s new personal AI agent, is one of the most important products we've built for the era of personal superintelligence.
Now, we're expanding it with a collection of new skills and connectors inside Muse to help people run their businesses.
https://t.co/k6UbaoYy7L
Introducing DINOv3: a state-of-the-art computer vision model trained with self-supervised learning (SSL) that produces powerful, high-resolution image features. For the first time, a single frozen vision backbone outperforms specialized solutions on multiple long-standing dense prediction tasks.
Learn more about DINOv3 here: https://t.co/lQpKhJLTZQ
Introducing our first set of Llama 4 models!
We’ve been hard at work doing a complete re-design of the Llama series. I’m so excited to share it with the world today and mark another major milestone for the Llama herd as we release the *first* open source models in the Llama 4 collection 🦙. Here are some highlights:
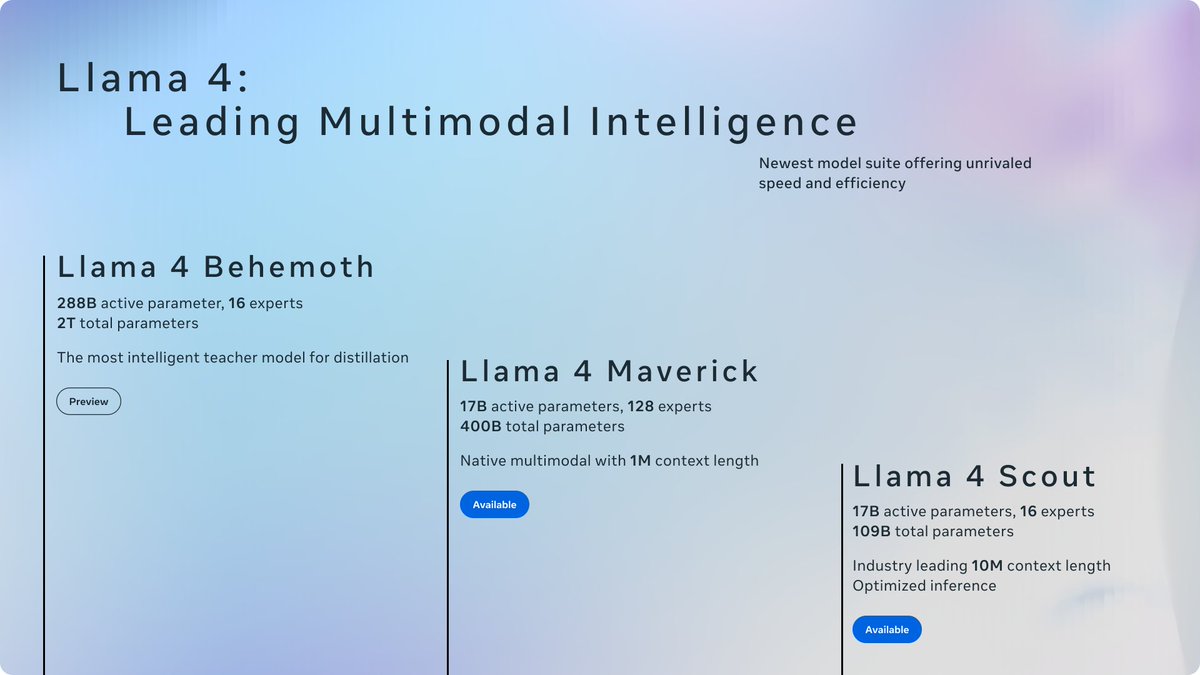
📌 The Llama series have been re-designed to use state of the art mixture-of-experts (MoE) architecture and natively trained with multimodality. We’re dropping Llama 4 Scout & Llama 4 Maverick, and previewing Llama 4 Behemoth.
📌 Llama 4 Scout is highest performing small model with 17B activated parameters with 16 experts. It’s crazy fast, natively multimodal, and very smart. It achieves an industry leading 10M+ token context window and can also run on a single GPU!
📌 Llama 4 Maverick is the best multimodal model in its class, beating GPT-4o and Gemini 2.0 Flash across a broad range of widely reported benchmarks, while achieving comparable results to the new DeepSeek v3 on reasoning and coding – at less than half the active parameters. It offers a best-in-class performance to cost ratio with an experimental chat version scoring ELO of 1417 on LMArena. It can also run on a single host!
📌 Previewing Llama 4 Behemoth, our most powerful model yet and among the world’s smartest LLMs. Llama 4 Behemoth outperforms GPT4.5, Claude Sonnet 3.7, and Gemini 2.0 Pro on several STEM benchmarks. Llama 4 Behemoth is still training, and we’re excited to share more details about it even while it’s still in flight.
A big thanks to all of our launch partners (full list in blog) for helping us bring Llama 4 to developers everywhere including @huggingface, @togethercompute, @SnowflakeDB, @ollama, @databricks and many others👏 This is just the start, we have more models coming and the team is really cooking – look out for Llama 4 Reasoning 😉
A few weeks ago, we celebrated Llama being downloaded over 1 billion times. Llama 4 demonstrates our long-term commitment to open source AI, the entire open source AI community, and our unwavering belief that open systems will produce the best small, mid-size and soon frontier models. Llama would be nothing without the global open source AI community & we are so ready to begin this next chapter with you. 🦙
Read more about the release here: https://t.co/7mbK3uggjO, and try it in our products today.
Today is the start of a new era of natively multimodal AI innovation.
Today, we’re introducing the first Llama 4 models: Llama 4 Scout and Llama 4 Maverick — our most advanced models yet and the best in their class for multimodality.
Llama 4 Scout
• 17B-active-parameter model with 16 experts.
• Industry-leading context window of 10M tokens.
• Outperforms Gemma 3, Gemini 2.0 Flash-Lite and Mistral 3.1 across a broad range of widely accepted benchmarks.
Llama 4 Maverick
• 17B-active-parameter model with 128 experts.
• Best-in-class image grounding with the ability to align user prompts with relevant visual concepts and anchor model responses to regions in the image.
• Outperforms GPT-4o and Gemini 2.0 Flash across a broad range of widely accepted benchmarks.
• Achieves comparable results to DeepSeek v3 on reasoning and coding — at half the active parameters.
• Unparalleled performance-to-cost ratio with a chat version scoring ELO of 1417 on LMArena.
These models are our best yet thanks to distillation from Llama 4 Behemoth, our most powerful model yet. Llama 4 Behemoth is still in training and is currently seeing results that outperform GPT-4.5, Claude Sonnet 3.7, and Gemini 2.0 Pro on STEM-focused benchmarks. We’re excited to share more details about it even while it’s still in flight.
Read more about the first Llama 4 models, including training and benchmarks ➡️ https://t.co/9G3QgVdCkB
Download Llama 4 ➡️ https://t.co/eVomRvEr0w
BEAST GAME EPISODE 3 IS OUT NOW!
To celebrate, I'm giving away $100,000 total to 10 random people who like and retweet this post!
Go watch it here: https://t.co/Yntf9E7FTN