Full-stack analytics leader turned entrepreneur
Co-Founder of Falcon Media - digital marketing agency
Running @quotefii - compare & save on auto insurance
Have been testing Grok 4.5 recently and it's quickly becoming my daily driver for code implementation.
Love the balance of speed and intelligence at the low cost. Have been using GPT 4.6 Sol xhigh for building the plan/orchestration, then handing off to Grok 4.5 for execution.
Once execution is completed, pass back to GPT 4.6 for a pass through to find any potential bugs and comment on the PR. Sometimes have to go through a few cycles of this, but it works really well all together.
Still playing around with the best workflow, but really enjoying this process for quickly implementing features.
@thsottiaux Woah, need to start cranking out some Sol ultra workflows before this afternoon.
Seriously tho thank you for the resets 🙌
So huge with testing the new models
@alliekmiller Being able to choose between steering and queueing is so huge.
Sometimes I need the model to receive additional context, but other times I'm fine waiting for the work to be completed. Great to have the option either way, super underrated
@elvissun@thsottiaux Yes please 🙏
this got me the first few times. if it's taking too long I'll change in future chats but don't want my workflow interrupted
@pashmerepat This is really helpful clarification, thank you!
For me personally, I've found using Sol medium is more equivalent to what I used 5.5 high/xhigh for, but better with the Sol bump. Now that I've adjusted, the usage amount is much more reasonable.
What all these new releases of AI models have reinforced in me is that it's not the tools that you use that matter. It's making sure you're getting done what needs to get done for your company to be successful.
Doesn't matter if you're not using the latest model or the most efficient workflow. You just need to be making progress on your goals.
Use tools that you enjoy and that actually make you productive. Don't need to be constantly chasing the next big thing.
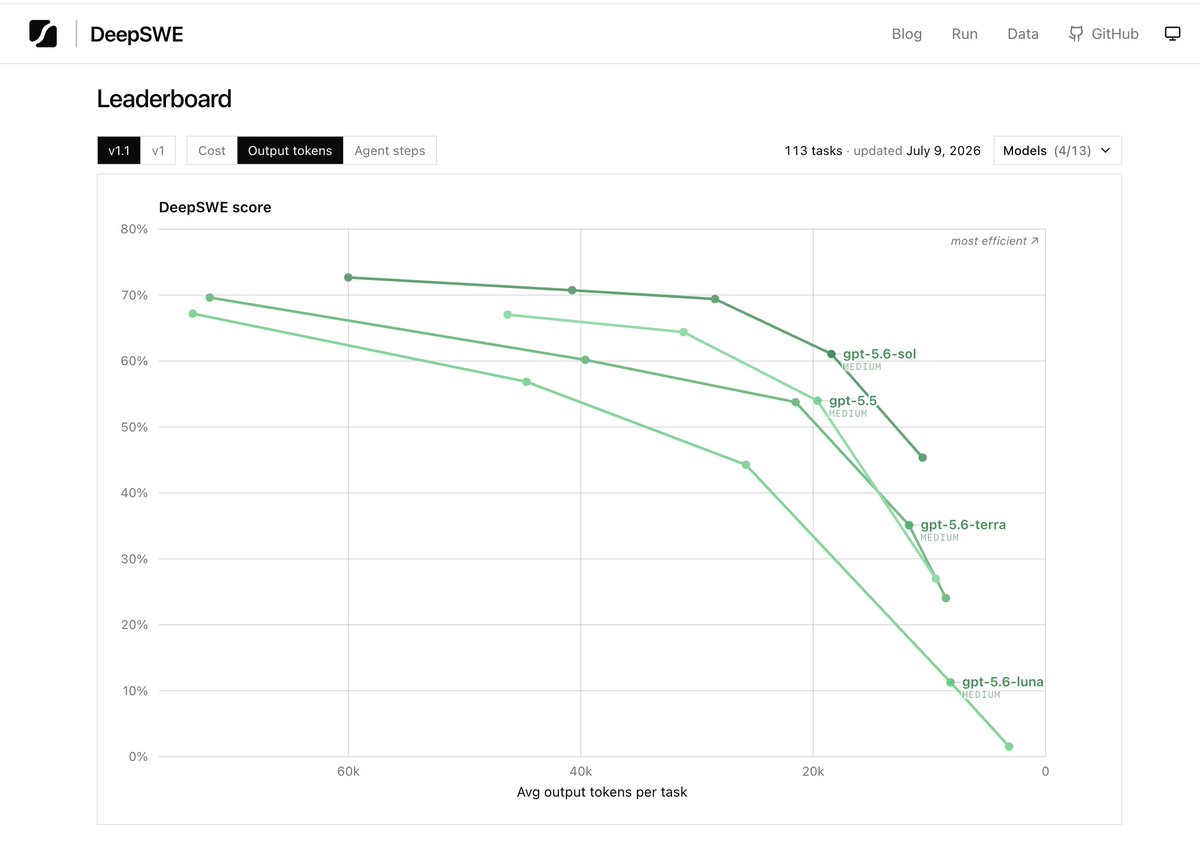
Yeah I get what you're saying. The 5.6 models are suppose to be more token efficient though. Sol uses less tokens for the same task in DeepSWE.
That's why cost is good to look at. Cost in theory balances the token output, steps, and cost per token to give you a price per task. But that doesn't seem to correlate with actual Codex usage when trying to complete similar tasks
@nicdunz Yup, came to the same conclusion. Neither are better than 5.5 unless on xhigh+ and then use way more usage. Sol medium has become my daily driver
@chuks_nwob@jonkomet Wouldn't that be the same issue for 5.5 though?
Running similar workflows through 5.5 vs 5.6. Just confused why 5.6 uses way more usage but on these charts shows less cost
In the exact same boat. Rarely hit the limit with 5.5 high/xhigh but hitting it now consistently with 5.6 sol. Terra/Luna don’t seem as good as 5.5 unless on xhigh or ultra and then I keep getting the thinking too much message.
Still like Sol high for orchestration/advising but switched back to 5.5 high for implementation
@SimonHoiberg imo Sol is a lot better for reasoning tasks, but man it uses up soooo much usage. Can't really use it as a daily driver, even on the $200/month plan. I like having Sol for orchestration/advising and 5.5 high for implementation. Feels like a good balance.