Digital Economy Strategist, Cybersecurity, Digital Transformation & e-Gov Senior Expert, EU Key Expert on PSC, NAC & Cap. Dev., Informatics Law, PDP, AI
✨ #OpenAI, Bilimsel Araştırmalara Özel Platformunu ("OpenAI #ScienceBlog") Duyurdu ve İlk Bulgusunu Yayımladı
✅ OpenAI, yapay zekanın #matematik, #fizik ve deneysel bilimlerdeki #hipotez geliştirme ile #teorem ispatlama süreçlerine katkısını belgelemek üzere resmî OpenAI Science Blog platformunu başlattığını duyurdu.
✅ Platformun ilk yayını kapsamında GPT-6 Astra modelinin yardımıyla parçacık fiziğindeki Standart Model'in kafes (lattice) üzerinde pertürbatif olmayan (nonperturbative) tanımına yönelik yeni bir matematiksel kurgu ve kanıt adımı paylaşıldı.
✅ Çalışma, zayıf kuvvet parçacıklarının kafes formülasyonlarında ortaya çıkan "çiftlenme" (doubling) sorununu aşmaya yönelik model destekli ispat yöntemlerini ortaya koyuyor.
➡️ https://t.co/SXgkSd3NvM
Alibaba has launched Qwen4 Max, gaining 9 points over Qwen3.8 Max on the Artificial Analysis Intelligence Index and landing 3 points behind Kimi K3.1 Pro at ~11% lower Cost per Task
Qwen4 Max, using xhigh reasoning effort, scores 43 on the Intelligence Index, 9 points ahead of Qwen3.8 Max (xhigh) and 3 points behind Kimi K3.1 Pro (max, 46)
Key takeaways:
➤ Qwen4 Max improves on every evaluation in the Index vs Qwen3.8 Max (xhigh, 34): HLE-Diamond +21 points (24% to 45%), AA-Omniscience +18 points, AutomationBench-AA +17 points, CritPt v2 +13 points, Terminal-Bench-Science +11 points, Terminal-Bench 4.0 +9 points, GDP.pdf +3 points, FrontierCode 2.0 +3 points and AA-Briefcase +82 Elo.
➤ Qwen4 Max costs $3.27 per Intelligence Index task, ~3x less than Qwen3.8 Max ($10.02) and ~11% less than Kimi K3.1 Pro ($3.68): This is driven by 25% lower per-token pricing than Qwen3.8 Max, 70% cheaper cache hits and lower token usage. Tencent Hy4 costs ~3x less per task ($1.03) than Qwen4 Max but scores 8 points lower on the Index.
➤ Qwen4 Max uses 39% fewer output tokens per task than Qwen3.8 Max: ~105k output tokens per Intelligence Index task vs ~171k for Qwen3.8 Max, ~72k for Kimi K3.1 Pro and ~78k for Tencent Hy4. Qwen4 Max uses fewer tokens, while increasing 9 points on the Intelligence Index
➤ Improvements in AA-Briefcase (knowledge work): On AA-Briefcase, our evaluation of agentic work across real business files, Qwen4 Max reaches 1686 Elo vs 1674 for Kimi K3.1 Pro and 1446 for Tencent Hy4.
➤ Qwen4 Max trails Kimi K3.1 Pro on Terminal-Bench 4.0 and Tencent Hy4 on FrontierCode 2.0: Qwen4 Max scores 48% on Terminal-Bench 4.0 vs 67% for Kimi K3.1 Pro and 37% for Tencent Hy4. On FrontierCode 2.0, @cognition’s private evaluation of real-world coding tasks, it scores 26%, level with Kimi K3.1 Pro (26%) and behind Tencent Hy4 (31%).
Key model details:
➤ Context window: 1M tokens
➤ Multimodal: Text and image input with text output
➤ Pricing: $1.50/$4.50 per 1M input/output tokens on Alibaba's first-party APIs, with a $0.075 cache hit price. This is lower than Qwen3.8 Max across the board ($2.00/$6.00, with a $0.25 cache hit price)
➤ Availability: @Alibaba_Qwen 's first-party APIs
Google's new Gemini 4 Hydrogen has Intelligence just below Claude Sonnet 5.5 and GPT-6.1 Sol, at a third of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol
@GoogleDeepMind has released their third new model in six weeks. Gemini 4 Hydrogen introduces an xhigh reasoning level and scores 54 on the Artificial Analysis Intelligence Index, with strengths in visual reasoning and non-hallucination. This places it 1 point behind Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), at ~32% of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol. With high reasoning, Gemini 4 Hydrogen matches the Intelligence of Gemini 4 Argon for ~19% of the Cost per Task
Key takeaways:
➤ The new xhigh reasoning level scores 54 on the Intelligence Index: xhigh is the first reasoning level above high on a Gemini model, and puts Hydrogen 1 point below Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), and 4 points ahead of Gemini 4 Argon (high). With default (high) reasoning, Gemini 4 Hydrogen scores 51, just behind GPT-6.1 Sol (xhigh, 52) and Claude Opus 5.5 (high, 52)
➤ Strong visual reasoning, presentation and non-hallucination: On GDP.pdf, a visual reasoning benchmark over long documents, it scores 33% all-pass on medium reasoning, the tied #1 score on the benchmark. On AA-Omniscience, Hydrogen has one of the lowest hallucination rates recorded at 8%, compared with 43% for Claude Sonnet 5.5 (max) and 52% for GPT-6.1 Sol (max). On AA-Briefcase, our agentic knowledge work evaluation, graders rate Hydrogen's presentation above other Gemini models, including Carbon
➤ Weaker on agentic terminal work: Hydrogen scores 54% on Terminal-Bench 4.0 and 50% on Terminal-Bench-Science 0.1, covering agentic coding and scientific research workflows in the terminal. Claude Sonnet 5.5 (max) scores 64% and 53%, and GPT-6.1 Sol (max) scores 56% and 58%. xhigh reasoning helps on the science tasks, lifting Terminal-Bench-Science from 41% at high to 50%, but makes no difference on Terminal-Bench 4.0 (54% at both). Science scores are even across domains, from 46% in earth sciences to 53% in physical sciences
➤ Low cost for its intelligence, with high token use at xhigh: Hydrogen is priced at $1.50/$7.50 per million input/output tokens. At xhigh it costs ~32% as much per task as Claude Sonnet 5.5 (max) for near-equal intelligence, but ~2.5x as much as GPT-6.1 Sol (max). xhigh nearly doubles output tokens compared with high for a 3 point gain in Intelligence, and Cost per Task falls from $3.16 at xhigh to $1.87 at high. Medium ($0.80) and low ($0.29) cost less again, but score 41 and 27 on the Intelligence Index
➤ On the Time per Task vs. Intelligence Pareto frontier: Gemini 4 Hydrogen has an output speed of ~200 output tokens per second. With high, medium, and low reasoning effort, Gemini 4 Hydrogen is on the Time per Task vs. Intelligence Pareto frontier, meaning no models are both more intelligent and have a lower Time per Task
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Reasoning efforts: Gemini 4 Hydrogen offers four reasoning levels (low, medium, high, and xhigh) with xhigh new in this release
➤ Pricing: $1.50/$7.50 per 1M input/output tokens. Cached input tokens receive a 95% discount ($0.075)
Congratulations to the @GoogleDeepMind team on the launch!
Anthropic has released Claude Fable 5.2, taking the #1 spot on the Artificial Analysis Intelligence Index v5 at 65, led by gains in science, knowledge, and coding
At max effort it scores 65, 5 points ahead of Gemini 4 Carbon (high, 60) and 6 ahead of Claude Opus 5.5 (max, 59). Gains are driven by scientific reasoning, knowledge and FrontierCode 2.0, and roughly matching Opus 5.5 on AA-Briefcase and Terminal-Bench 4.0.
Priced at $8/$40 per 1M input/output tokens, a 20% reduction from Fable 5.1, Claude Fable 5.2 averages a Cost per Task of $26.5 with max effort, a ~2.6x increase compared to Opus 5.5 (max, $10.0) and ~2x compared to Fable 5.1 (max, $12.99)
Key takeaways:
➤ Claude Fable 5.2 leads 5 of the 9 evaluations in the Intelligence Index: At max effort, Fable 5.2 scores 65, ahead of Gemini 4 Carbon (high, 60), Claude Opus 5.5 (max, 59) and GPT-6 Astra (max, 57), and ~15 points above Claude Fable 5.1 (max, 49). It sets the highest scores on HLE-Diamond (80%, previous best 69% from Gemini 4 Carbon), AA-Omniscience v1.1 (67, previous best 54 from Gemini 4 Carbon), Terminal-Bench-Science (73%, previous best 65% from Gemini 4 Carbon), CritPt v2 hard subset (77%, previous best 72% from GPT-6 Astra) and FrontierCode 2.0 (49%, previous best 46% from Claude Opus 5.5)
➤ Less progress in agentic knowledge work and terminal coding: Claude Fable 5.2 improves on Fable 5.1 across capabilities, but sometimes only to Opus 5.5 levels. It reaches 1785 Elo on AA-Briefcase, within the confidence interval of Opus 5.5 (1800) and just behind Claude Sonnet 5.5 (1813). On GDP.pdf it reaches 24% all-pass against 26% for Opus 5.5. On Terminal-Bench 4.0 it scores 60%, level with Opus 5.5 and behind Kimi K3.1 Pro (67%), Gemini 4 Carbon (65%) and Sonnet 5.5 (64%). AutomationBench-AA is an exception, at 76% against 70% for Opus 5.5, narrowly behind Gemini 4 Carbon, 78%
➤ Lower efforts still take leading positions: With high and xhigh effort, Claude Fable 5.2 scores 62, ahead of every other model at any effort, using 98k output tokens per task against 173k for Opus 5.5 (max). At max effort Fable 5.2 costs ~2.6x more than Opus 5.5, but at lower effort settings it can outperform Opus 5.5 at lower cost per task
Other model details:
➤ Context window: 1 million tokens with image and text input
➤ Pricing: $8/$40 per 1M input/output tokens; cache writes $10 with 5-minute TTL, $16 with 1-hour TTL, and cache reads $0.20
➤ Effort settings: five (low, medium, high, xhigh, max). Intelligence Index evaluations were run at all five with Anthropic's default fallback enabled
Congratulations to @AnthropicAI on this impressive release!
✨ #Anthropic - Bağımsız Denetçi Raporu: Model Geliştirme Hızı İki Katına Çıktı
✅ Anthropic'in sınır modellerine bağımsız iç erişim hakkı bulunan araştırma kuruluşu (#METR ve bağımsız denetçiler), şirketin model geliştirme ve otonom araştırma hızına dair güncel güvenlik raporunu paylaştı.
✅ Rapora göre #Claude tabanlı araştırma ajanlarının şirket içi model mimarisi iyileştirmelerinde ve biyolojik deney analizlerinde kullanılması, geliştirme döngü hızını Ekim 2025’e kıyasla yaklaşık 1.9 katına çıkardı ve ve bu ivmenin % 80'inin yapay zekânın kendi gelişimine katkısından kaynaklandığını açıklandı
✅ Bununla birlikte denetçiler, güvenlik protokolleri gereğince halka açık raporda yer alan bazı otonom yayılım ve yetenek kanıtlarının regülasyonlar nedeniyle sansürlü (redacted) olarak sunulduğunu açıkladı.
✨ #OpenAI — "#GPT-6 #Cyber" Güvenlik Modelini Yayımladı ve #Linux Çekirdeğinde 948 #Zafiyet Bildirdi
✅ OpenAI, siber savunma ve zafiyet analizi için özel olarak eğitilmiş yeni sınır modeli GPT-6 Cyber'ı resmi olarak duyurdu.
✅ Modelin test sürecinde otonom tarama yetenekleriyle açık kaynak kod tabanları analiz edildi ve Linux çekirdeği ile çekirdek alt sistemlerinde 948 adet güvenlik açığı tespit edildi.
✅ OpenAI, sorumlu açıklama (responsible disclosure) ilkeleri kapsamında yazılım geliştiricileriyle doğrudan temasa geçildiğini ve araştırmanın yayımlandığı tarih itibarıyla bu açıklardan 61'inin upstream seviyesinde yamalandığını bildirdi.
✅ Model, güvenlik sınırlarını ve izin verilen yetki alanlarını aşmama testlerinde yüksek kontrol uyumu sergiledi.
➡️https://t.co/PBFLLWorcl
✨ #OpenAI: Veri Merkezi #Enerji Maliyetleri ve #Gizlilik Şartlarına Dair #Ulusal#Topluluk#Sözleşmesi
✅ OpenAI, artan bilgi işlem ve yapay zeka veri merkezi yatırımlarının yerel yönetimler üzerindeki baskısını azaltmak amacıyla *"National Community Compact"* adlı resmî taahhüdünü duyurdu. Şirket, sahip olduğu veya işlettiği tüm veri merkezlerinin bütün elektrik ve kamu altyapı maliyetlerini doğrudan karşılayacağını, yerel yönetimlerle yapılan görüşmelerde kamu yetkililerine gizlilik anlaşması (#NDA) imzalatma uygulamasına son verdiğini beyan etti.
➡️https://t.co/M4P1GTvLU0
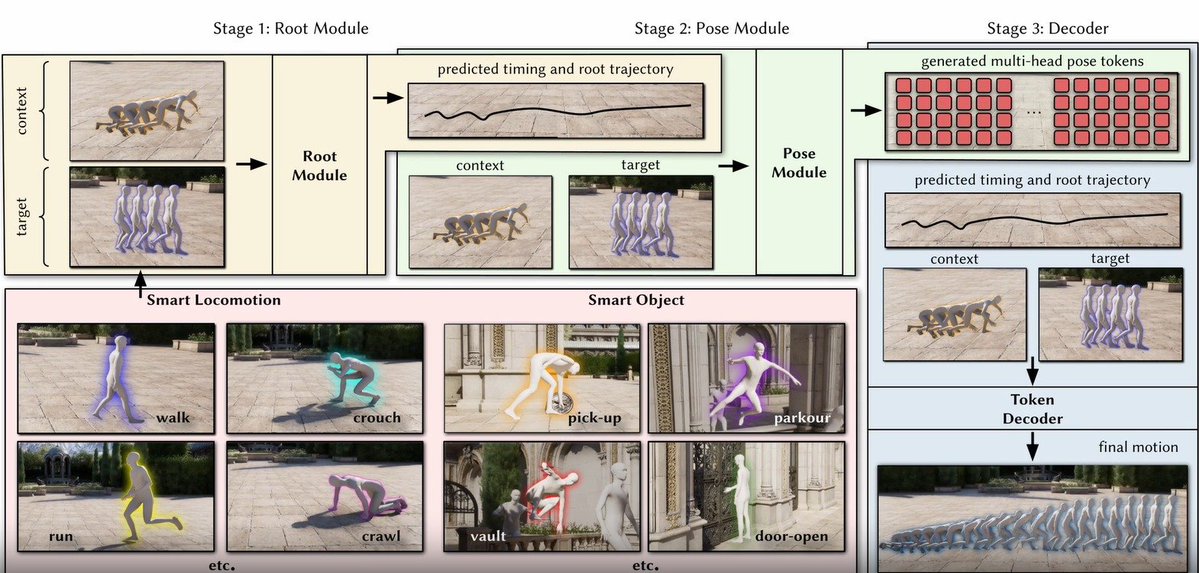
✨#NVIDIA — Gerçek Zamanlı Nöral Karakter Animasyonu Modeli "#MotionBricks"in tam sürümünü Tanıttı
➡️ NVIDIA Research (#NVlabs), oyun motorları, sanal prodüksiyon ve simülasyon ortamları için geliştirdiği yeni derin öğrenme modeli MotionBricks'in tam sürümünü resmi olarak duyurdu.
➡️ Model; kullanıcıdan veya otonom ajanlardan gelen hız, yön ve stil komutlarını anlık olarak işleyerek gerçekçi karakter hareketleri ve nesne etkileşimleri oluşturuyor. Tek bir nöral omurga üzerinden 350.000'den fazla hareket becerisini kapsayan mimari, "2 milisaniyelik" ultra düşük gecikmeyle "15.000 FPS" seviyesinde çıkarım (inference) hızına ulaşarak fizik tabanlı dijital insan animasyonlarında yeni bir verimlilik standardı ortaya koyuyor.
✅ 27 Nisan 2026: İlk önizleme
✅ Temmuz 2026: Resmi Tanıtım
✅ 23 Ekim 2026: Tam sürüm
➡️ https://t.co/Fx6vuVn0YS
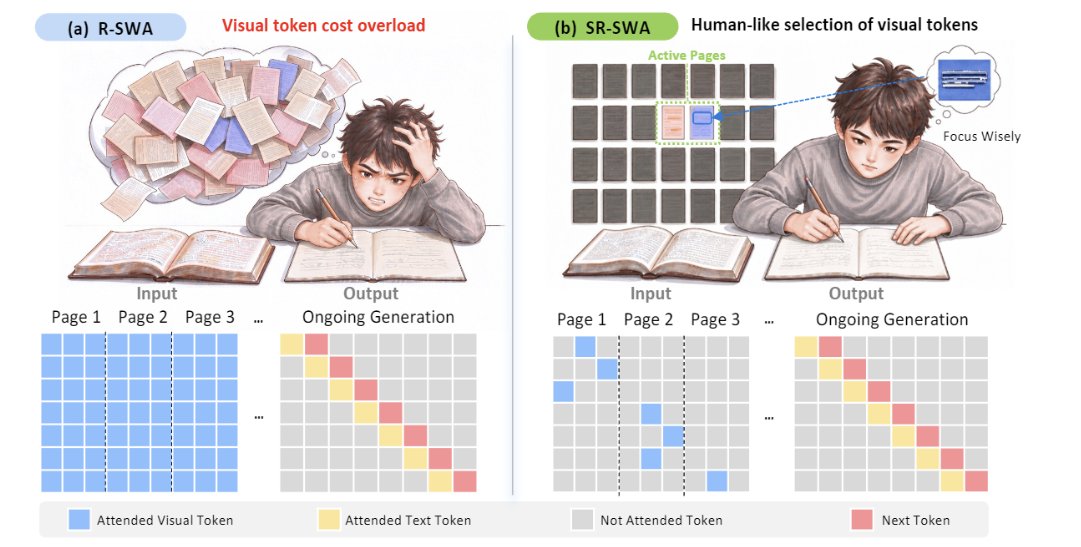
✨ #Baidu, sonsuz sayfalı belgelerin ayrıştırılmasını sağlayan #UnlimitedOCR2 modelini 27 Ekim’de açık kaynaklı hale getirdi.
✅ Bu ürün, yüzlerce sayfalık çok uzun belgeleri tek bir seferde ve bellek darboğazı yaşamadan dijital metne dönüştürebilen son teknoloji bir Görsel-Dil (Vision-Language) #OCR modeli.
➡️ Model, Uzmanların Karışımı (Mixture of Experts - #MoE) mimarisine sahip.
➡️ Toplamda 3.3 milyar parametresi bulunsa da işlem sırasında her sorgu için yalnızca yaklaşık 500 milyon parametrelik aktif bir kısmı devreye giriyor
➡️ Bu da yerel cihazlarda (örneğin dizüstü bilgisayarlarda) çalışabilmesini kolaylaştırıyor.
❗Huggingface: https://t.co/0ZpDZqF0Rt
❗Github: https://t.co/kCZQGJ7qHL
#AçıkKaynak #OpenSource
✨Bugün Resmi Gazete'de yayımlanan atamaları, ücretsiz olarak yayımlanan "Kamu Kurumları Teşkilat Haritası"ndan takip edebilirsiniz:
➡️ https://t.co/ZG6F28tzTW
#KKTH#Atamalar#ResmiGazete#Kamu
✨Resmi Gazete’de yayımlanan Cumhurbaşkanlığı Kararnameleri ile aşağıdaki birimler kuruldu:
✅ (CBK 201)
➡️ Enerji ve Tabii Kaynaklar Bakanlığı
Bilgi Teknolojileri Genel Müdürlüğü
➡️ İçişleri Bakanlığı
112 Acil Çağrı ve Koordinasyon Genel Müdürlüğü
➡️ Sanayi ve Teknoloji Bakanlığı
Bilgi Teknolojileri Genel Müdürlüğü
✅ (CBK 203)
➡️ Siber Güvenlik Başkanlığı
İletişim Sistemleri Genel Müdürlüğü
Kamu Kurumlarının güncel idari yapılanmalarını, ücretsiz olarak yayımlanan "Kamu Kurumları Teşkilat Haritası"ndan inceleyebilirsiniz:
📷 https://t.co/3Cb1cev2xV
#KKTH #İdariYapılanma
✨#Google'dan Yörüngedeki #YapayZeka Çipinden (Project #Suncatcher) İlk Başarılı Çıkarım
✅Google, #uzay tabanlı bilgi işlem ve #uydu iletişim mimarisi kapsamında yörüngeye yerleştirilen yapay zeka hızlandırıcısının (#TPU) uzay ortamında ilk kez harici bir istemi (#prompt) başarıyla işleyerek dünyaya yanıt ilettiğini bildirdi.
✅Bu başarı, karasal veri merkezleri üzerindeki #soğutma ve #elektrik yükünü hafifletmeyi hedefleyen ve 2027'de devreye alınması planlanan uydu çifti projesinin ilk somut operasyonel testi olarak kayıtlara geçti.
➡️ Google'ın 30.10.2026 tarihli Duyurusu:
https://t.co/MY8TIqIij8
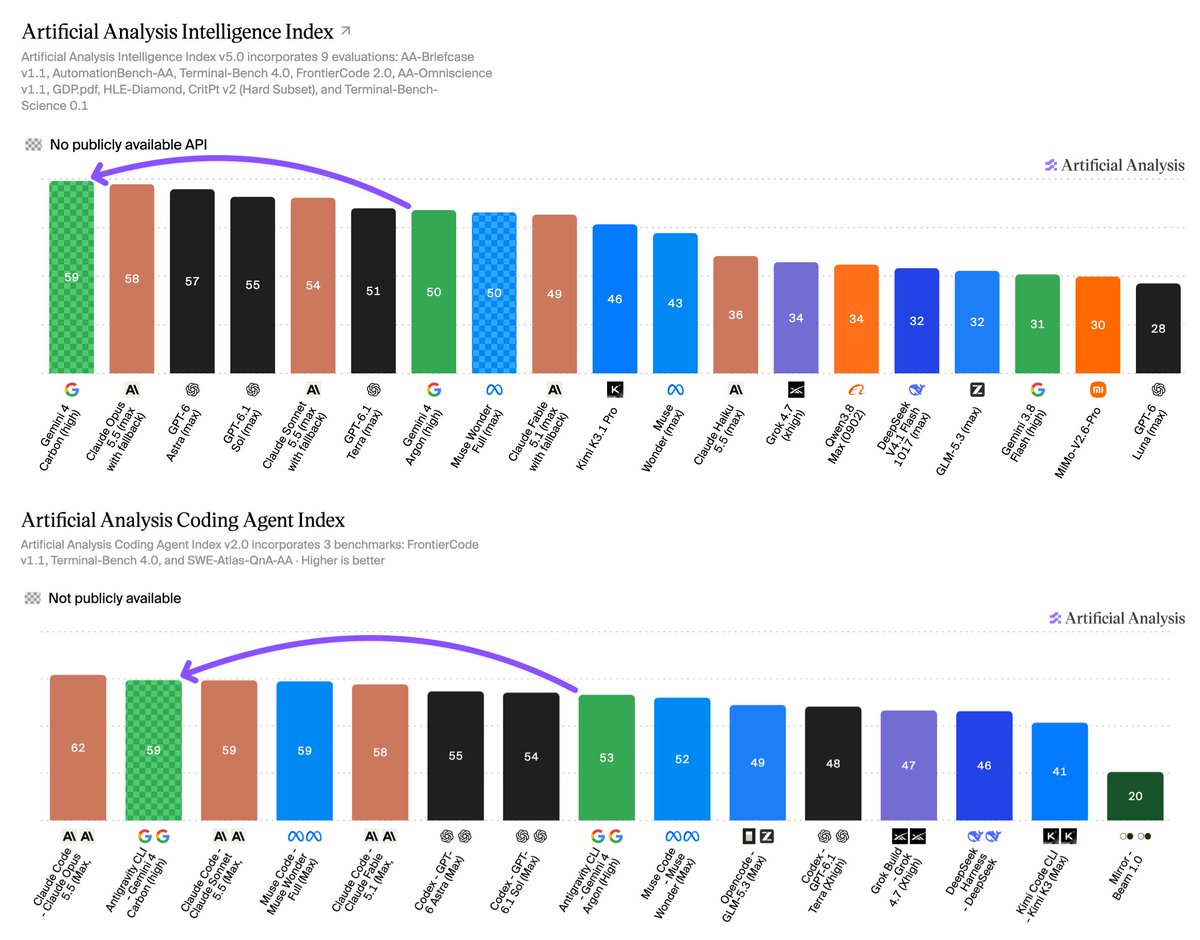
I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!
✨ Bütün Bakanlıkların #2027 yılı ve önceki yıllardaki bütçelerini, ücretsiz olarak yayımlanan "Kamu Kurumları Teşkilat Haritası"ndan inceleyebilirsiniz:
➡️ https://t.co/ZG6F28t24o
#KKTH#Atamalar#Bütçe#Kamu #2027
✨ #OpenAI ve #Anthropic Destekli "AI Biyogüvenlik Laboratuvarı" (UK AI Biosecurity Lab) Kuruldu
#BirleşikKrallık Hükümeti; OpenAI ve Anthropic ortaklığıyla biyolojik tehditleri önceden tespit etmek, patojen yayılımını modellemek ve aşı geliştirme süreçlerini hızlandırmak amacıyla "AI Biosecurity Lab" girişimini resmi olarak duyurdu.
Hükümetin 100 milyon sterlinlik kamu kaynağının yanı sıra OpenAI ve Anthropic, projeye gelişmiş yapay zeka modelleri ve bilgi işlem kapasitesi olmak üzere toplamda 200 milyon sterline varan kaynak taahhüdünde bulundu.
https://t.co/Rjm61mKUBe
#YapayZeka #AI #Biosecurity
Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index scoring 55, making large gains in agentic performance; it will be the leading open-weights model once its weights are published
@Kimi_Moonshot's new reasoning model gains 11 points over Kimi K3 (max, 44). It trails only Claude Opus 5.5 (max with fallback, 58), Claude Sonnet 5.5 (max with fallback, 56), and Muse Wonder Full (max, 56) on the Intelligence Index.
Once the weights for K3.1 Pro are released it will be the highest-scoring open weights model and the gap between the leading open weights and proprietary models on the Intelligence Index will narrow from 12 points to 3.
Key results:
➤ Large gains in agentic performance: Kimi K3.1 Pro scores 3rd on GDPval-AA with 1,846 Elo, up 312 Elo from Kimi K3, behind only Claude Opus 5.5 (1,866 Elo) and Muse Wonder Full (1,857 Elo). Kimi K3.1 Pro also achieves the highest score of any model on Terminal-Bench 4.0. K3.1 Pro scores 67%, up from 13% for Kimi K3 and ahead of Claude Sonnet 5.5 (64%). AutomationBench-AA, which tests agentic SaaS workflows, rises from 58% to 73%.
➤ Gains in other evals are more moderate: Humanity's Last Exam rises from 47% to 52%, CritPt from 23% to 25%, and SciCode from 59% to 61%. AA-Omniscience Index rises from 20 to 30, as the hallucination rate falls from 53% to 44% and accuracy rises from 48% to 51%.
➤ Cost per Task roughly equal to Kimi K3 at $1.98 per Task: K3.1 Pro uses 55K output tokens per Intelligence Index task, 14% more than Kimi K3 at 48K, while its first-party token prices are 33% lower.
Additional model details:
➤ Context window: 1M tokens.
➤ Size: 2.8T total, 104B active parameters
➤ Input modalities: Text and image
➤ Weights and license: Weights currently not published, Moonshot is expected to release the weights soon after launch
➤ Pricing: $2/$10/$0.20 per 1M input/output/cache hit tokens, 33% lower than Kimi K3 on all three rates.
Congratulations to the team at @Kimi_Moonshot on the release!