🚨Our new paper is out: Model Casting and Low-Parameter Gating: Towards More Sparsely Activated FFNs
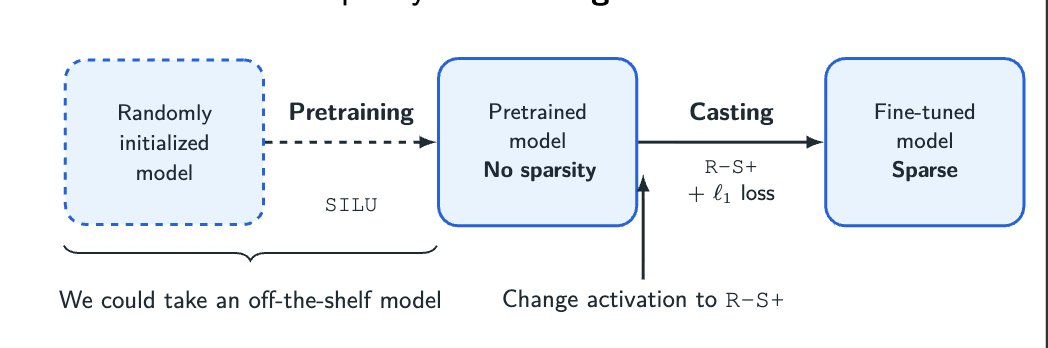
We present model casting, a mid-training recipe that drastically sparsifies the activations within the FeedForward Network layer of a transformer. Model casting consists of switching to an activation that outputs zeros for all negative inputs (R-S+) and using an L1 loss to set the required sparsity as a target at training time.