���Google AI Ultraが1年無料でもらえる」という投稿とリンクが広まっていますが、Google公式のキャンペーンではありません
出回っているリンクの正体は、誰かのGoogle One申し込み画面から抜き出されたトークン付きの決済URLです
ドメインが本物のGoogleでも、公式に配られたリンクではありません
Google AI Ultraは月14,500円(20TB)からの有料プランで、1年無料になる公式オファーは見当たりません
非公式のリンクで有効になったように見えても、あとから取り消される可能性があります
申し込み画面のURLなので、正規料金の請求やアカウント停止といったリスクも否定できません
元の投稿者もサブアカウントで試したと書いてい��、メインのアカウントで使うのはおすすめしません
すでに使ってしまった人は、Google Oneの設定やhttps://t.co/e9GxFuVoGVの「サブスクリプションとサービス」で今のプランと請求予定を確認し、不要なら解約しておいてください
https://t.co/1NomEvariI
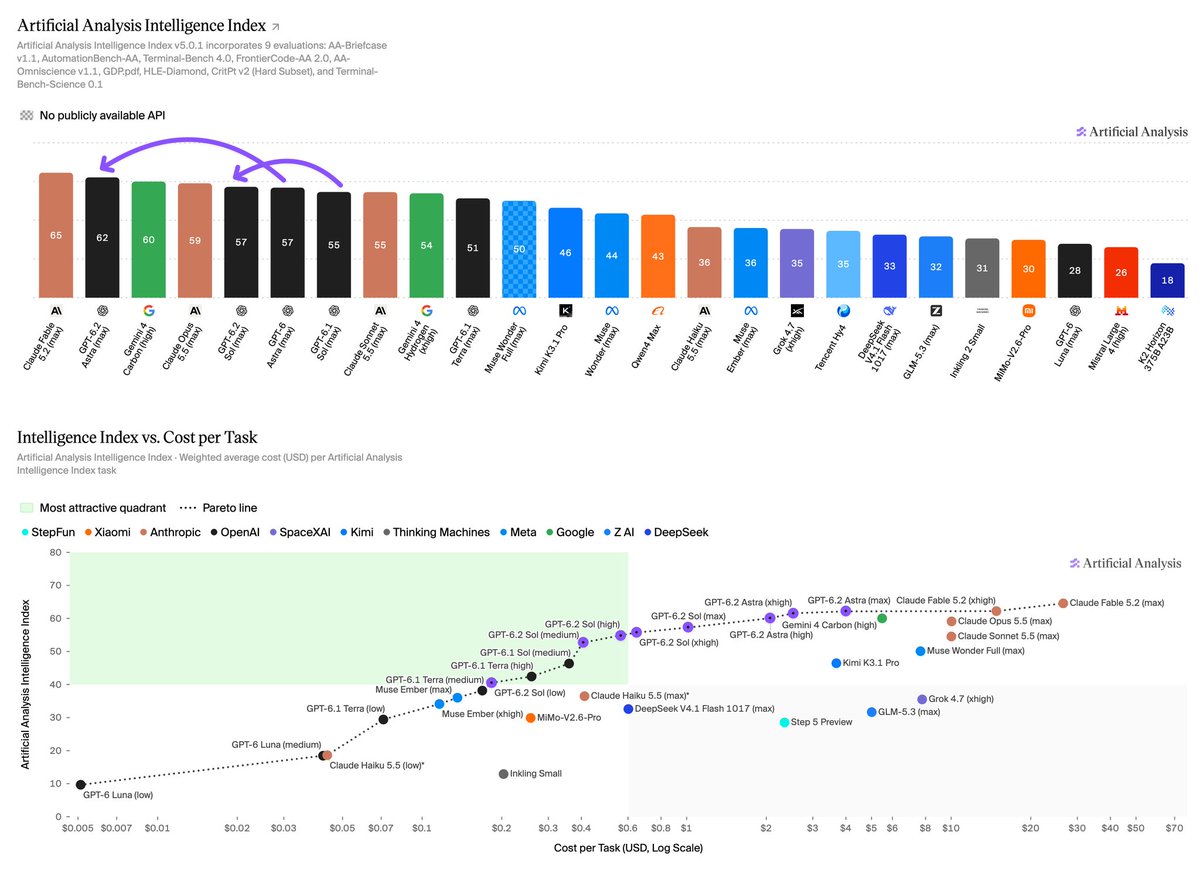
OpenAI’s release of GPT-6.2 Astra and GPT-6.2 Sol delivers the #2 model in the Artificial Analysis Intelligence Index and most of the Cost per Task Pareto frontier
@OpenAI's GPT-6.2 Astra is priced at $8/$40, 20% below GPT-6 Astra, and cached input drops to $0.40 from $1.00 per million tokens. GPT-6.2 Sol pricing is unchanged from GPT-6.1 Sol, at $2/$10 per million input/output tokens.
Key takeaways:
➤ Second in Intelligence Index: OpenAI now trails only Anthropic’s Claude Fable 5.2 in the Artificial Analysis Intelligence Index. GPT-6.2 Astra jumps 5 points from GPT-6 Astra, overtaking Gemini 4 Carbon (60) and Claude Opus 5.5 (59) at their top effort settings. GPT-6.2 Sol gains 2 points at 57, placing it on par with GPT-6 Astra at ~15% of the Cost per Task.
➤ Occupies most of cost and output token frontiers: OpenAI models now occupy most of the Cost per Task Pareto frontier, sharing the frontier with only Anthropic and Meta. OpenAI also dominates the Output Token per Task Pareto Frontier, with Claude Fable 5.2 being the only model from a non-OpenAI lab appearing on the frontier.
➤ Strengths in science and knowledge: OpenAI performs strongly in both of our key science-focused evaluations, leading Terminal-Bench-Science 0.1, covering agentic scientific research workflows, and placing second only to Claude Fable 5.2 in CritPt v2 (hard subset), covering physics reasoning. GPT-6.2 Astra performs below only Claude Fable 5.2 in factual knowledge as measured by AA-Omniscience v1.1 Accuracy, and in HLE-Diamond, a reasoning and knowledge benchmark.
➤ Leading in 3D and robotics: GPT-6.2 Astra leads AA-3D at 1318, with Claude Fable 5.2 at 1271 and GPT-6.2 Sol at 1259. This benchmark measures how well models build interactive 3D experiences, and is rated by human graders. GPT-6.2 also leads AA-Robotics v0.1, our research preview measuring how well language models can understand, plan, and act in the real world. GPT-6.2 Astra and GPT-6.2 Sol scored 79 and 78 respectively, ahead of Claude Fable 5.2 at 75. Our team is hard at work adding more difficult tasks, as OpenAI and Anthropic models can now perform the majority of basic tasks in this initial research preview.
➤ No improvement in Coding Agent Index: GPT-6.2 Astra is flat with GPT-6 Astra, and GPT-6.2 Sol loses 3 points relative to GPT-6.1 Sol in the Artificial Analysis Coding Agent Index (Codex harness at max effort). For Sol, the drop is driven by a 14-point drop in SWE-Atlas-QnA-AA, where the model is more likely than its predecessor to omit key facts in its responses. Cost efficiency however does place several effort levels of GPT-6.2 Astra and Sol on the Pareto frontier for Cost per Task.
【📢 注目!AIにプロジェクト丸ごと点検させる一文】
散らかったフォルダやコード、どこから直すか迷っていませんか?
Anthropicのアレックス・アルバート氏が、Xでシンプルな「AIへの指示文(プロンプト)」を紹介しました。新しいAIモデルが出るたびに、自分の全プロジェクトで同じ指示文を実行しているそうです。「ぜひ試して」とも勧めています。(個人のX投稿であり、公式機能の発表ではありません)
📝 指示文(英語の原文)
"Read this entire project and find everything that's broken, inconsistent, inefficient, or no longer needed. Fix what you're sure about and list the rest for me to review."
📝 日本語訳(意訳)
「このプロジェクト全体を読んで、壊れている所・ちぐはぐな所・ムダな所・もう要らない所を全部見つけて。確実な所は直して、残りは私が確認できるようにリストにして」
🗣️ 要点
・①全体を読ませる
・②4種類の問題(壊れている/ちぐはぐ/ムダ/もう不要)を探させる
・③確実な所だけ直させる
・④迷う所は直さず、リストにして人が判断する
📊 反響
この投稿は確認時点(11/10 17時頃)で、ブックマーク約1.3万、いいね約6,800でした(数字は変動します)。
🤔 私たちにとっては?
コピペで試せるのが強みです。プログラムだけでなく、資料やメモのフォルダ整理にも同じ考え方が使えそうです(これは使い方のヒン��で、本人の発言ではありません)。ただし、AIが直した所は最後に人が確認することが大事。X上でも同じ声が多いようです(Xの話題まとめ���ース)。
あなたはどっち派?👇
A:AIに丸ごと点検させたい
B:自分の目で確認してから直したい
#AI #プロンプト #生成AI
▶ Xをフォローで毎日チェック!
YouTubeもやってるので、プロフ欄からご覧ください