@Koukoumidis That's a nice take. I think the question is increasingly becoming not “Which model should we use?” but instead “What intelligence should we own?”
What most people get wrong is that you don't need that much compute to run large AI models. We can fit an entire 8 billion parameter LLM on a laptop RTX 3070 with 4-bit quantization.
Transformers summed up in 3 sentences:
Transformers take "tokens" as input. Through attention, they have the ability to look back at earlier tokens. This allows them to understand context and deal with longer sequences.
Most "AI breakthroughs" we see are just corporations rebranding statistical models that have been around for years. The marketing department is working harder than the engineers.
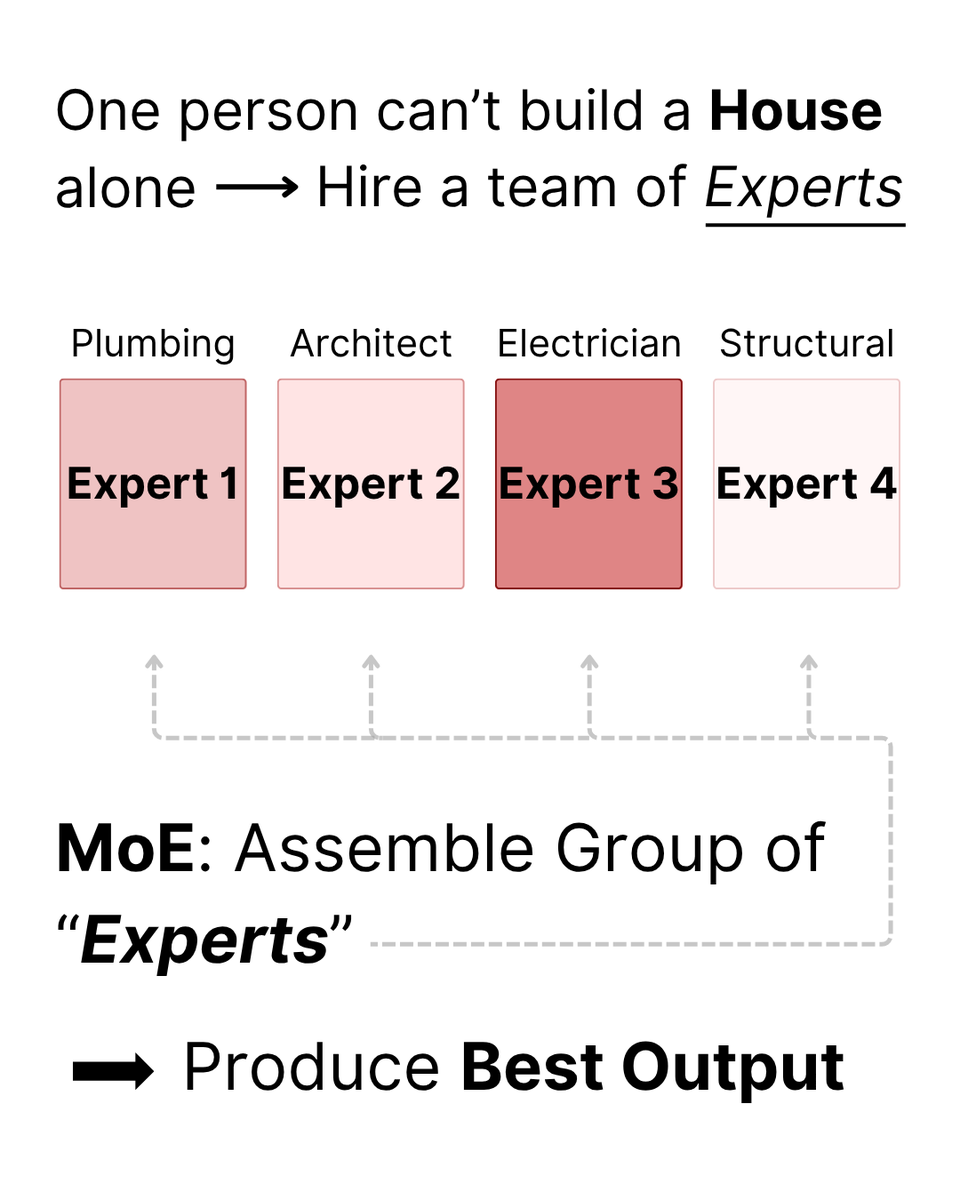
Mixture of Experts (MoE) models scale efficiently without sacrificing performance.
Like ensemble models, they combine different FFNs termed "experts" for the best output.
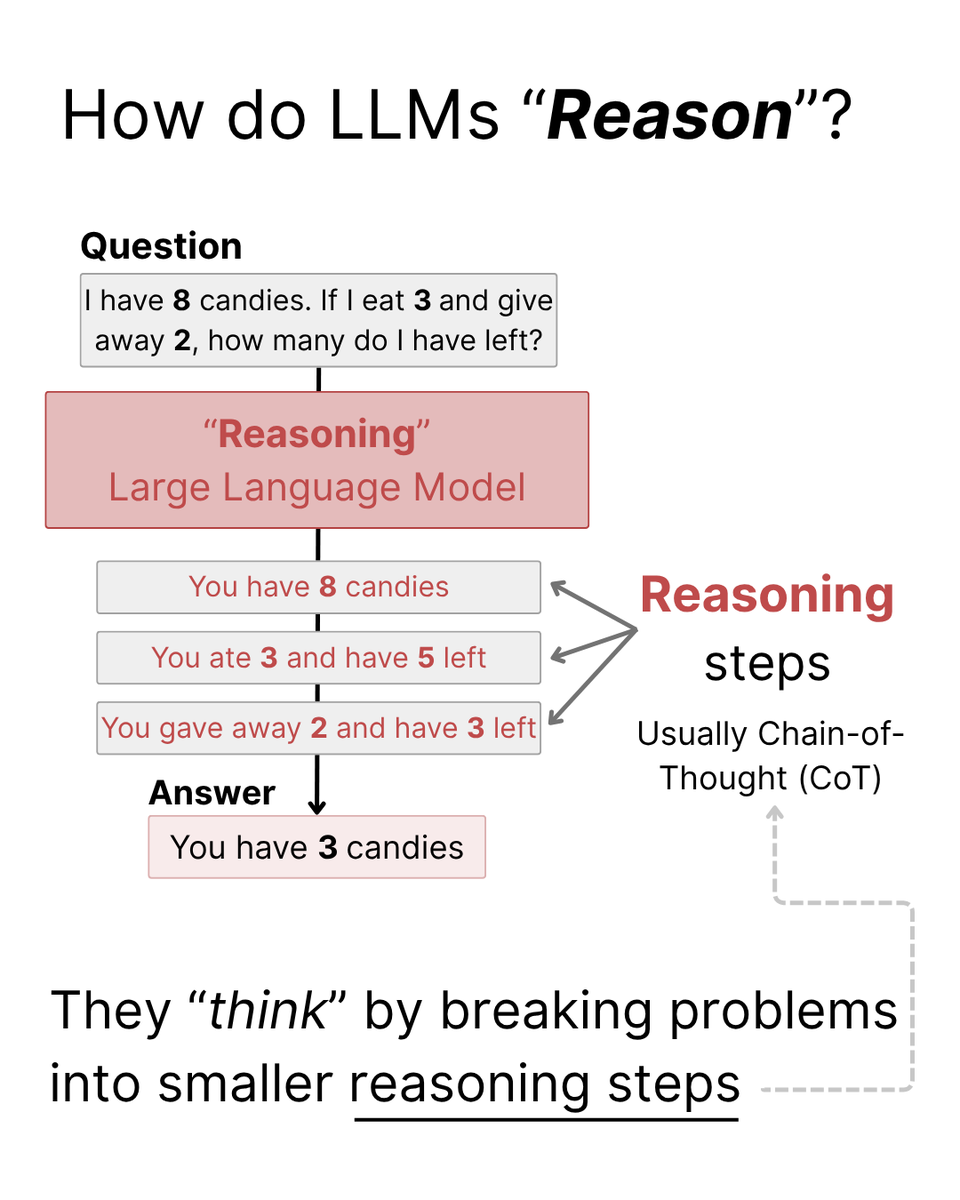
Reasoning large language models (LLMs) appear to “think” by breaking a more complex prompt down into smaller steps, resulting in intermediate steps before an output.
These steps are called "reasoning steps" or "thought processes".