Hy4-Flash is now supported in Strata 🙌
It has its own .strata quantisation checkpoints at 64GB, 96GB, and 128GB. You can run it with at least an 8GB GPU. A preview of something bigger I'm doing for local inference in the next few days.
@TencentHunyuan Hy4-Flash is a great model with some good long-horizon agentic tasks.
See more at: https://t.co/AU2SCnJ02H
Kokoro-Engine
Desktop AI characters with a voice and long-term memory
Live2D characters can track your gaze and respond with actions in a floating desktop window. Speech recognition and voice synthesis are part of the same runtime.
Characters, conversations, summaries, and long-term memories are stored locally in SQLite. It supports Ollama, llama.cpp, and OpenAI and Anthropic compatible APIs.
You can import SillyTavern character cards, build UI themes with HTML/CSS/JS, and add behavior through MOD scripts.
https://t.co/d5B8Jv0VLM
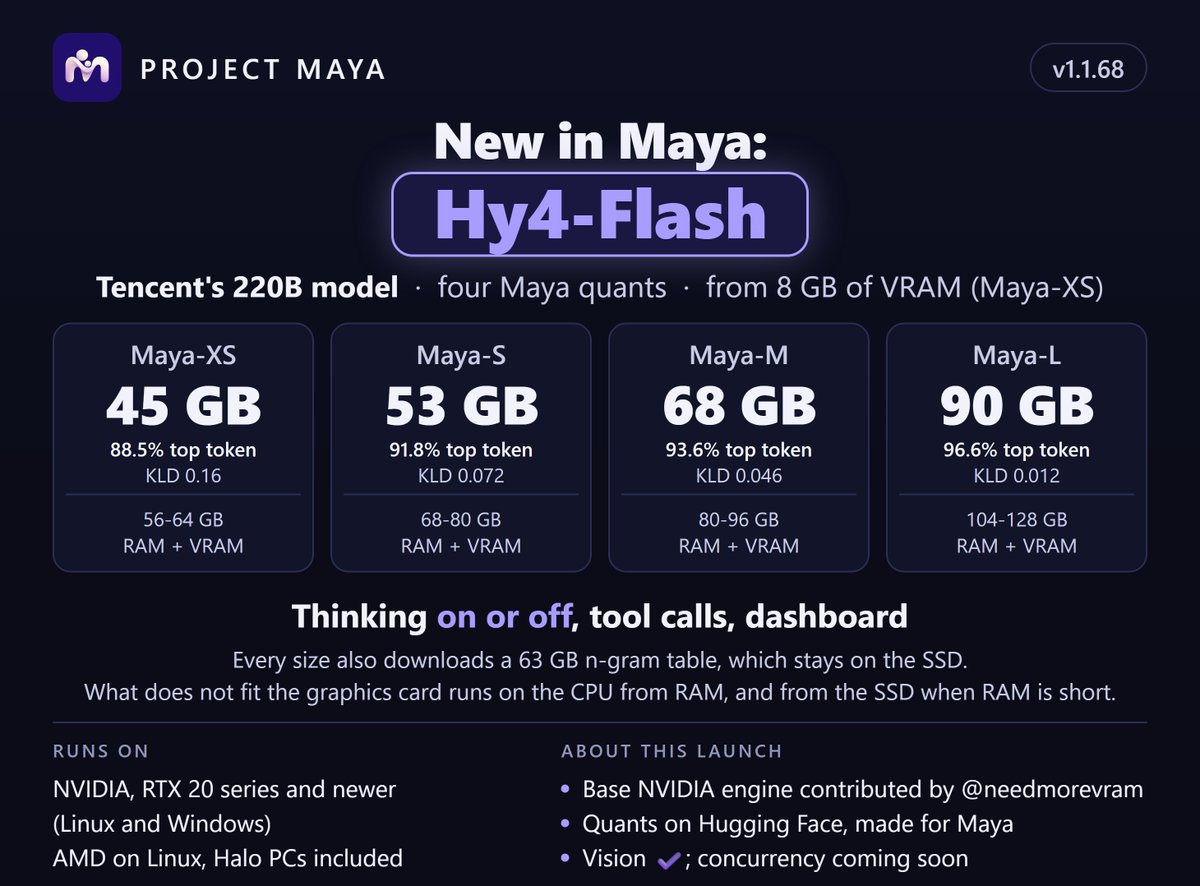
Tencent's 220B Hy4-Flash now runs on a home PC with an 8 GB graphics card. 🚀
Maya v1.1.68 is out, with four quants we made ourselves for @TencentHunyuan's new model. Each one is measured against the full-precision original:
Maya-XS · 45 GB · 88.5% same top token
Maya-S · 53 GB · 91.8%
Maya-M · 68 GB · 93.6%
Maya-L · 90 GB · 96.6%
How does 220B fit? What doesn't fit the graphics card runs on the CPU from RAM, what doesn't fit RAM streams from the SSD, and the model's 63 GB n-gram table stays on the SSD.
✅ Drafting: the model checks every drafted token
✅ Vision, thinking on or off, tool calls
✅ NVIDIA RTX 20 series and newer on Linux and Windows
✅ AMD on Linux, Strix Halo and Gorgon Halo included
✅ One setup command picks the size and context that fit your PC
Which one will you pick?
Full notes 👇
https://t.co/sM5YLvEjTM
OpenAI Dots & GrokBot alternative running fully locally!! It uses PolyStrata (Strata engine) to serve and swap the models it needs and, of course being fast 😎
Check out more here: https://t.co/UhTBHPeXib