If the app you're using hosted on someone else's cloud is free or nearly free, the product for sale is you. If you're into all the AI agent apps, don't forget it
Played with Qwen3.8 Flash Next and @pidotdev on my 64GB Mac, as a result I have another episode of "Vibe reversing" ready 🙃 The crackme was quite simple, but I was surprised to see how well the agent behaved (also ran the exe w Unicorn + wrote a keygen!) https://t.co/2gbPgwVAgZ
Qwen3.8 Flash Next is now supported in DwarfStar, covering 64GB Mac systems very well and with very fast inference of 50~70 t/s and > 1400 t/s prefill. For now this is Metal only. Thanks to @ivanfioravanti for all the cool work in the PR. N-grams on SSD like for DS4.1F.
@antirez Cool! I'd love to play with similar optimisations on smaller models. I replicated with qwen3.8:27B on an M4 max (TG 21t/s) and a 3.5:9B on a Steam Deck (11t/s) and while answers are already more than decent (the 9b even got Blue Marble!) they could benefit from a speed-up
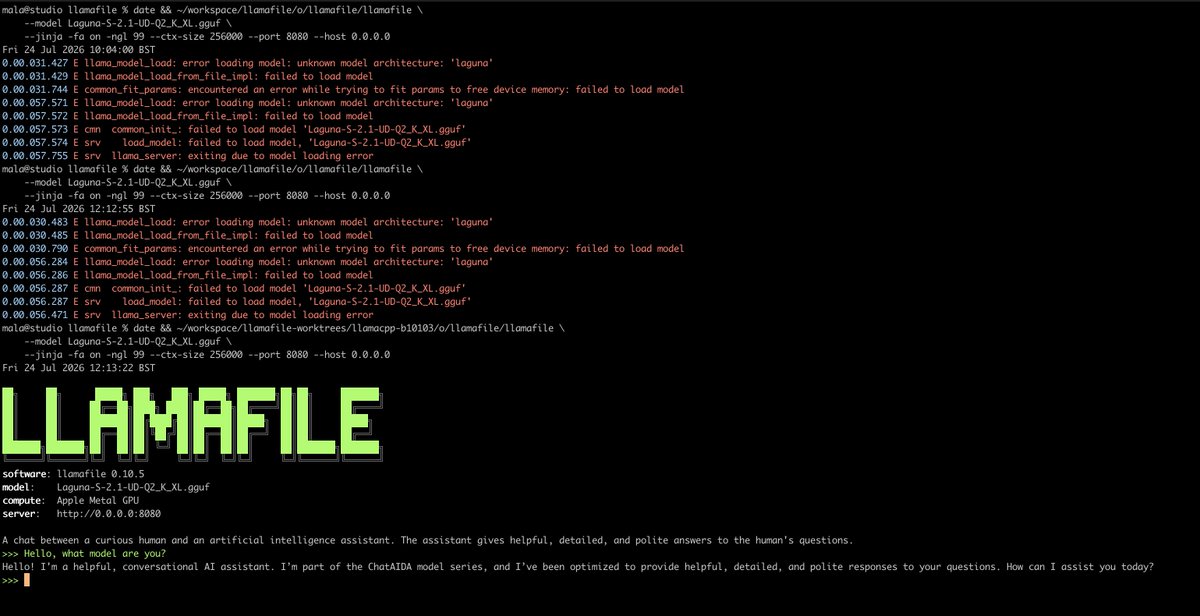
Weekend project: I started working on a new llamafile release (0.10.6 ) with support for MuseGlimmer:30B and Qwen3.8:27B. Yesterday I uploaded WIP llamafiles in the alpha HF repo https://t.co/JJu3NHhKT6 in case you want to play with them 🙃 (metal+linux cuda and vulkan only atm)
How do you reduce your reliance on subscription plans and token subsidies if you're not actively measuring how much you benefit from them? Awareness is the crucial first step for change
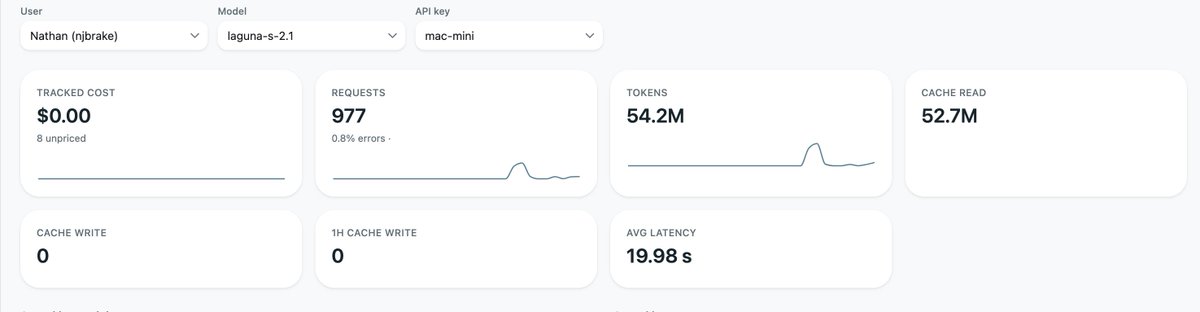
Over the past week I've used the @poolsideai Laguna S 2.1 model for 54 million tokens of work, almost 1000 requests (all running through @pidotdev and @AgentofEmpires 🚀) Probably saved me about ~$50 of API Costs. (tracked via @MozillaAI's otari)
Right now I'm using it almost exclusively as an orchestrator agent: I work with it to launch and monitor a fleet of coding agents (Opus 4.8). It is something that I used to use Claude code to do, but the Laguna model is completely capable of doing this for the unbeatable price of ~$0.00.
Human coders can't think of all the edge cases, AI coding agents can't forecast all the edge cases: users find the edge cases. Users reporting and helping fix them are what makes open source software still an unstoppable force in 2026.
@vRobM Re: sarcasm, sorry! I just wanted to let you know I had completed it without spoiling the fun to others... And since I checked the source and found email addresses were not actually saved, I thought this could have been a good proof. Glad you liked the ch35t idea! 💙
@vRobM Done! I love how ppl will wait forever to be contacted 😜
If you like riddles you might be interested in https://t.co/8I41Ky9r1W. It is not a single game, but rather a way you can share what you create in a more resilient way (simple json data files, that I hope will outlive me)
@vRobM@jartine And feel free to reach out either (or both!) here or directly on github discussions / issues. I am happy to hear suggestions on how to improve it! 🙏
@vRobM@jartine Hi Rob, sure! And TYSM for sharing your appreciation, ppl easily running agents on their own hardware is what all this is about 💙
--mmproj points at multimodal projector weights (those used for e.g. images/sound), and --help returns the full llama.cpp param list (from v0.10.4)