🥳Very proud of this work
Adding this extra loss of predicting the distance of upcoming tokens yields better models of comparable size, compared to using only the typical next token prediction
Read more: https://t.co/zid62pmgGY
Amazing work by @zmkzmkz@erla_ndpg@mbzuai
PREPRINT:
Predicting the Order of Upcoming Tokens Improves Language Modeling
Instead of just predicting the next token, what if an LM also learns to rank the proximity of all future tokens?
🔝 Introducing Token Order Prediction (TOP), an LM auxiliary loss to improve upon MTP
Jev taking off has been a pretty surreal full-circle moment
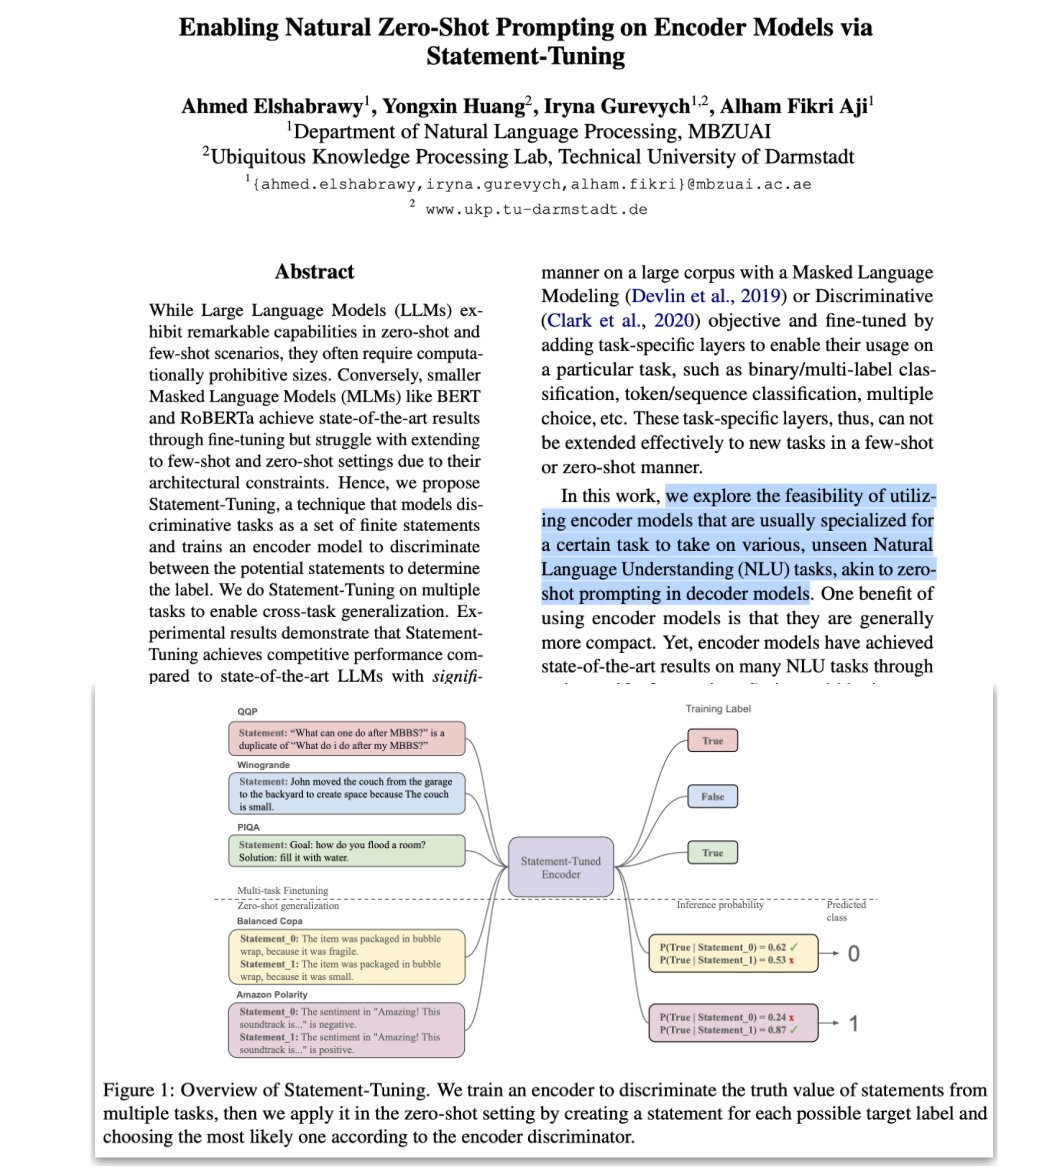
~2 years ago, we introduced Statement Tuning: train encoder models to produce decision probabilities as a lightweight alternative to generative LLMs for zero-shot classification tasks
Awesome to see a similar idea productized & taken this far
@CompleteSkeptic@typesafeai huge respect for what you’ve shipped. Would love to compare notes
Paper:
https://t.co/TRJ604hyx3
Crosslingual extension:
https://t.co/Mnq38zdRMt
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
@rdmakbar I did, they did not care... My last Schengen to Austria gave me multiple entry 3 months, despite me not asking. Maybe some countries are more 'stingy'
I was hoping to get a longer Schengen visa validity so I could use it for EACL, but I only got 20 days, despite this not being my first time visiting Schengen countries.
Strong passport privilege is real. So much wasted time and money for practically every conference trip😂
@zmkzmkz Back then the training data were template-based, similar to the early finetuning instruction / SFT data (eg. P3).
Now SFT data is more diverse, so then probably if the statement tuning data is more diverse, it can generalize better. LLMs can probably be used to generate those
@patrickamadeus_ Hmm, so nowadays people still use massive LLM for llm-as-a-judge purposes. I wonder if we should train encoder-based general purpose judge model or rubric scoring model that can take any rubric/prompt
@zmkzmkz Frankly we aren't the first to do zero-shot with encoder models, but we really focused on making it dead simple. No network modifications or weird inference tricks required. Just prompting
@rayendito@zmkzmkz I think they did a great job on scaling and adding multimodal support, but yeah, I suppose scaling (data/model) is almost a guaranteed way to improve performance
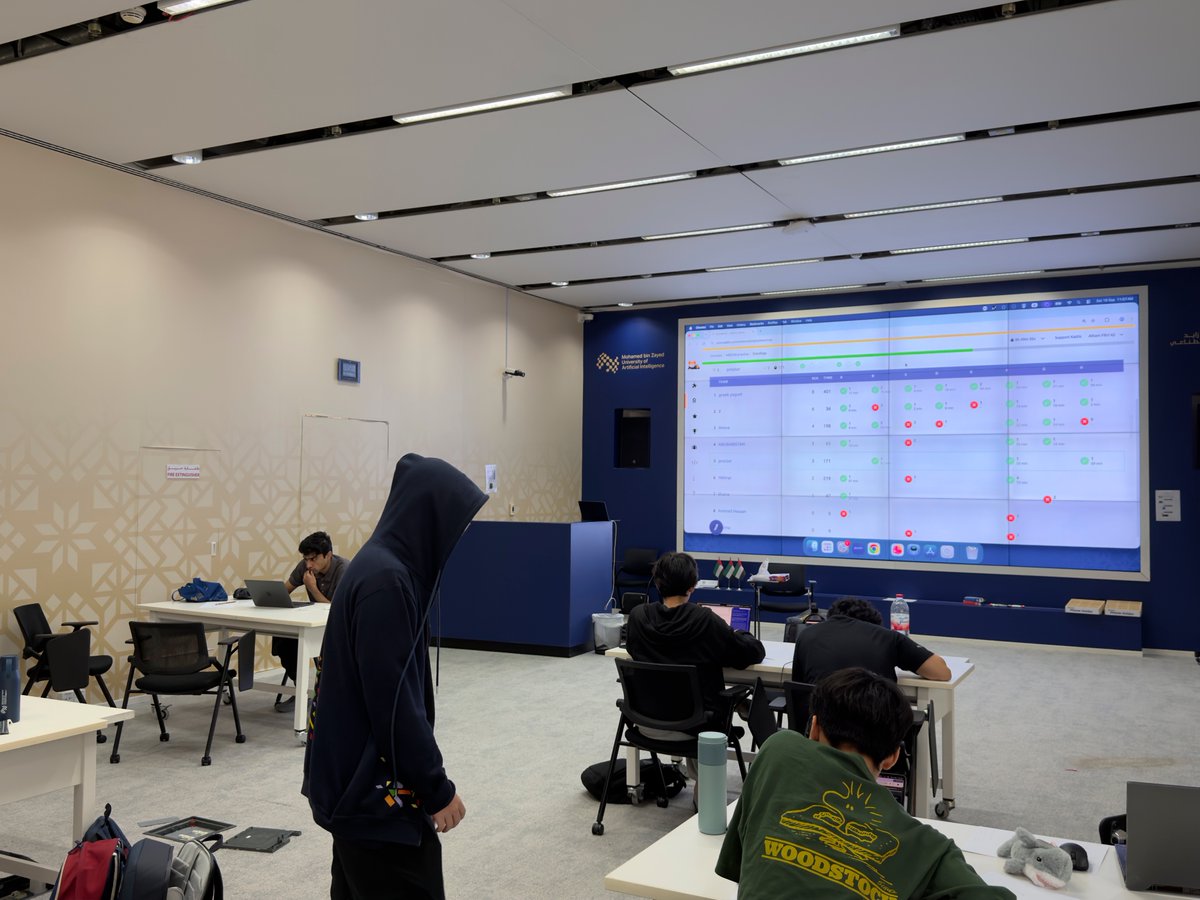
It’s that time of year again! Getting @mbzuai’s ICPC team ready for the season ahead
Last year, we won silver at the regional championship and qualified for the World Finals. This year, let’s aim even higher!
Exciting day for NVIDIA and @huggingface.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty. They allow every developer, startup, university, industry and country to build with, customize and benefit from AI.
Thank you @ClementDelangue for coming to me.
NVIDIA is going to be a great home for Hugging Face, its community and the future of open models. 🤗
https://t.co/q8Om2Xc5ye